الذكاء الاصطناعي التوليدي • مبتدئ⏱️ 20 دقيقة للقراءة
10 AIGC Use Cases
10 حالات استخدام: ما الذي يمكن أن تحققه نماذج AIGC مفتوحة المصدر؟
نمذج توليد الصور والفيديو الأكثر قوة في الوقت الحالي هما على الأرجح GPT Images 2.5 و Seedance 2.5، مما يدفع حدود التوليد إلى الأمام.
إذا كنا نعتبرهما الطراز الأول من النماذج ذات المصدر المغلق، فما هو مستوى النماذج مفتوحة المصدر اليوم؟ هل هي مجرد ألعاب؟ هل يمكنها حقًا تقديم إنتاجية حقيقية؟
يعرض هذا المقال مباشرة ما يمكن للخبراء تحقيقه مع النماذج مفتوحة المصدر، باستخدام Z-Image من Alibaba لتوليد الصور و MiniMax H3 لتوليد الفيديو.
مقدمة في هذين النموذجين
Z-Image هو نموذج توليد صور بـ 6 مليار معلمة، مشترك تحت ترخيص Apache 2.0. النموذج الكامل Z-Image هو نموذج أساسي غير مقشر يدعم CFG والarmac السلبي والضبط الدقيق؛ المجتمع يستخدم بشكل أكثر شيوعًا Z-Image-Turbo، الذي يستخدم 8 خطوات فقط ويولّي الأولوية للسرعة.
MiniMax H3 هو نموذج توليد صوت وفيديو بـ 33 مليار معلمة، يمكنه إخراج مقاطع فيديو من 4 إلى 15 ثانية، بسرعة 24 إطارًا في الثانية، مع صوت ستيريو. بدقة، هو نموذج أوزان مفتوحة باستخدام MiniMax H3 Community License. The open-sourced H3-Base can generate 768p audio-video locally, but the official Context-IR module responsible for understanding complex inputs and the 2K regeneration pipeline have not been fully open-sourced.
Z-Image: أكثر من مجرد رسم وجوه جميلة
الكثير من نماذج توليد الصور اليوم يمكنها توليد وجوه جميلة. Looking at a single retouched face is honestly not that impressive. The truly difficult tasks are: Is the text written correctly? Is the count accurate? Can the same product maintain consistency across different views? Are complex spatial relationships understood correctly?
Let's first look at a set of local tests by @witcheer.
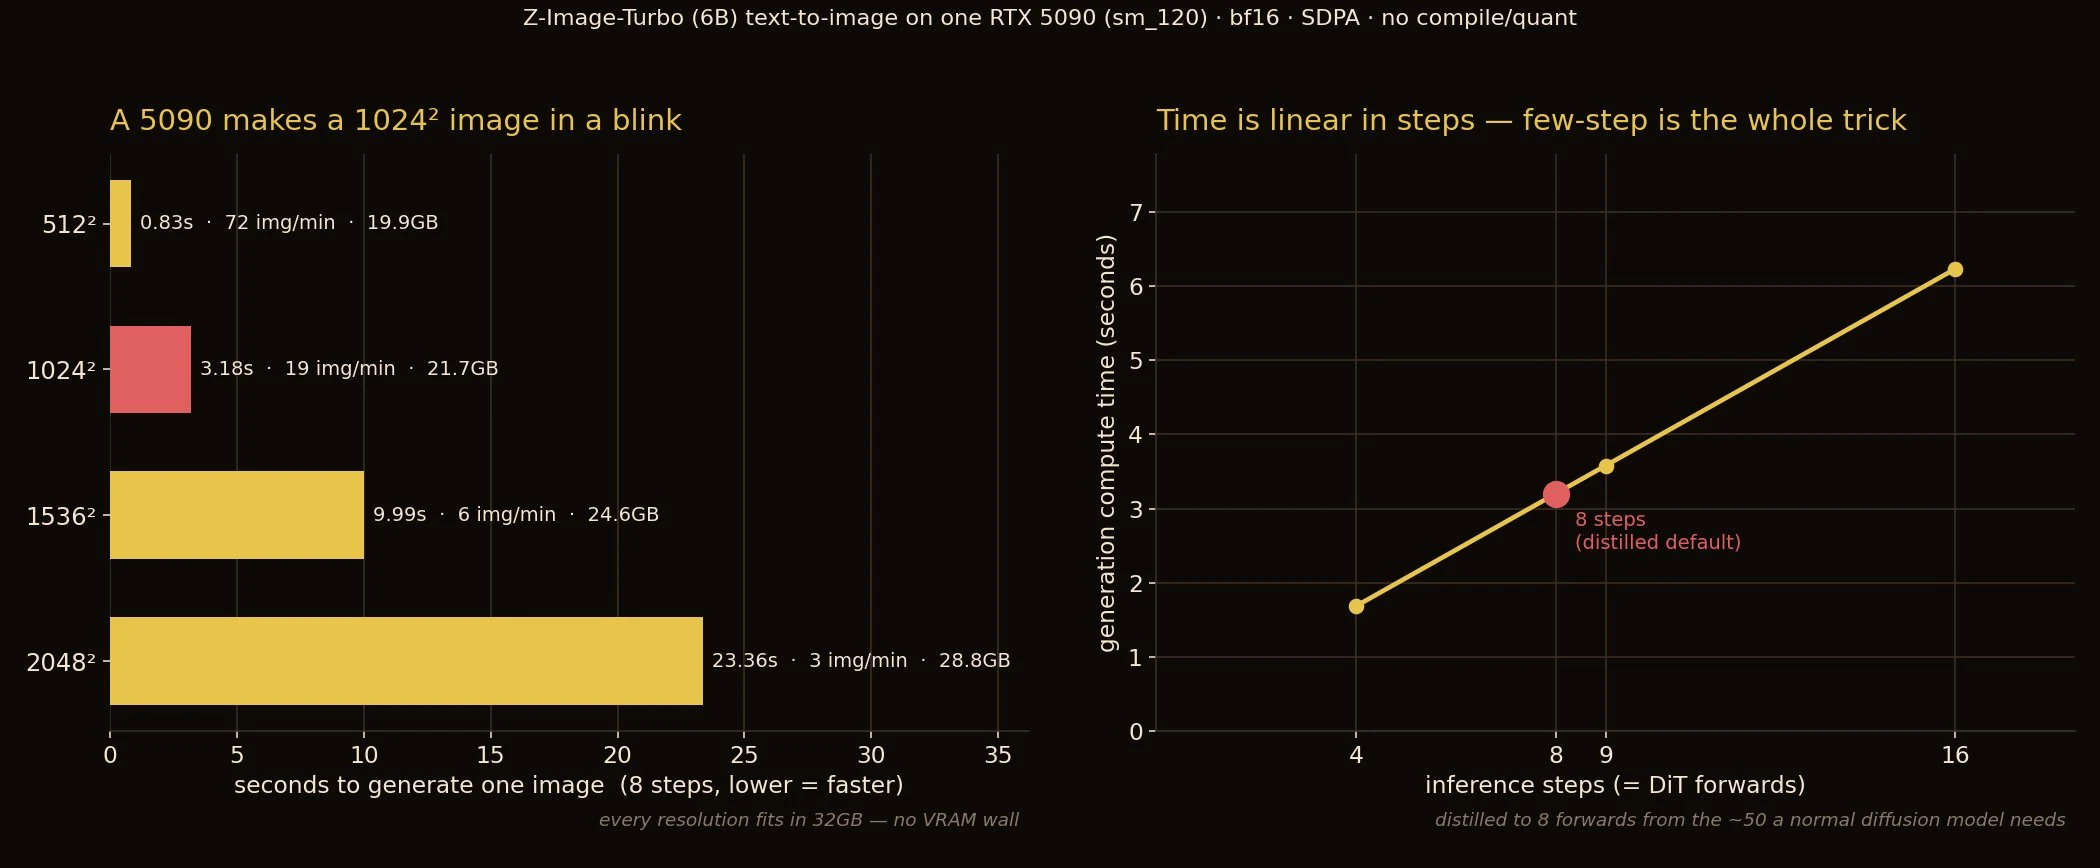
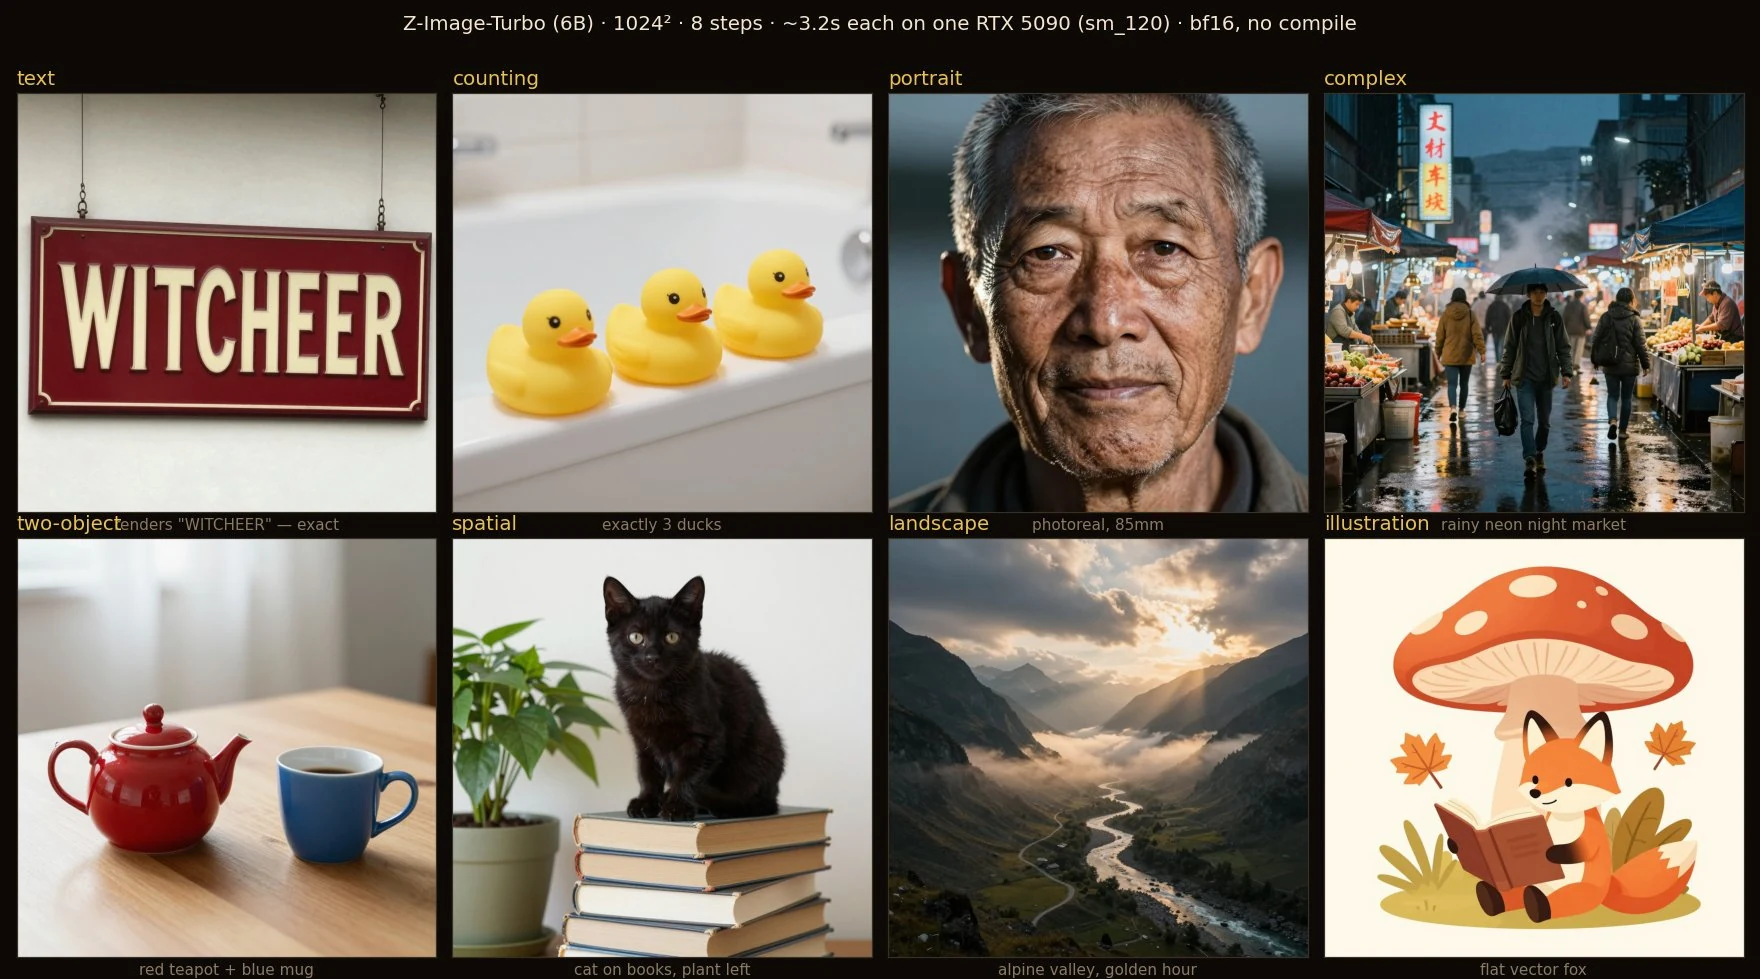
He ran Z-Image-Turbo on an RTX 5090, generating 1024px images in about 3.2 seconds each. The prompt requested a store sign with specified words, plus "exactly three ducks," and both the text and count came out correctly.
These two tasks seem simple, but they have actually been persistent challenges for diffusion models. Letters tend to blur, and three ducks often mysteriously become four or five.
Original post: https://x.com/witcheer/status/2074020722972758139
Next is a case closer to e-commerce delivery.
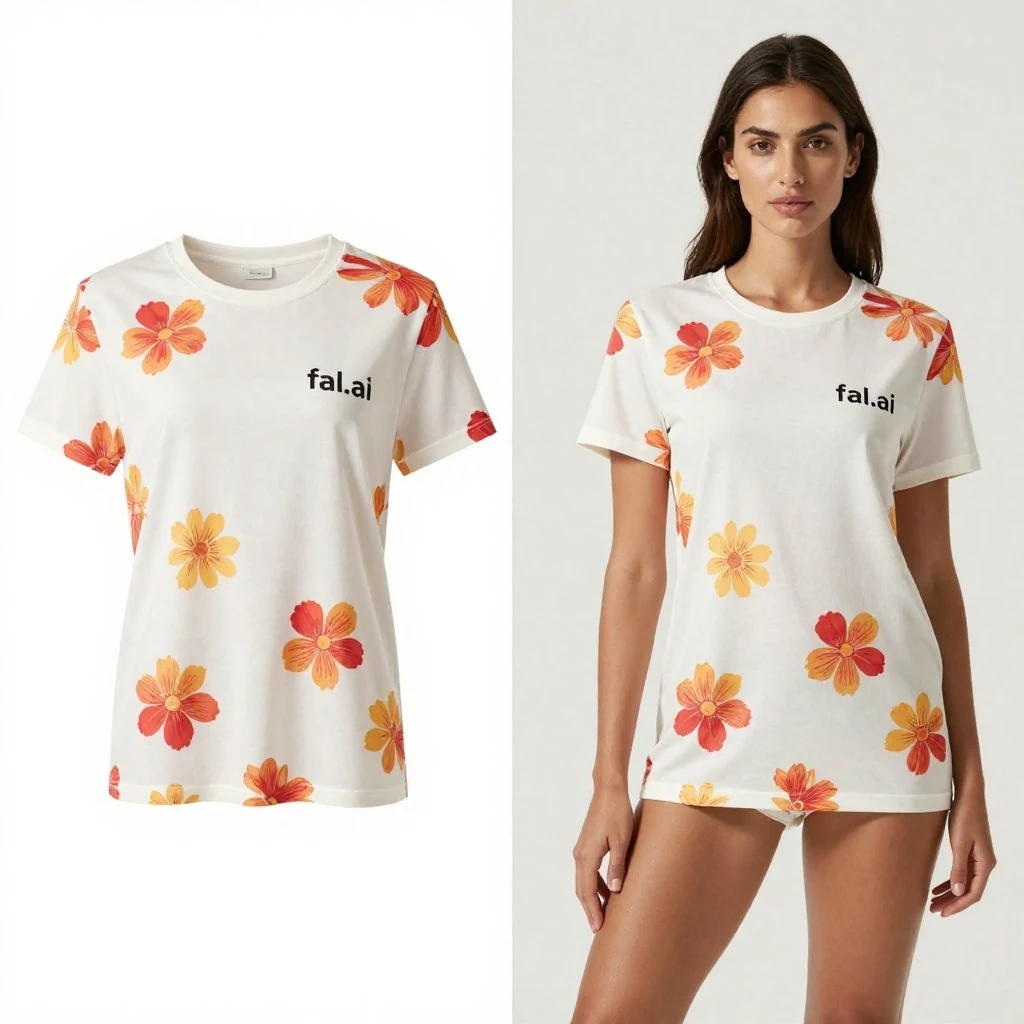
@rizavelioglu had the model generate a side-by-side split image: the left side shows only a white patterned T-shirt, while the right side shows a real model wearing the same shirt. The prompt also required preserving the print, text, fabric, stitching, and cut.
The final output showed that the clothing on both sides wasn't generated independently—the patterns and style matched well. For e-commerce teams, this is far more valuable than simply generating a "pretty model photo." Product images, on-body images, and marketing images can all continue from the same design.
Of course, this is just one successful sample, and there's still a gap before stable batch generation. But it at least proves the direction works.
Original post: https://x.com/rizavelioglu/status/2000012841525649621
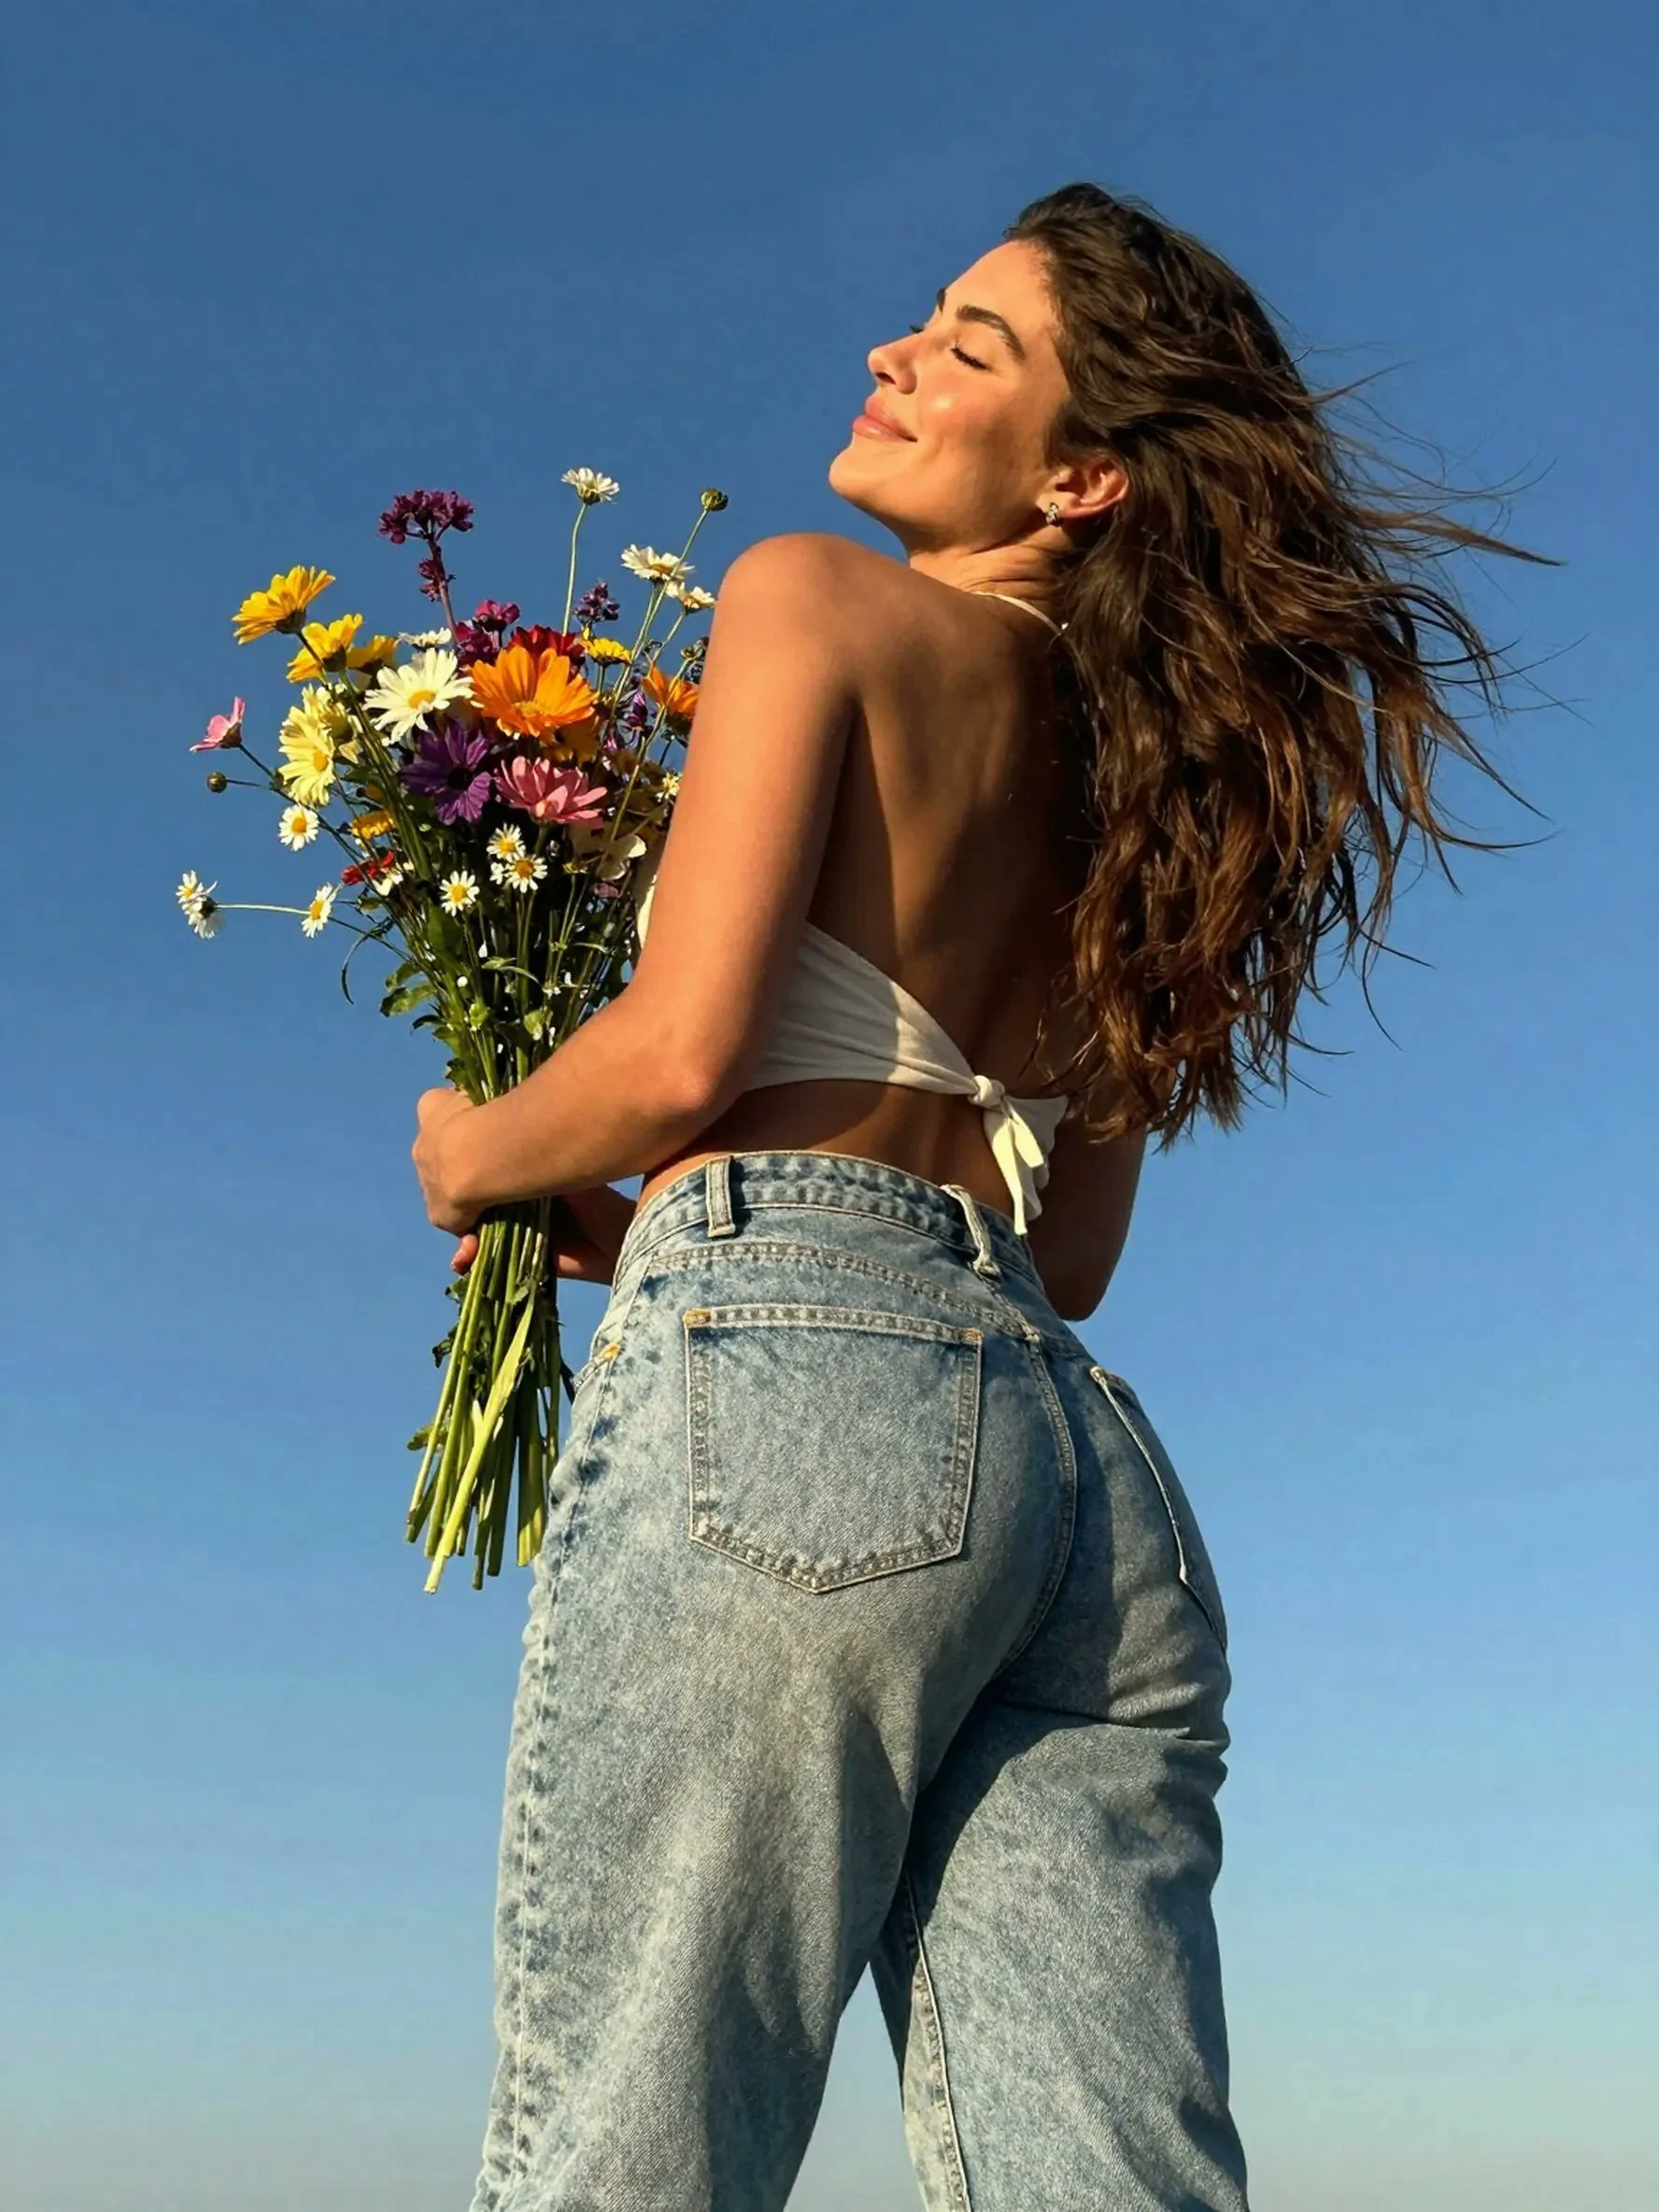
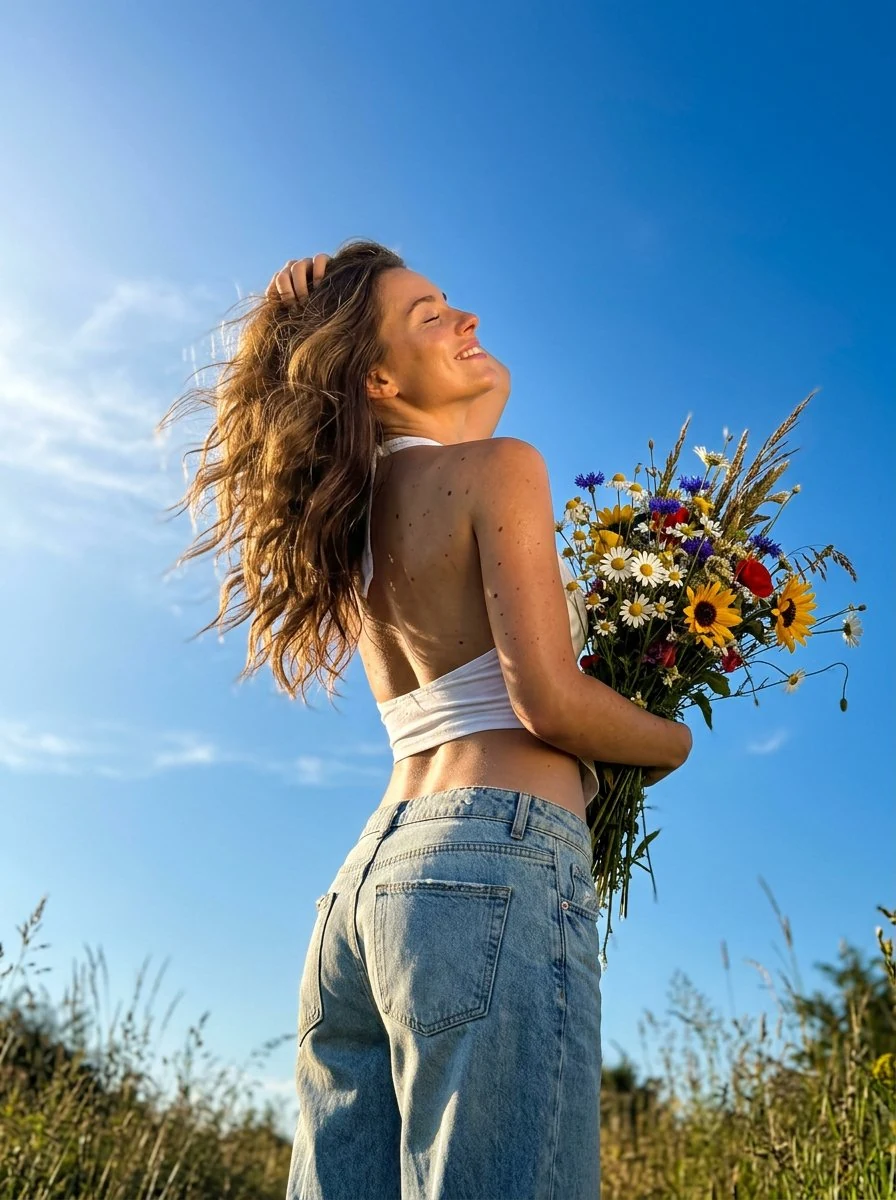
For realistic portraits, @dreamydigiarts created a comparison with the same prompt.
He had Z-Image-Turbo and Nano Banana 2 both generate a phone-shot upward angle: blue sky, backlighting, person leaning back, holding a large bouquet of wildflowers, hair blown by wind, while preserving the slight graininess of phone photos.
The Z-Image output already had a strong candid photography feel. The jeans, skin, and backlighting didn't blur into a plastic layer, and the upward angle composition was solid. For atmospheric character shots and social media images, this is already well beyond toy-level.
Original post: https://x.com/dreamydigiarts/status/2084233075245171142
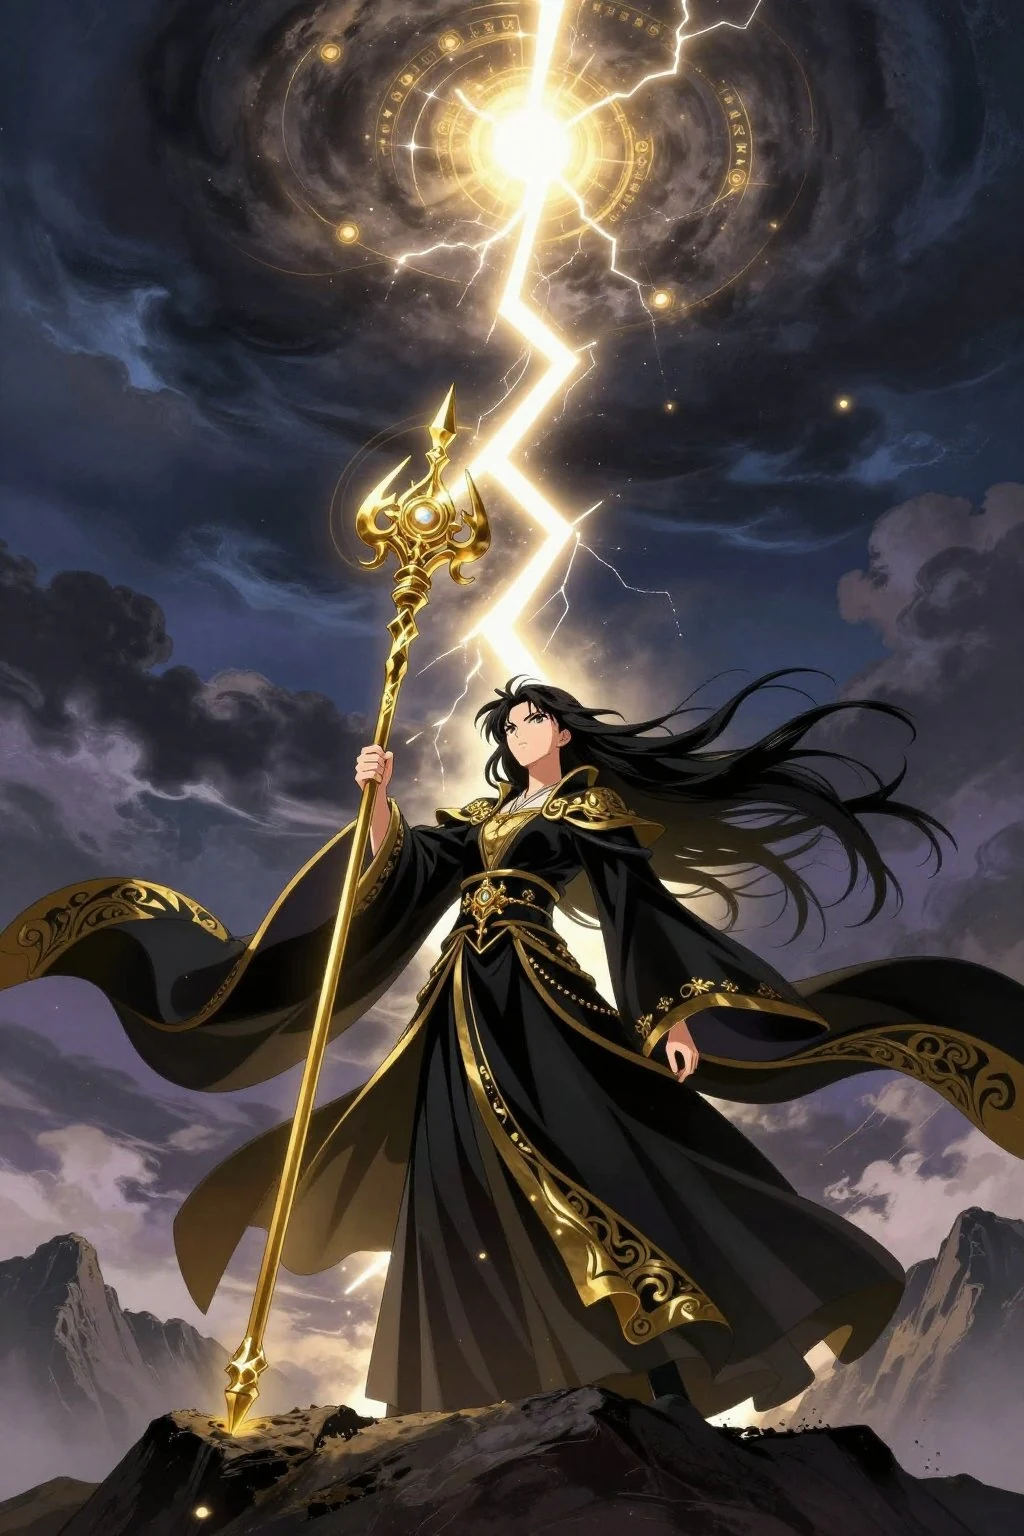
Z-Image isn't limited to realism either. @tisch_eins tested Boogu, Flux 2 Klein, and Z-Image-Turbo with the same prompt. The scene required a black-haired female mage standing on a stormy mountaintop, with a golden staff fully visible from hand to tip, a lightning bolt shooting from the staff tip into the clouds, plus low-angle, full-body composition, cape, runes, electrical arcs, and strong golden rim lighting.
يميل هذا النوع من الـ Prompts إلى إهمال جانب لصالح آخر: يُقص العصا، يرتبط البرق في الموضع الخطأ، وقد تنتهي الشخصية برأس كبير فقط. حافظت نتيجة Z-Image على جميع العلاقات الرئيسية، مما يُظهر تحكمها القوي في تركيبات الرسوم المعقدة.
Original post: https://x.com/tisch_eins/status/2081490372405174375
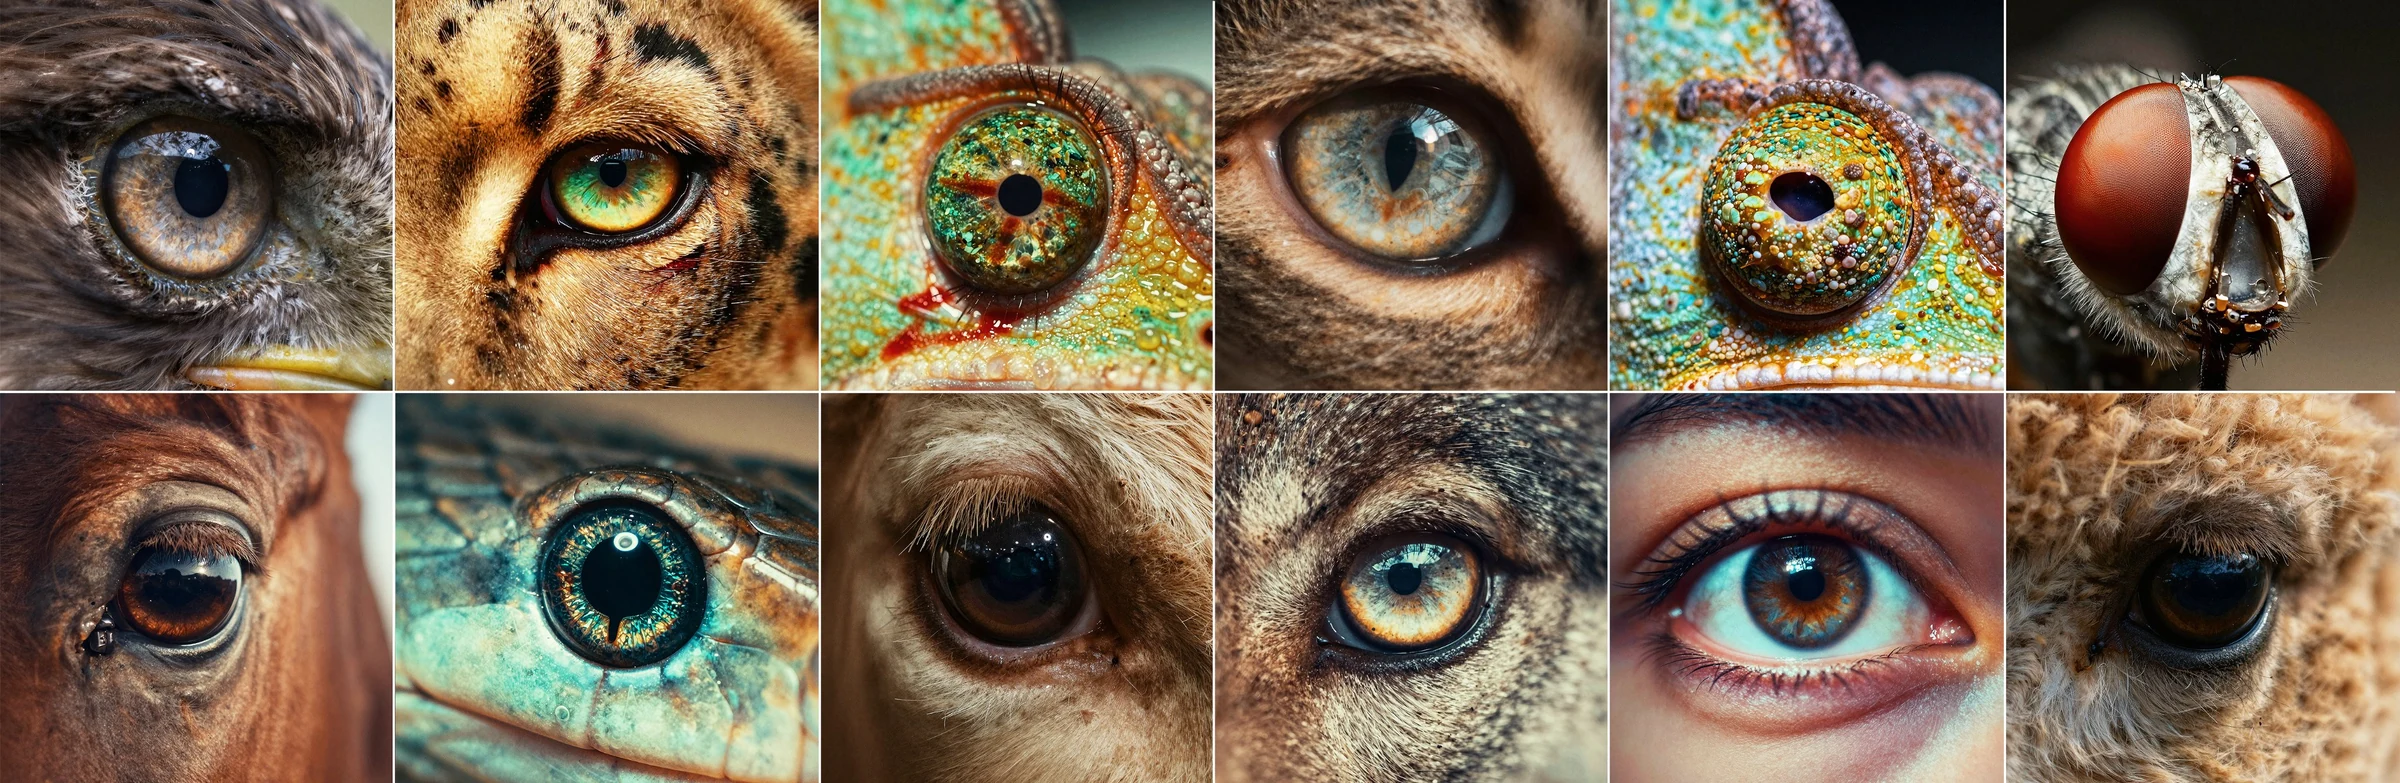
The last one is extreme macro photography. @aisthetiic's prompt was very short: an animal's pupil filling the main frame, with dramatic lighting from the upper left revealing iris texture, and a background gradient from dark to bright bokeh.
What's more interesting is that the image didn't fall apart. The gaze is firmly locked on the pupil, with light, shadow, and background all serving the same subject. When creating poster key visuals or emotional covers, this kind of compositional compliance is more useful than stacking ten thousand "8K, masterpiece, ultra-detailed" keywords.
Original post: https://x.com/aisthetiic/status/1994424107451007336
Looking at these 5 cases together, Z-Image's advantages are quite clear:
The model is small, fast, capable in realism, and can understand relatively long natural language prompts. The full base model can also be used for LoRA, ControlNet, and industry fine-tuning.
MiniMax H3: الفيديو مفتوح المصدر يبدأ بالشعور السينمائي
توليد الفيديو أصعب بكثير من توليد الصور. A single wrong finger in an image can sometimes be cropped out. But in video, if the character's face changes over 15 seconds, the camera doesn't follow the timeline, dialogue gets mixed up between characters, or sound effects don't match actions—any one slip and the whole piece is ruined.
In H3's cases, the first thing worth examining is dual-character consistency.
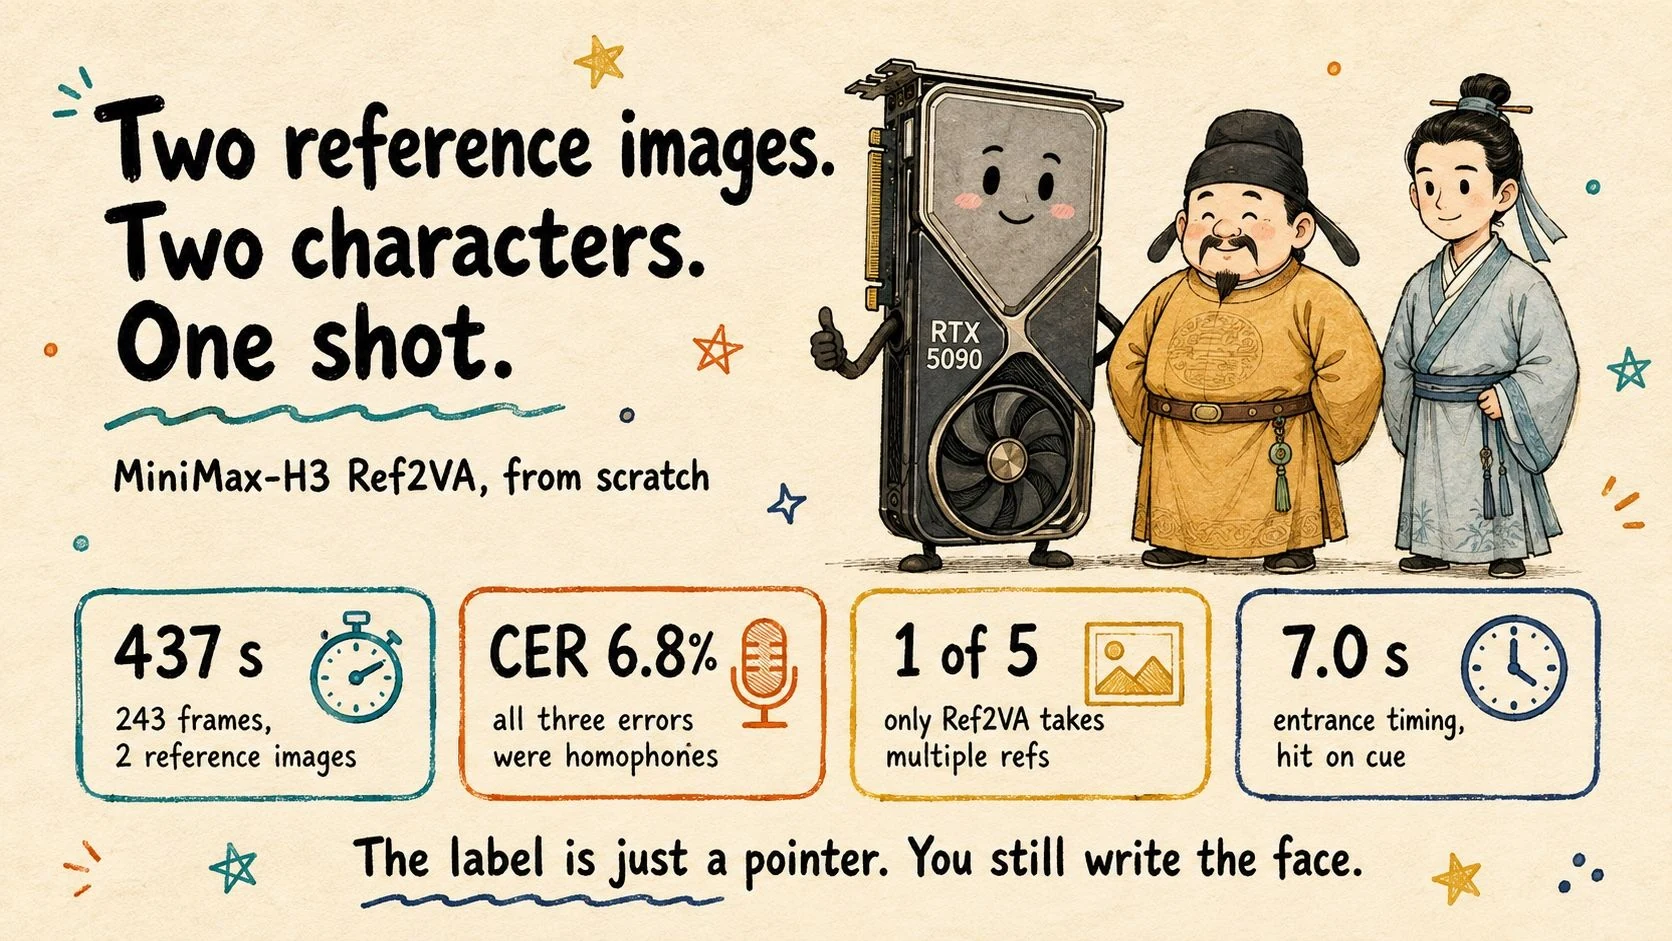
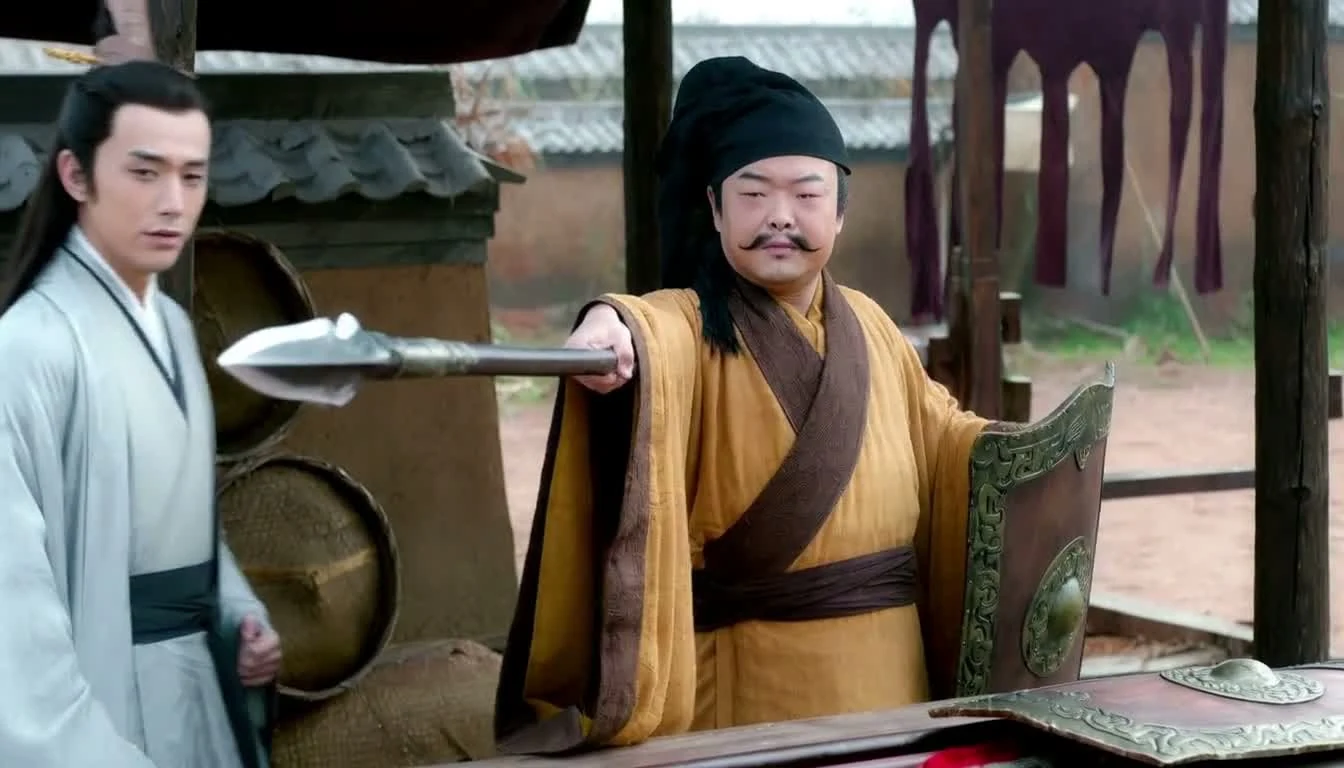
@coolthor fed two Z-Image-generated character design images into H3's Ref2VA mode. One wears an ochre robe, the other wears blue-grey clothing, with deliberately different appearances. The prompt arranged for one character to enter between seconds 6-8 and included three lines of Chinese dialogue.
In the 10.125-second video, the two characters didn't swap faces or clothes. The character scheduled to enter didn't appear in the first half and only appeared around the 7-second mark. The author then used ASR to verify 44 Chinese characters, achieving a character error rate of 6.8%, with errors being homophones.
This was run on a single RTX 5090, taking 437 seconds for 243 frames. The speed isn't extremely fast, but being able to control character, timing, and dialogue simultaneously is already very impressive.
Original post: https://x.com/coolthor/status/2096779996320719307
Another local case comes from @Lumosous.
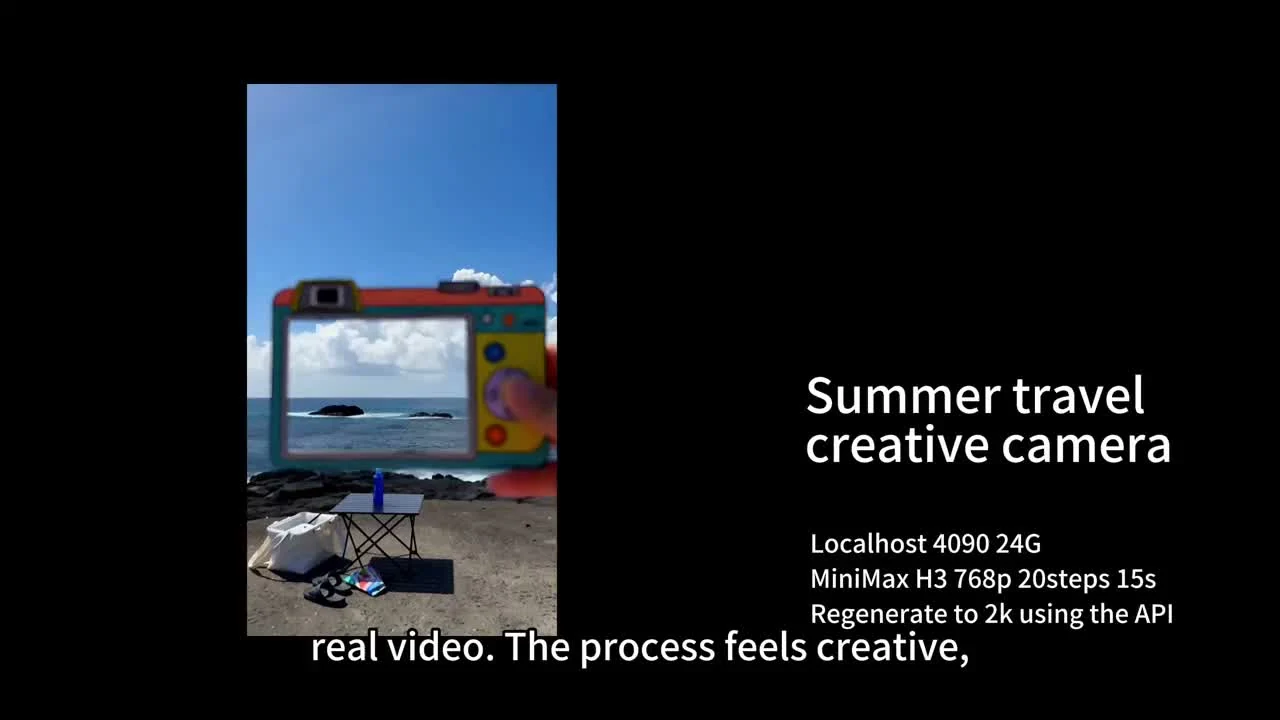
Using an RTX 4090 and ComfyUI, he made three attempts: a four-scene travel short film, a music video that switches scenes with drum beats, and a seaside story with 4 shots and ambient sound. The initial idea was first sent to MiniMax's official Prompt Writing Skill to create structured prompts with shots, timing, actions, and sounds, then fed to H3.
The most useful aspect of this case is that it didn't just make "pretty images." When the drum beat hits, the scene actually changes; in the seaside clip, the four shots, atmosphere, and background sound all came out together in one round.
His benchmark data: 4090 takes over 200 seconds for a 15-second, 20-step low-resolution video; upgrading to 768p takes over 1000 seconds. Open source lets you iterate repeatedly, but free doesn't mean costless—electricity, VRAM, and wait time are also costs.
Original post: https://x.com/Lumosous/status/2089351551361937490
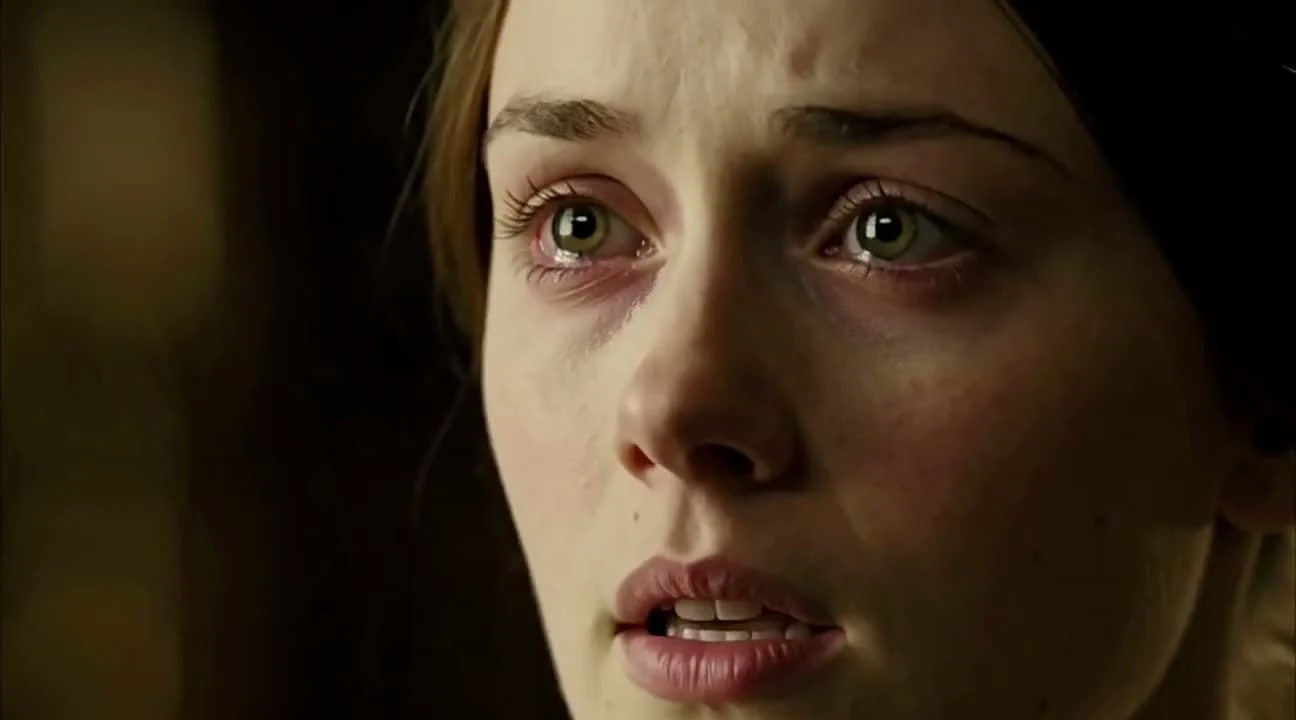
@PixelAigc's 30-second "Jane Eyre"-style British manor segment is even more impressive.
His prompt directly broke the 30 seconds into 4 shots. Each segment specified focal length, camera angle, character positioning, micro-expressions, dialogue, breathing, ambient sound, and prohibited items. Character emotions progressed from tentative to counter-argument to moved, with separate voice constraints for male and female.
This piece used local ComfyUI with H3 Turbo LoRA, first generating 480p, then upscaling to 1080p with Topaz. The author reported that 25 seconds takes approximately 13-15 minutes. This doesn't represent the official model's raw performance, but it represents the most interesting aspect of the open-source ecosystem: one month after the model's release, the community is already modifying speed, creating long videos, and integrating automatic super-resolution.
Original post: https://x.com/PixelAigc/status/2093563293306929579
H3's official single-segment limit is 15 seconds. So how do you make longer videos?
@superalesha used 4 RTX 3090s to run a 30-second first-person action film. He chained two 15-second segments, deliberately stopping the first on a stable frame, continuing generation from the same frame in the second segment, cutting the duplicate frames, and letting the audio continue.
The seam is hidden at the 15-second mark, nearly invisible during normal viewing. The entire piece took 44 minutes from generation to completion. The value of this case isn't that H3 suddenly broke the time limit, but that someone figured out the limit and worked around it with a workflow.
Original post: https://x.com/superalesha/status/2086171185134686509
There's also a case particularly useful for studying "how to actually write video prompts."
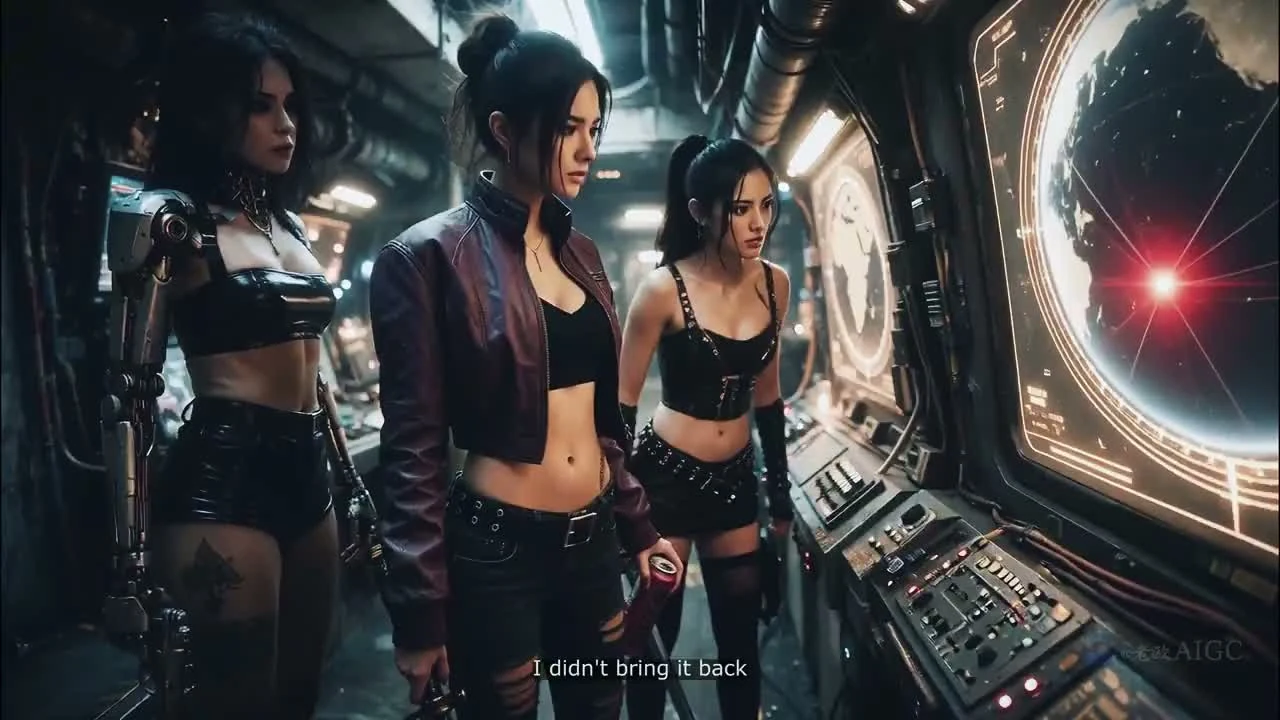
@ou_zhen599 used local ComfyUI to create a 15-second cyber spaceship short film. The scene features three female characters: one sitting on the left, one standing in the center with a knife, and one standing in the front-right holding a soda can. The prompt didn't just describe the plot—it specified who speaks at what second, that silent characters must not move their lips, the soda can must remain in the right hand throughout, when the red tracking point appears on screen, and finally when the shadow outside the porthole presses in.
The hardest part of this kind of case is keeping the space stable, not losing props, not mixing up dialogue, and making silent characters truly stay quiet. H3 already managed to pack all these constraints into a 15-second short film. The game for open-source video has clearly changed.
Original post: https://x.com/ou_zhen599/status/2097988690102390893
بشكل عام:
If you just want to quickly produce a finished video, closed-source models are still the easiest option.
But if you want to iterate repeatedly, batch generate, train your own style, or integrate capabilities into a local workflow, Z-Image and H3 are worth serious study. Use open-source models to rapidly prototype shots and footage first, then call closed-source models only when truly stuck—costs will be much lower.
Open-source models used to feel like a consolation prize for those waiting things out. Now they can genuinely participate in real creative work.
For people who need to create images and videos daily, the best change is that in the future, every time an idea comes up, you don't first have to calculate how many credits this round will burn.