फाइन-ट्यूनिंग और मूल्यांकन • शुरुआती⏱️ 30 मिनट पढ़ने का समय
Training Data Preparation
How to Transform Business Materials into Trainable Data?
Before training a model, we often encounter the following problem:
I have a lot of raw materials, product manuals, operation guides, and business specifications, each in its own format, and the content is quite scattered,
How can I make use of this data?
And if I directly use domain-specific or scenario-specific data, will the trained model still have the ability to answer general knowledge questions?
Therefore, the key point is how we can transform all materials into training data usable by the model.
At the same time, data cleaning, deduplication, and anonymization are also essential. We may have distilled the data, but we need to adapt it to our desired outcomes.
For example, when training a model, if the self-identification data is not properly trained, it might answer that it is a ChatGPT model, a Claude model, and so on.
Data is the foundation of everything. In this chapter, we start from data sources and look at how these scattered materials go through synthesis, cleaning, deduplication, and anonymization to finally become data that can be used for model training.
Learning Business Skills While Preserving General Capabilities
Collecting and annotating training data from scratch requires significant time and cost. For common tasks such as text classification, question answering, and text generation, you can find suitable public datasets to include in training.
Common public datasets include:
Text classification and inference: GLUE, SuperGLUE, CLUE, etc.;
Reading comprehension and question answering: SQuAD, CMRC, etc.;
Text summarization: CNN/DailyMail, etc.;
Dialogue and instruction fine-tuning: Alpaca, ShareGPT, OpenOrca, etc.;
Multimodal tasks: COCO and other image-text datasets.
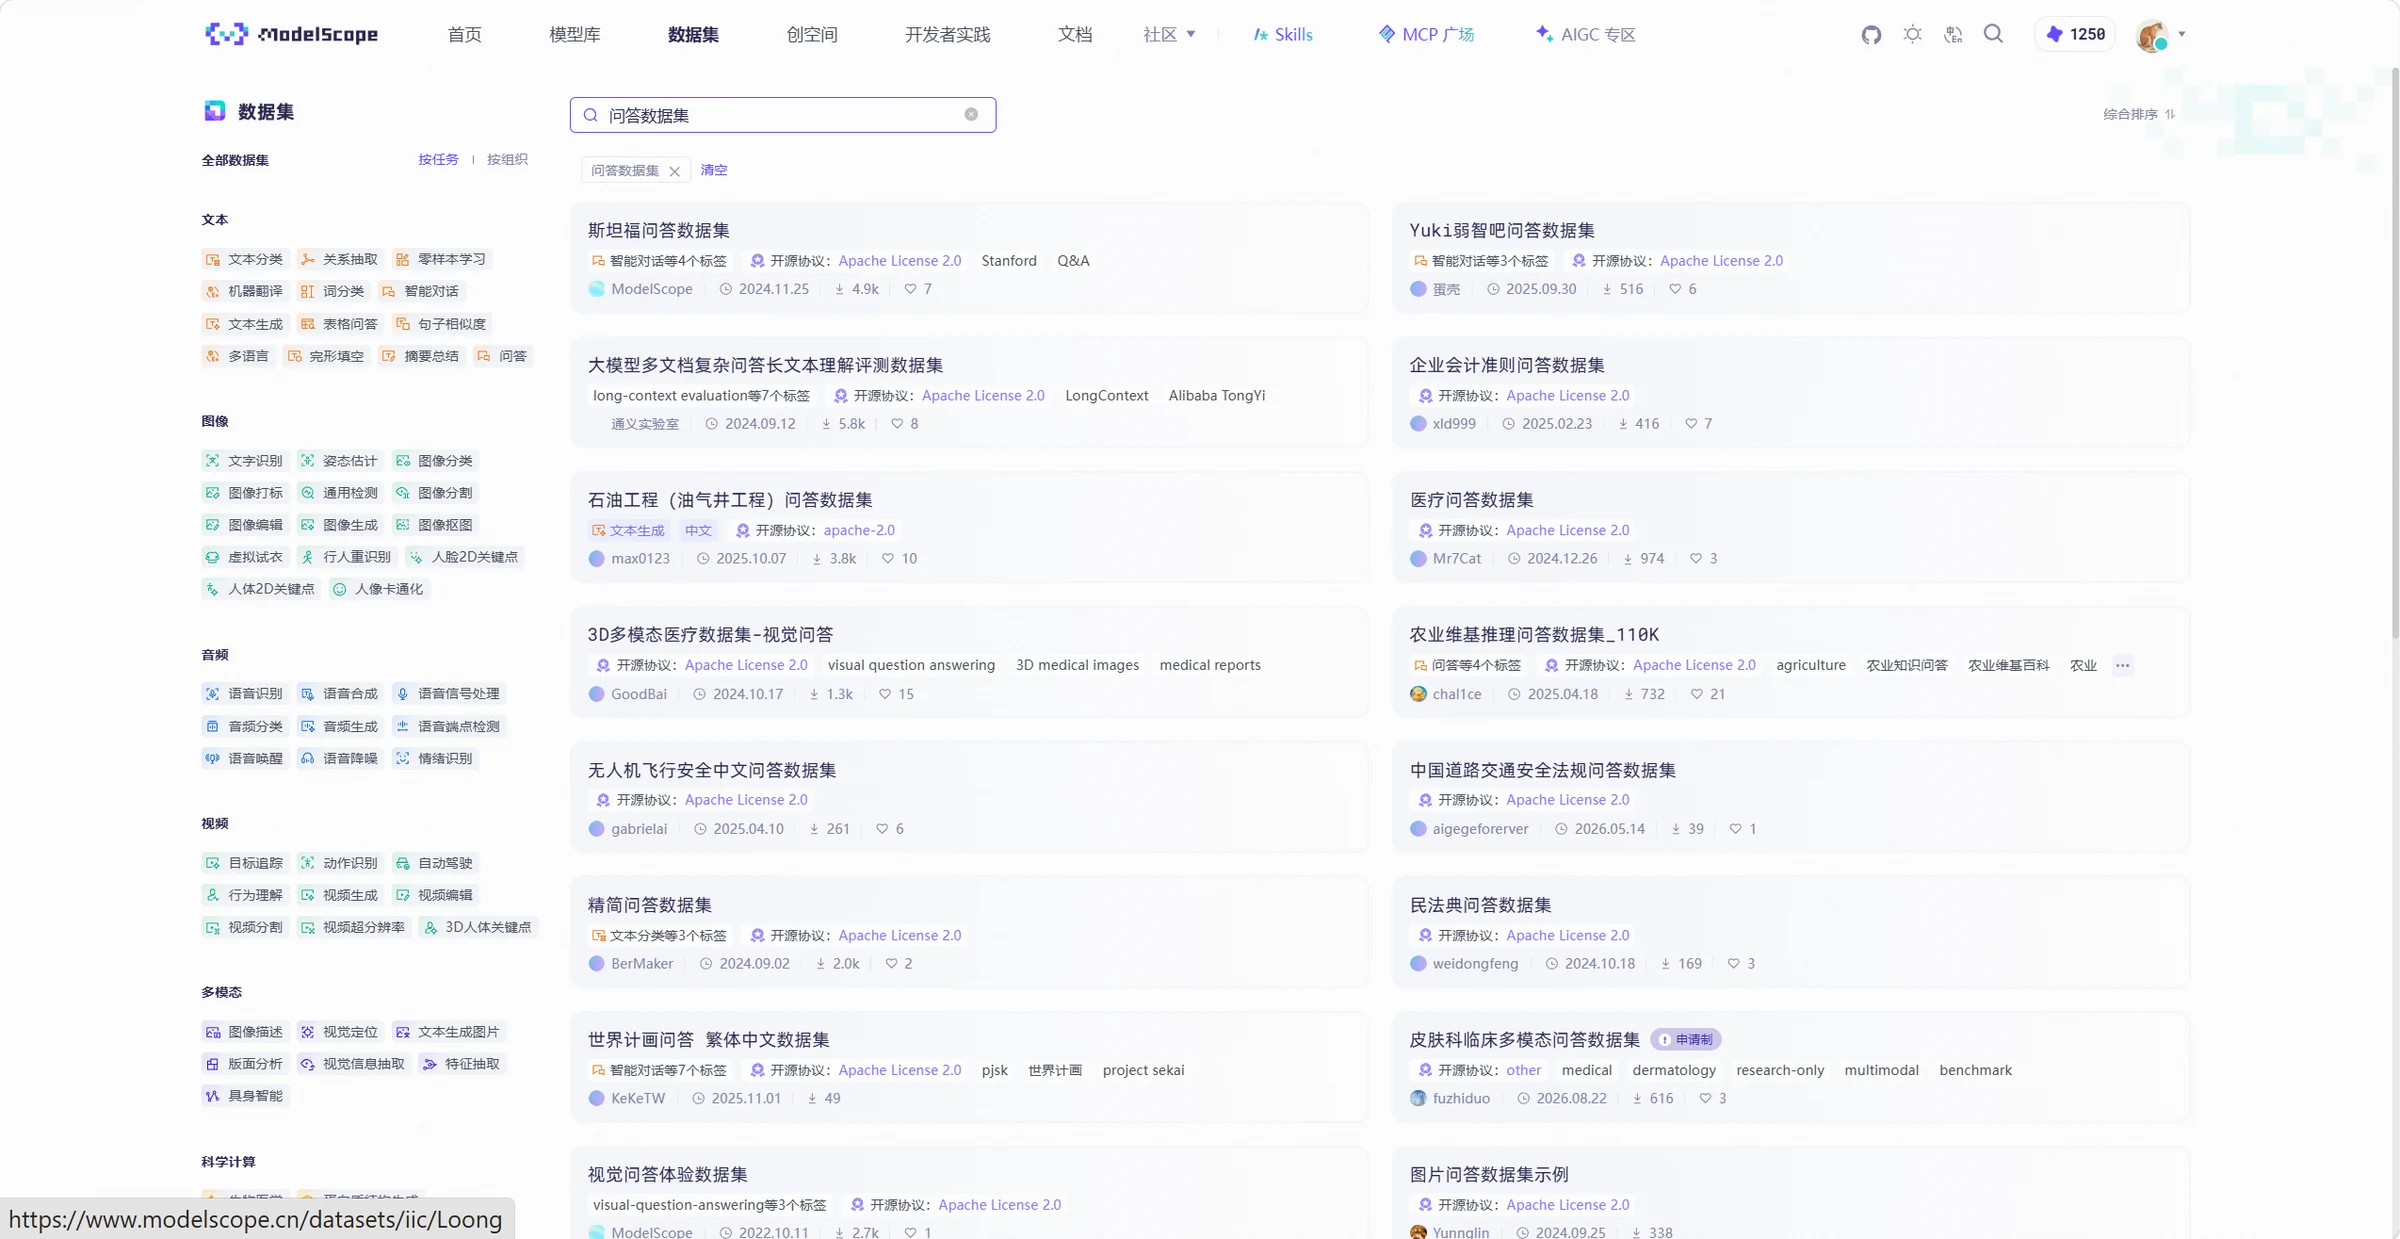
In addition to obtaining data from dataset official websites, you can also find and use open-source datasets through the ModelScope Dataset Hub. The Dataset Hub provides features such as dataset search, online preview, and download. Some datasets can also be loaded directly through the ModelScope SDK for subsequent processing and training. For specific dataset download methods, see the chapter "Data: The Foundation for Open-Source Model Fine-Tuning".
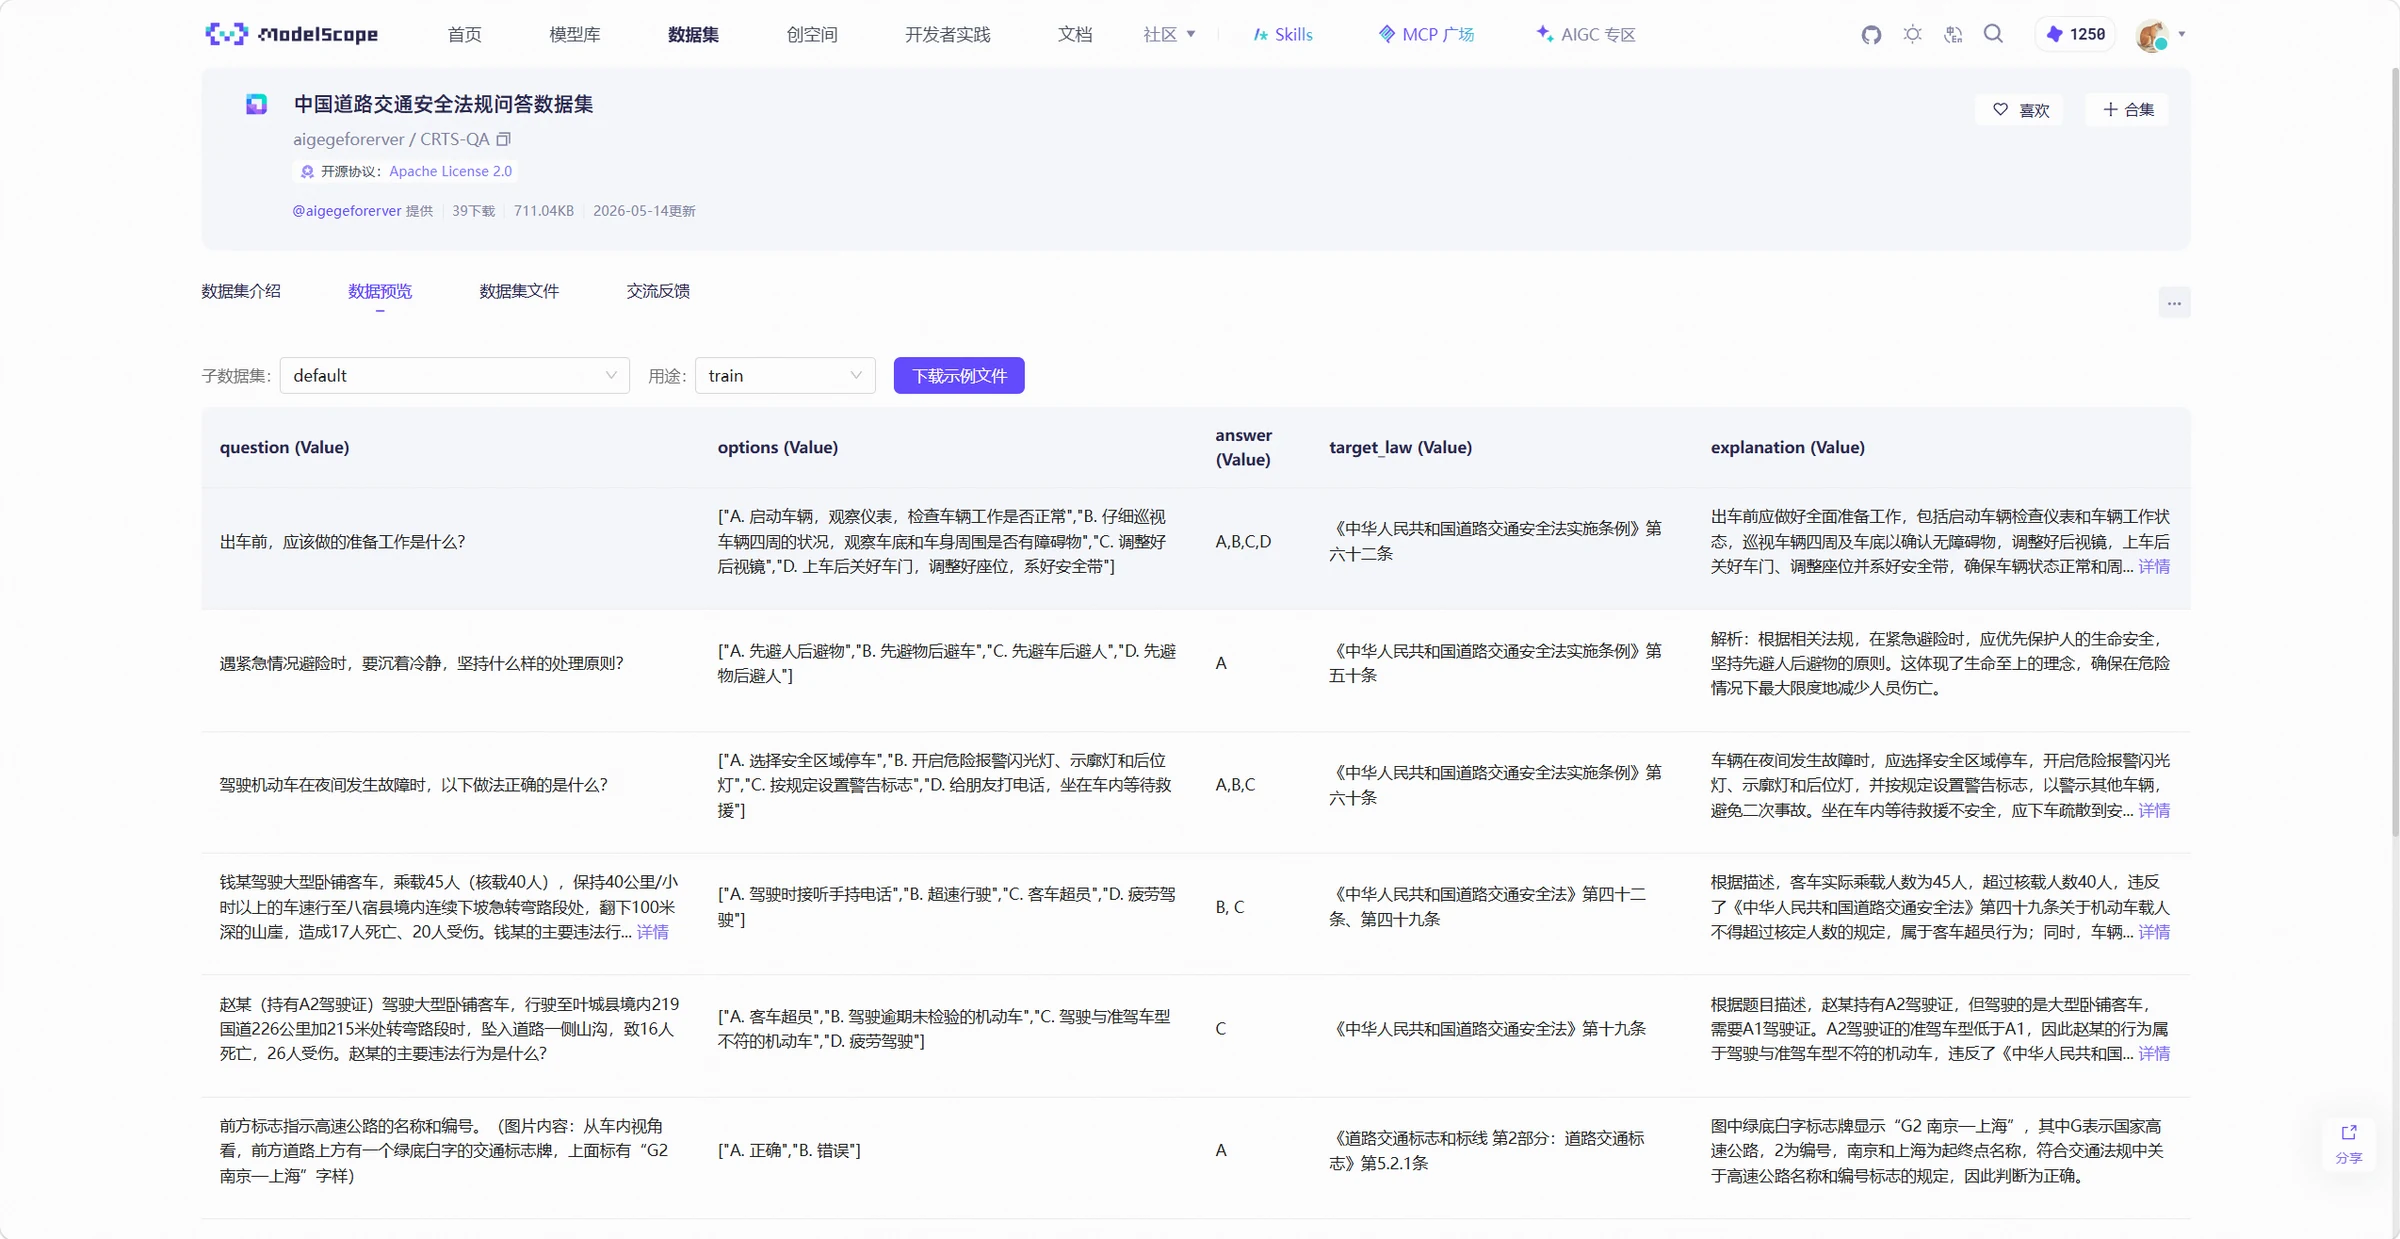
When selecting open-source datasets, you should not only check whether the data content matches the training task, but also verify the dataset's sample count, field format, label types, and data quality to determine whether it meets training requirements. The data preview feature provided by ModelScope can help quickly view dataset fields and sample content, as shown in the following example:
Open-source data is mainly used to supplement the model's general capabilities. If the model needs to learn enterprise-internal products, terminology, business rules, and processing workflows, corresponding business data needs to be prepared.
How to Use Business's Own Materials?
Business data comes from actual enterprise business systems and materials, which is closer to the scenarios where the model will ultimately be used. General Q&A data can help the model learn basic question-answering patterns, while enterprise-internal Q&A data can further help the model learn product names, business terminology, and processing rules.
Common business data sources include:
Enterprise documents: Product manuals, operation guides, business specifications, workflow documents, etc., from which product knowledge, business rules, and operational processes can be extracted;
Customer service records: Historical conversations between users and customer service, work orders, and complaint records, which can be used to construct intent recognition, Q&A, and dialogue data;
FAQ: Questions and standard answers organized by business personnel, which can be directly converted into Q&A training data;
Expert cases: Typical problems and their solutions handled by business experts, which can be used to construct training data for complex business scenarios.
Business data generally cannot be directly used for model training. A business manual of several dozen pages, for example, needs to have its body text extracted from Word, PDF, and other files first, then organized into Q&A pairs, classification samples, or instruction data based on the training task. Customer service records may also contain system messages, invalid dialogues, and duplicate content that need to be filtered and organized first.
Business data may also contain sensitive information such as names, phone numbers, ID numbers, and customer information. Before entering the training dataset, it needs to be anonymized according to the enterprise's data security requirements to avoid using real sensitive information directly for model training.
Only Documents Without Q&A? Let the Model Help Synthesize Data
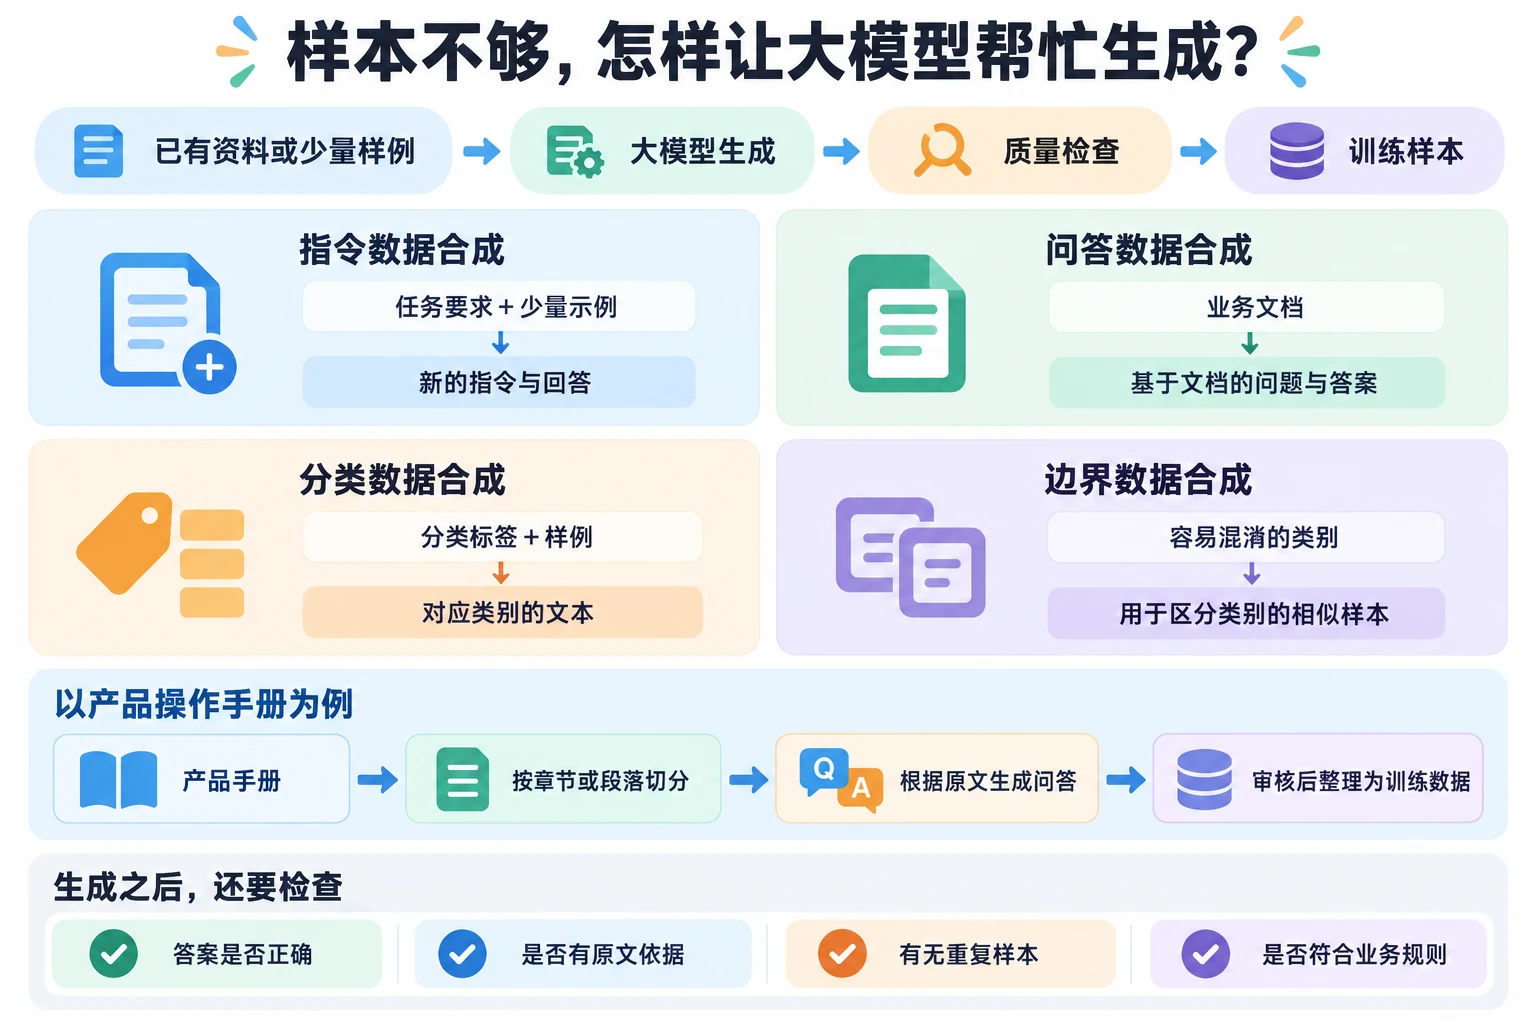
In practical projects, existing data may not meet all training needs. For example, some business types have only a few samples, or existing documents contain knowledge but no Q&A data that can be directly used for training. In this case, large models can be used to generate new training samples, a process called data synthesis.
Common data synthesis methods include:
Instruction data synthesis: Based on existing tasks or a few examples, have the large model generate new instructions and answers;
Q&A data synthesis: Input business documents and have the large model generate questions and answers based on the document content;
Classification data synthesis: Specify classification labels and examples, and have the large model generate text for the corresponding categories;
Boundary data synthesis: Generate similar samples for easily confused categories to strengthen the model's ability to distinguish category boundaries.
For example, if an enterprise only has a product operation manual but no Q&A data, the manual first needs to be split by chapters or paragraphs, and the large model can be used to generate several questions and answers based on the paragraph content. After reviewing the results, they can be organized into Q&A training data.
Data synthesis can reduce the workload of manually writing training samples and supplement scenarios where original data is insufficient. However, synthesized data cannot be directly used for training after generation. The large model may generate incorrect answers, duplicate samples, or fabricate non-existent products or business rules, so quality checks are still needed.
Generated Data Shouldn't Be Used for Training Right Away
The quality of synthesized data directly affects model training results. Before adding synthesized data to the training set, you need to check whether the generated content is correct and filter out incorrect, fabricated, duplicate, and overly similar data.
Do the Answers Match the Original Text?
If the synthesized data is generated from business documents, you need to check whether the generated content is consistent with the original text.
For example, the original business document specifies:
Refund applications need to undergo manual review, and refunds can only be processed after approval.
The Q&A data generated by the model:
Q: Does a refund require review?
A: Refunds are automatically processed after submission, without manual review.
This answer conflicts with the business rules. If used for training, the model may learn incorrect business processes.
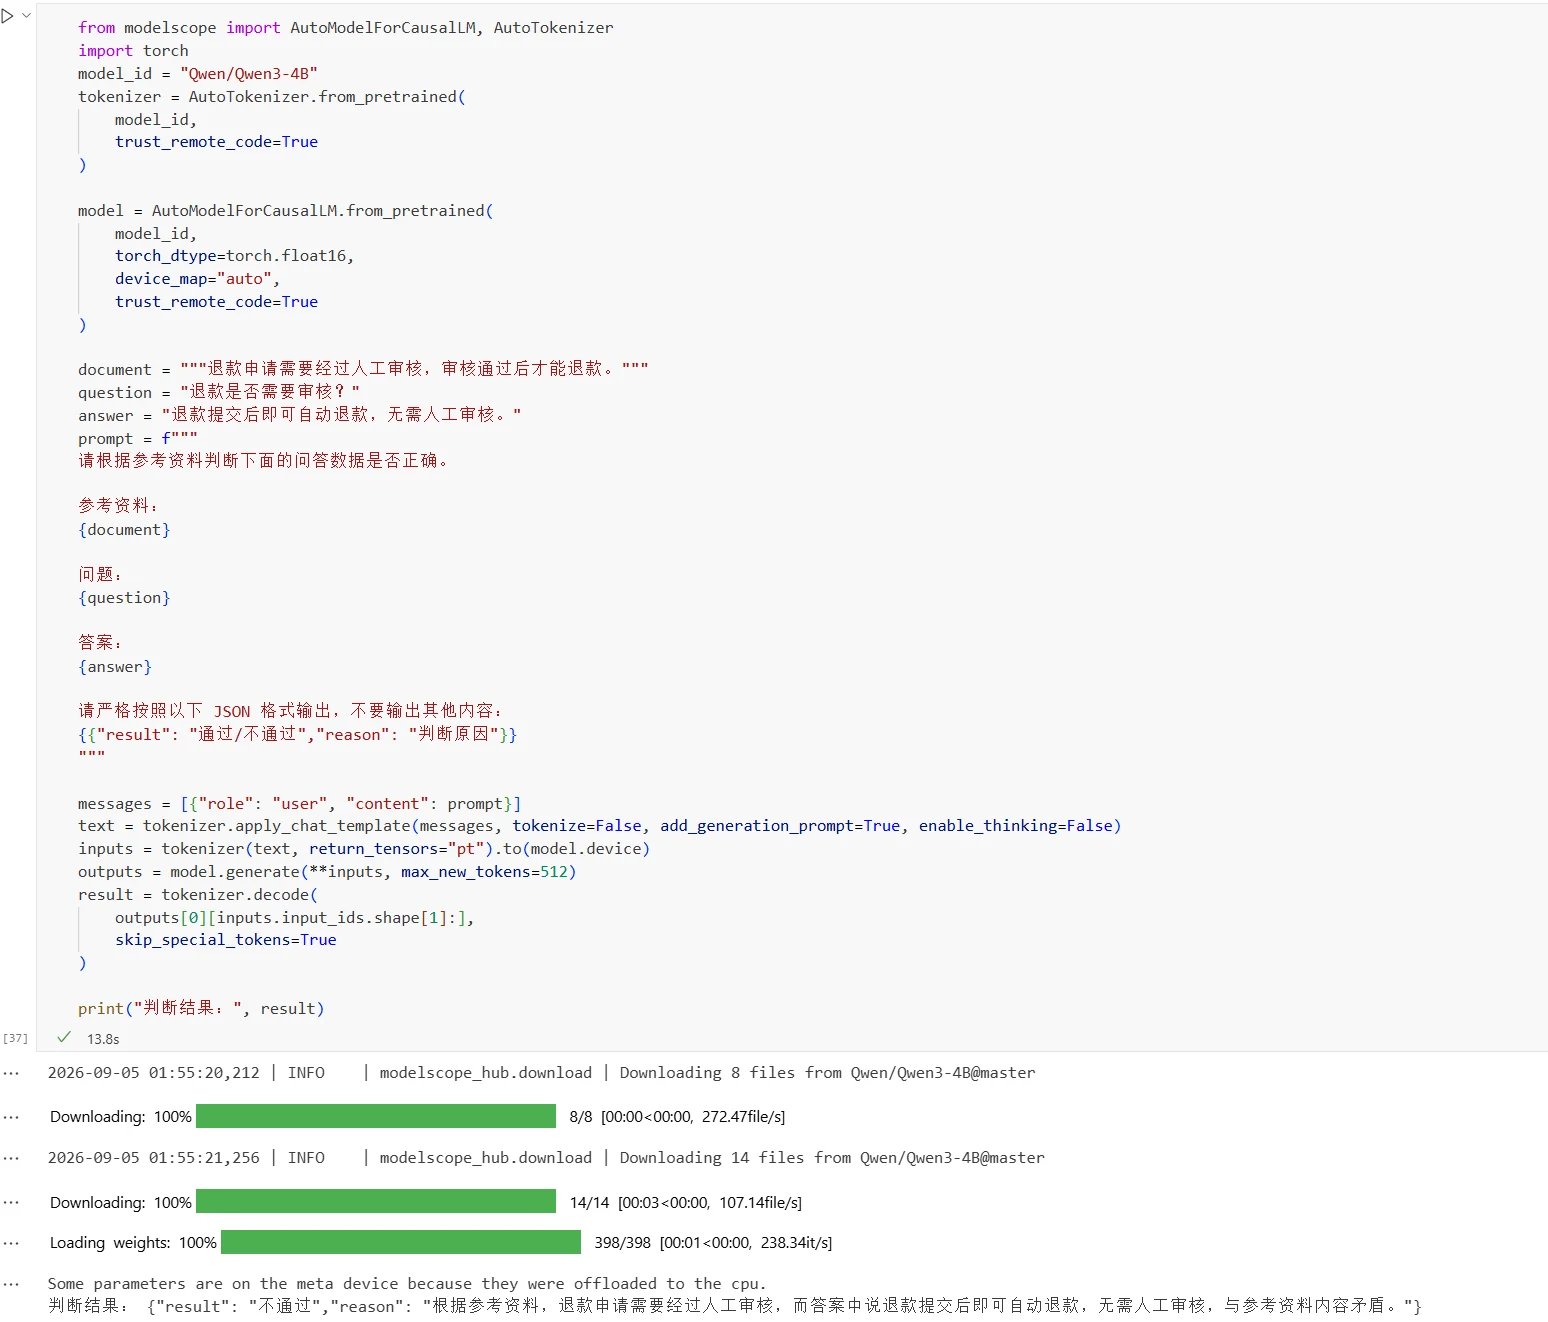
In practice, you can use the large model to perform consistency evaluation on synthesized data. Input the original material, question, and answer simultaneously into the model to determine whether the answer is consistent with the material. For data judged to be incorrect, you can delete or regenerate it. The processing code is as follows:
from modelscope import AutoModelForCausalLM, AutoTokenizer
import torch
model_id = "Qwen/Qwen3-4B"
tokenizer = AutoTokenizer.from_pretrained(
    model_id,
    trust_remote_code=True
)

model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype=torch.float16,
    device_map="auto",
    trust_remote_code=True
)

document = """Refund applications need to undergo manual review, and refunds can only be processed after approval."""
question = "Does a refund require review?"
answer = "Refunds are automatically processed after submission, without manual review."
prompt = f"""
Please determine whether the following Q&A data is correct based on the reference material.

Reference material:
{document}

Question:
{question}

Answer:
{answer}

Please output strictly in the following JSON format, without any other content:
{{"result": "pass/fail", "reason": "reason for judgment"}}
"""

messages = [{"role": "user", "content": prompt}]
text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True, enable_thinking=False)
inputs = tokenizer(text, return_tensors="pt").to(model.device)
outputs = model.generate(**inputs, max_new_tokens=512)
result = tokenizer.decode(
    outputs[0][inputs.input_ids.shape[1]:],
    skip_special_tokens=True
)

print("Judgment result:", result)
Result display:
Don't Let the Model Fabricate What Isn't in the Original Text
When the large model generates data, it may produce information that doesn't exist in the original material. This type of problem is usually called hallucination. For example, generating non-existent product names, product parameters, or business processes.
For example, the original material:
The product supports a maximum of 100GB of storage space.
Generated data:
Q: Does the product support automatic scaling?
A: Yes, when storage space is insufficient, the system will automatically scale up
The original material doesn't state whether the product supports automatic scaling, so the generated answer lacks supporting evidence and is considered fabricated content.
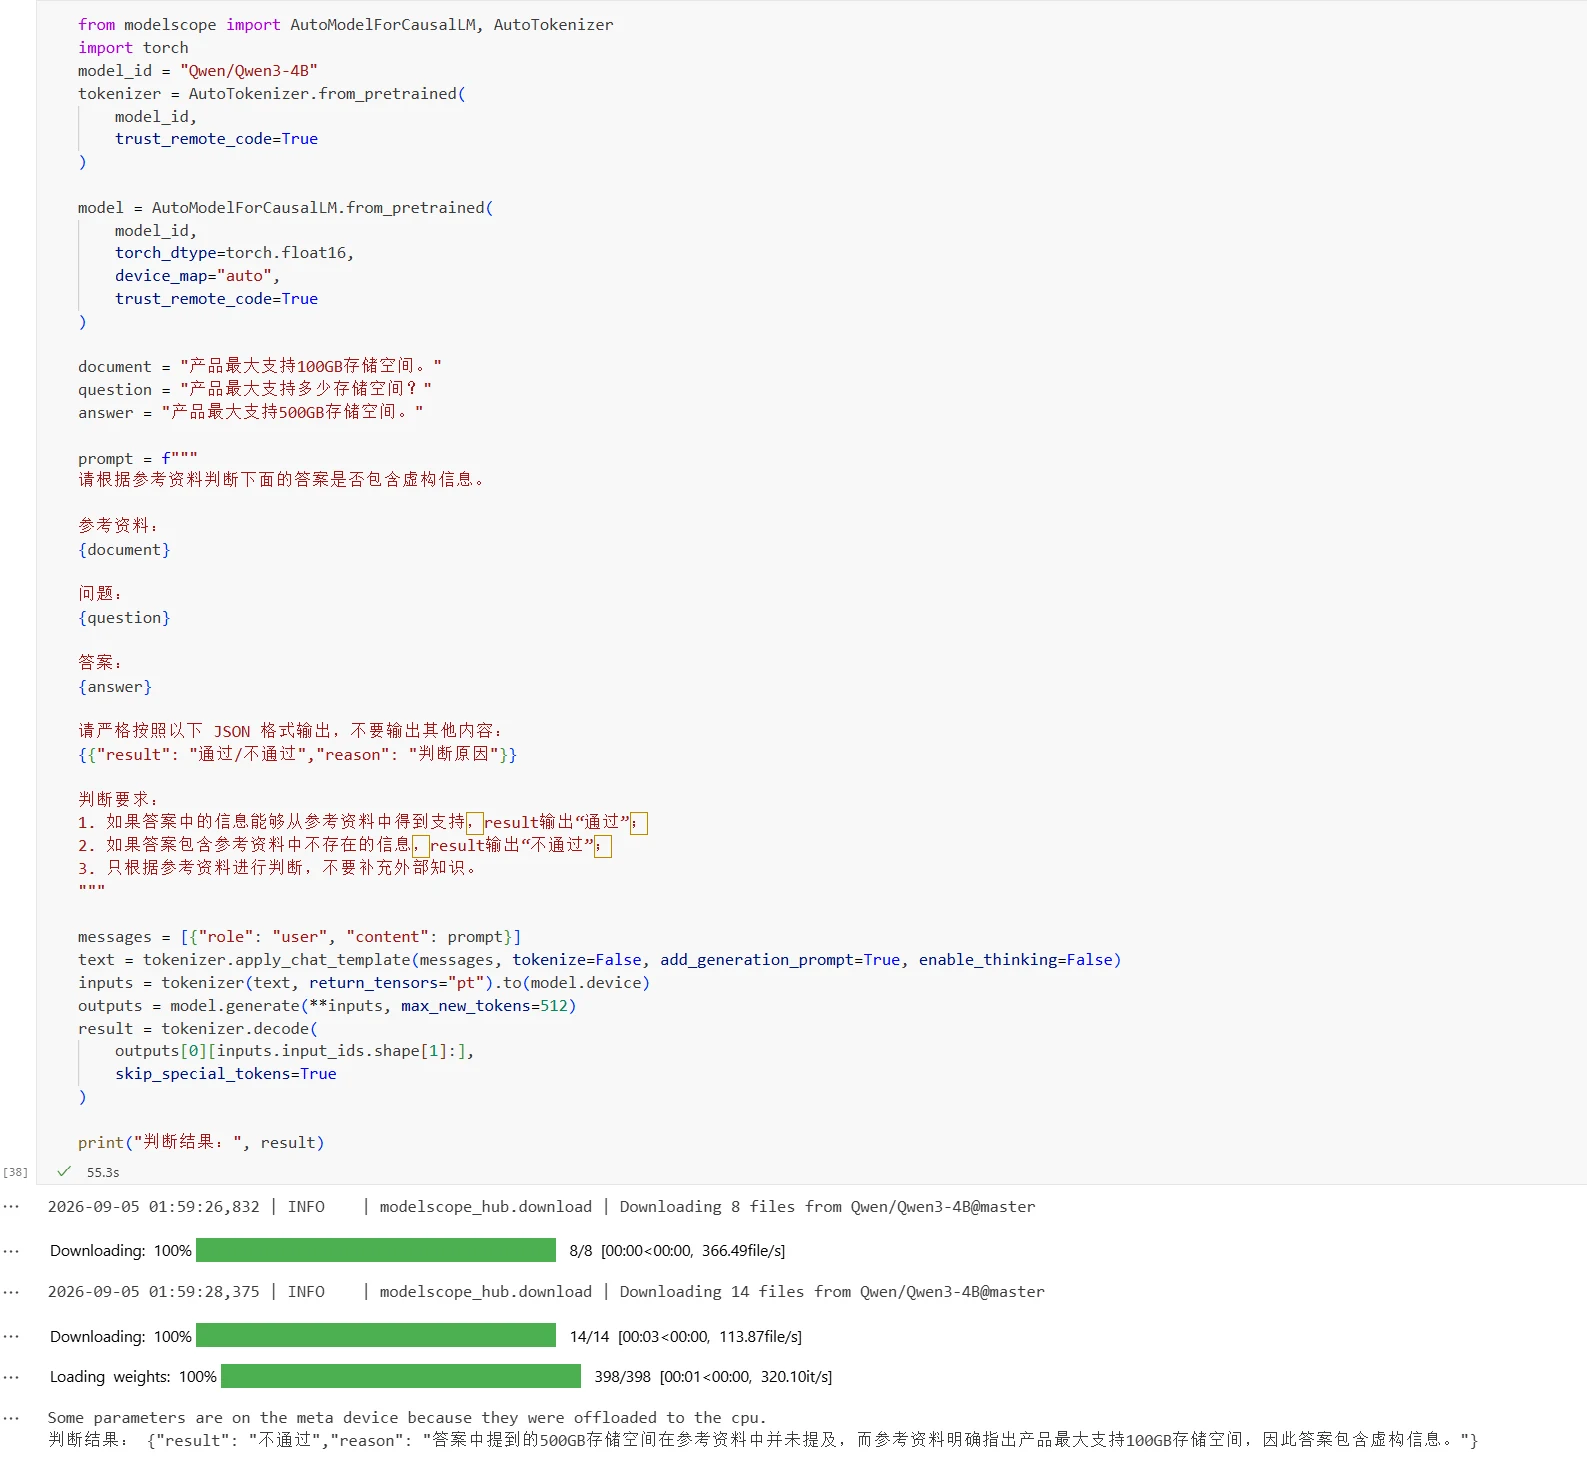
For data generated from business materials, you can use the large model for evidence checking to determine whether the key information in the answer can be supported by the original material. For data lacking evidence or that cannot be confirmed, you can delete, regenerate, or perform manual review. For important business rules, business personnel can also conduct spot checks. The processing code is as follows:
from modelscope import AutoModelForCausalLM, AutoTokenizer
import torch
model_id = "Qwen/Qwen3-4B"
tokenizer = AutoTokenizer.from_pretrained(
    model_id,
    trust_remote_code=True
)

model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype=torch.float16,
    device_map="auto",
    trust_remote_code=True
)

document = "The product supports a maximum of 100GB of storage space."
question = "What is the maximum storage space supported by the product?"
answer = "The product supports a maximum of 500GB of storage space."

prompt = f"""
Please determine whether the following answer contains fabricated information based on the reference material.

Reference material:
{document}

Question:
{question}

Answer:
{answer}

Please output strictly in the following JSON format, without any other content:
{{"result": "pass/fail", "reason": "reason for judgment"}}

Judgment requirements:
1. If the information in the answer can be supported by the reference material, result outputs "pass";
2. If the answer contains information not in the reference material, result outputs "fail";
3. Judge only based on the reference material, do not add external knowledge.
"""

messages = [{"role": "user", "content": prompt}]
text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True, enable_thinking=False)
inputs = tokenizer(text, return_tensors="pt").to(model.device)
outputs = model.generate(**inputs, max_new_tokens=512)
result = tokenizer.decode(
    outputs[0][inputs.input_ids.shape[1]:],
    skip_special_tokens=True
)

print("Judgment result:", result)
Result display:
Different Phrasing, Same Question
When the large model generates data in batches, it easily produces duplicate or highly similar samples. For example: "How to change the login password?" and "How do I change the login password?" These questions have different phrasings but essentially the same content. If there are too many similar samples, it will reduce the effective information of the dataset.
After data synthesis, you need to check for duplication and similarity between samples, filter out completely duplicate data, and control the number of highly similar samples while retaining representative ones. Specific data deduplication methods will be introduced in the following sections.
Organizing Data from Different Sources Together
Whether data comes from open-source datasets, enterprise business data, or large model synthesis, it needs to undergo unified processing before being used for model training. Common processing steps include data collection, data cleaning, data deduplication, and data anonymization.
First Collect the Required Content and Standardize the Fields
Data collection involves obtaining the required data from different data sources based on the training task, and organizing it in a unified manner.
Before collection, you need to determine the data content required for the training task. Classification tasks need text and category labels, Q&A tasks need questions and answers, and instruction fine-tuning needs instructions and corresponding answers. During collection, only keep data and fields related to the training task.
Data structures from different sources may differ. For example, one dataset uses question and answer fields, while another might use query and response fields. After collection, you need to unify field names and data structures for subsequent processing.
For data missing necessary information, you can supplement it during the collection process. For example, adding category labels to classification data, or organizing reference answers for Q&A data.
Data Needs to Be Cleaned First
Raw data may contain some invalid or erroneous content that needs to be cleaned before training.
Common processing includes: removing blank data and invalid records, stripping redundant HTML tags and special characters, unifying text encoding and formatting, and correcting obvious OCR recognition errors.
Data cleaning does not mean deleting all special content. Code, formulas, units, and punctuation may themselves be part of the training content, and whether to keep them should be decided based on the specific task.
Taking a FAQ dataset as an example, the raw data:
faq_data = [
    {
        "question": "  How to change the login password?  ",
        "answer": "<p>Go to personal center and click 'Change Password'.</p>"
    },
    {
        "question": "",
        "answer": "Please contact the administrator."
    },
    {
        "question": "What if I forget my password?",
        "answer": "Click 'Forgot Password'\n\nFollow the prompts to operate."
    },
    {
        "question": "What is the customer service phone number?",
        "answer": "The customer service phone number is 400-123-4567\xa0"
    }
]
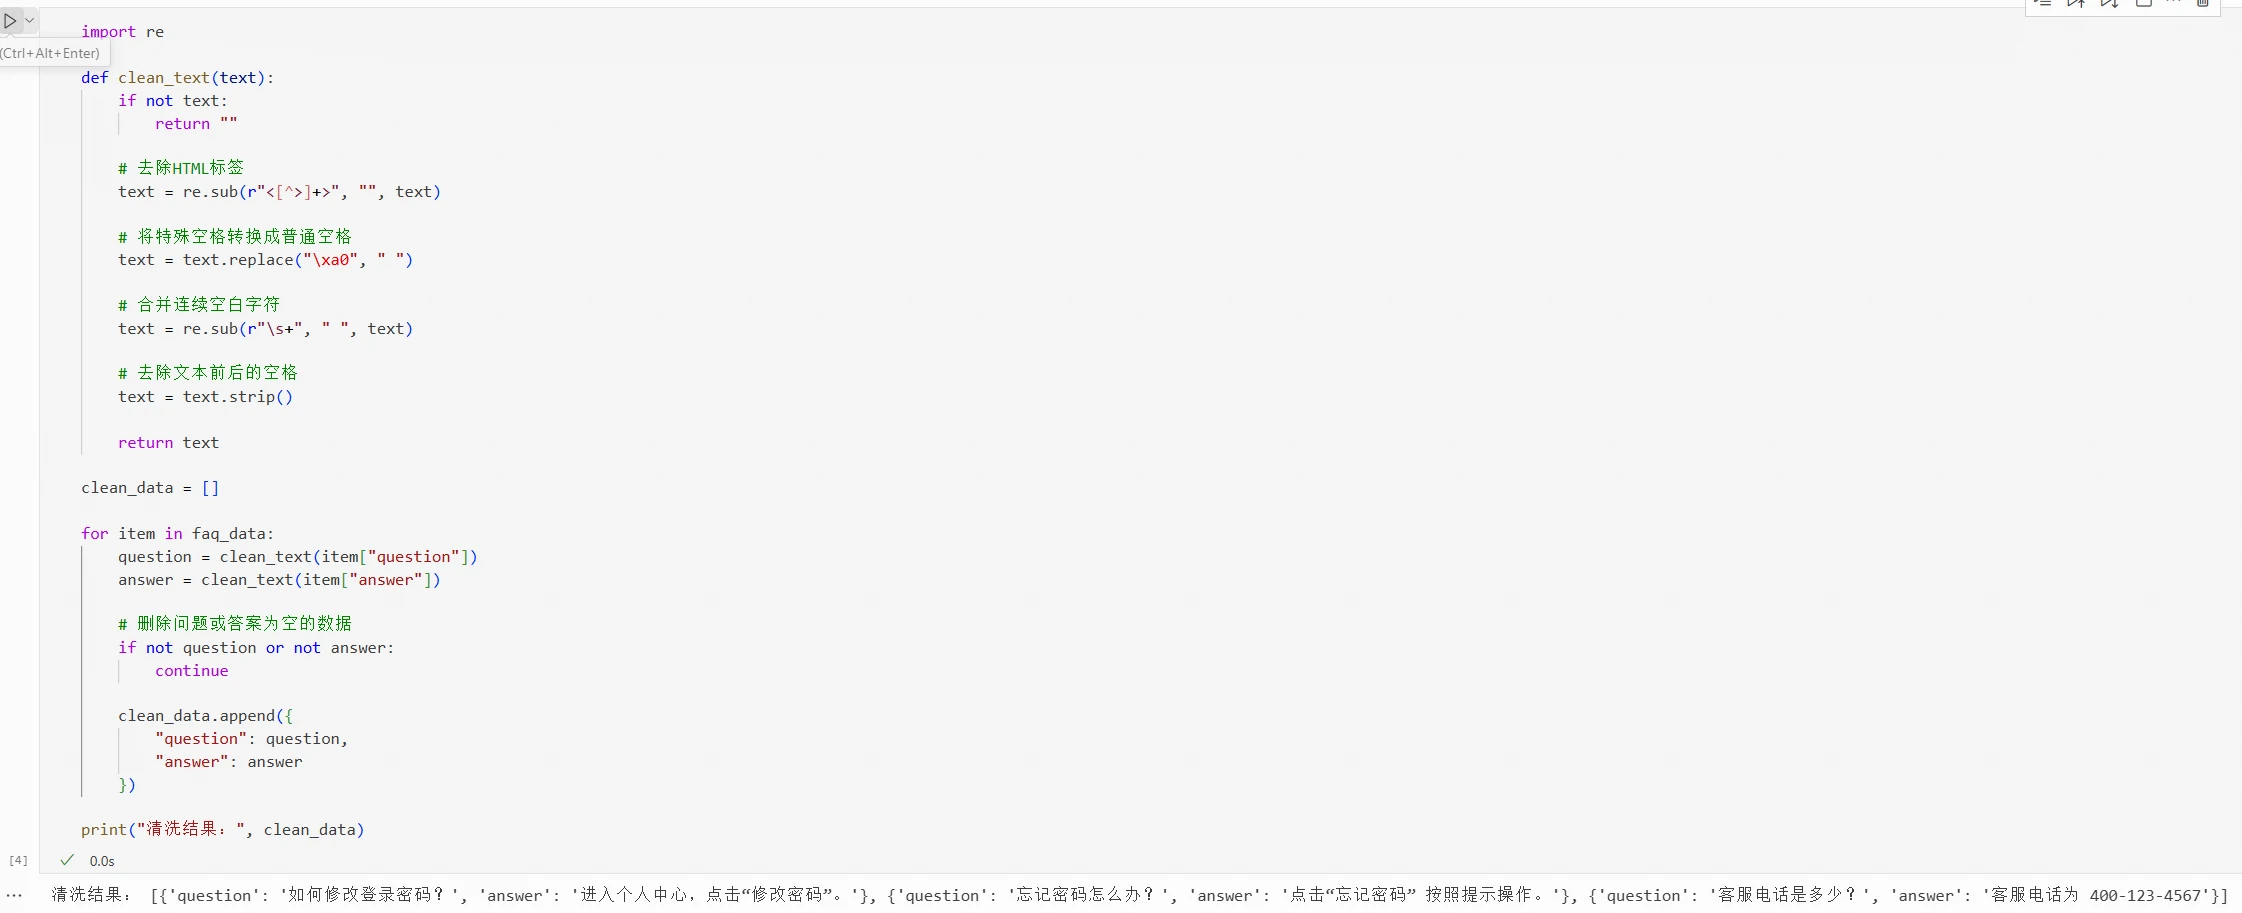
The cleaning code is as follows:
import re

def clean_text(text):
    if not text:
        return ""

    # Remove HTML tags
    text = re.sub(r"<[^>]+>", "", text)

    # Convert special spaces to normal spaces
    text = text.replace("\xa0", " ")

    # Merge consecutive whitespace characters
    text = re.sub(r"\s+", " ", text)

    # Strip leading and trailing spaces
    text = text.strip()

    return text

clean_data = []

for item in faq_data:
    question = clean_text(item["question"])
    answer = clean_text(item["answer"])

    # Delete data where question or answer is empty
    if not question or not answer:
        continue

    clean_data.append({
        "question": question,
        "answer": answer
    })

print("Cleaning result:", clean_data)
The cleaning result is as follows:
The specific cleaning rules in practice need to be determined based on data characteristics.
Is It Necessary to Keep All Duplicate Data?
After aggregating data collected from different sources, duplicate or similar data may appear. The same FAQ might appear in public datasets, product manuals, and customer service knowledge bases simultaneously. Synthesized data may also be similar to existing data content. If there is too much duplicate data, it will reduce the diversity of training data, causing the model to over-learn certain knowledge or expression patterns. Therefore, unified deduplication is needed before training.
Based on the degree of data duplication, data deduplication can be divided into exact data deduplication and similar data deduplication:
Exact data deduplication: Determine whether the content of two data items is completely identical, which can be done through text matching or hash values.
Similar data deduplication: Determine whether two data items, despite different wording, have highly similar content. Methods such as MinHash, SimHash, or vector similarity can be used for detection.
Different types of data require different deduplication rules. Taking a FAQ dataset as an example, you can combine the question and answer into a single complete text, then determine whether different samples are duplicate or similar.
Exact Data Deduplication
Data sample:
faq_data = [
    {
        "question": "How to change the login password?",
        "answer": "Go to personal center and click 'Change Password'."
    },
    {
        "question": "What if I forget my password?",
        "answer": "Click 'Forgot Password' and follow the prompts."
    },
    {
        "question": "How to change the login password?",
        "answer": "Go to personal center and click 'Change Password'."
    }
]
(1) Text Matching
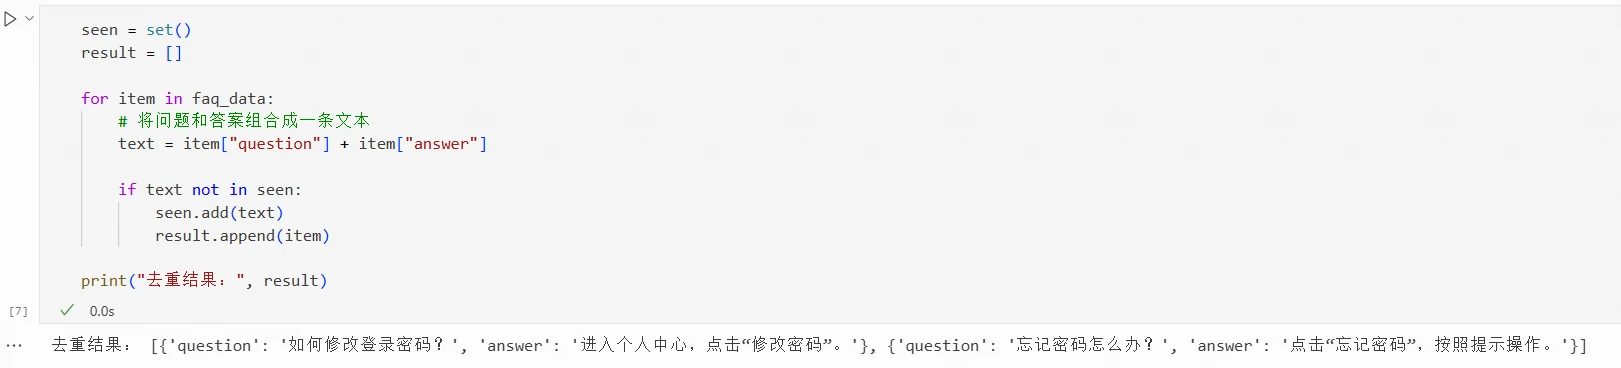
The text matching deduplication code is as follows:
seen = set()
result = []

for item in faq_data:
    # Combine question and answer into a single text
    text = item["question"] + item["answer"]

    if text not in seen:
        seen.add(text)
        result.append(item)

print("Deduplication result:", result)
The deduplication result is as follows:
After processing, only one of the two identical FAQs is retained.
(2) Hash Values
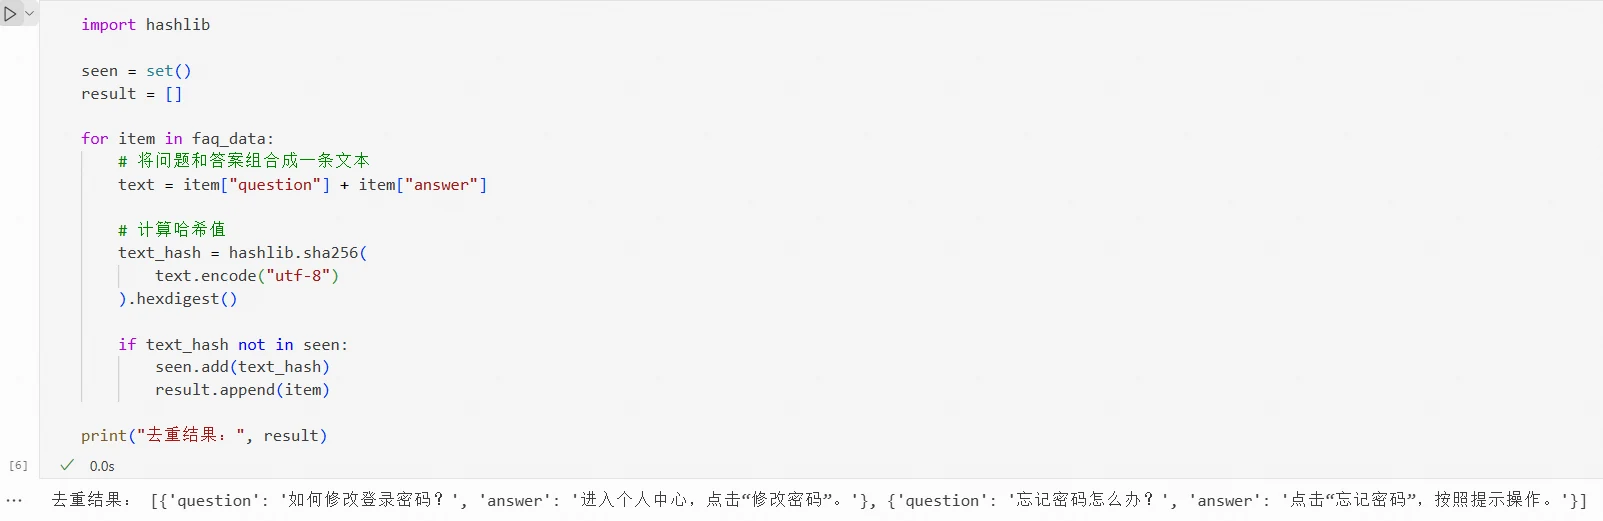
A hash algorithm can convert a piece of text into a fixed-length value. Identical text will produce the same hash value, so you can determine whether data is duplicate by comparing hash values. For example:
import hashlib

seen = set()
result = []

for item in faq_data:
    # Combine question and answer into a single text
    text = item["question"] + item["answer"]

    # Calculate hash value
    text_hash = hashlib.sha256(
        text.encode("utf-8")
    ).hexdigest()

    if text_hash not in seen:
        seen.add(text_hash)
        result.append(item)

print("Deduplication result:", result)
The deduplication result is as follows:
Ordinary hash values can only be used to determine whether content is exactly the same. As long as the text in the question or answer changes, the computed hash value will be different. For data with different wording but similar content, further similarity judgment is needed.
Similar Data Deduplication
Data sample:
faq_data = [
    {
        "question": "How to change the login password?",
        "answer": "Go to personal center and click 'Change Password'."
    },
    {
        "question": "How do I change the login password",
        "answer": "After going to personal center, click 'Change Password'."
    },
    {
        "question": "How to apply for an invoice?",
        "answer": "Go to the order page, select invoice application and submit the information."
    }
]
The first two FAQs have differences in wording but the overall expressed content is quite similar. For this type of data, MinHash, SimHash, or vector similarity can be used for detection.
(1) MinHash
MinHash primarily determines similarity based on the overlap of words or characters in text, making it more suitable for detecting literally similar data. For FAQ data, you can first combine the question and answer into a single text, then split the text into words, characters, or character fragments for calculation.
MinHash is typically used to approximate Jaccard similarity:
J(A,B)=\frac{|A\cap B|}{|A\cup B|}
Where A and B represent the sets of words or characters contained in two pieces of text,
A\cap B
represents the content that both share,
A\cup B
represents all content contained in both. The calculation result is between 0 and 1, with values closer to 1 indicating greater similarity between the two pieces of text.
In Python, you can use the datasketch library to implement MinHash:
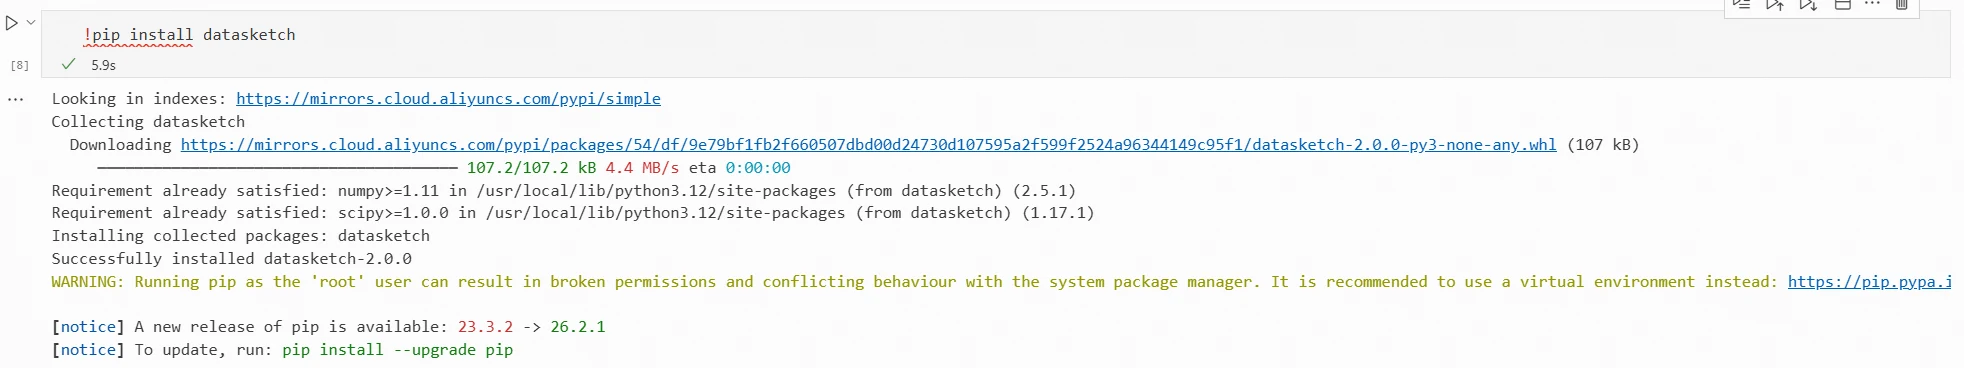
!pip install datasketch
Result display:
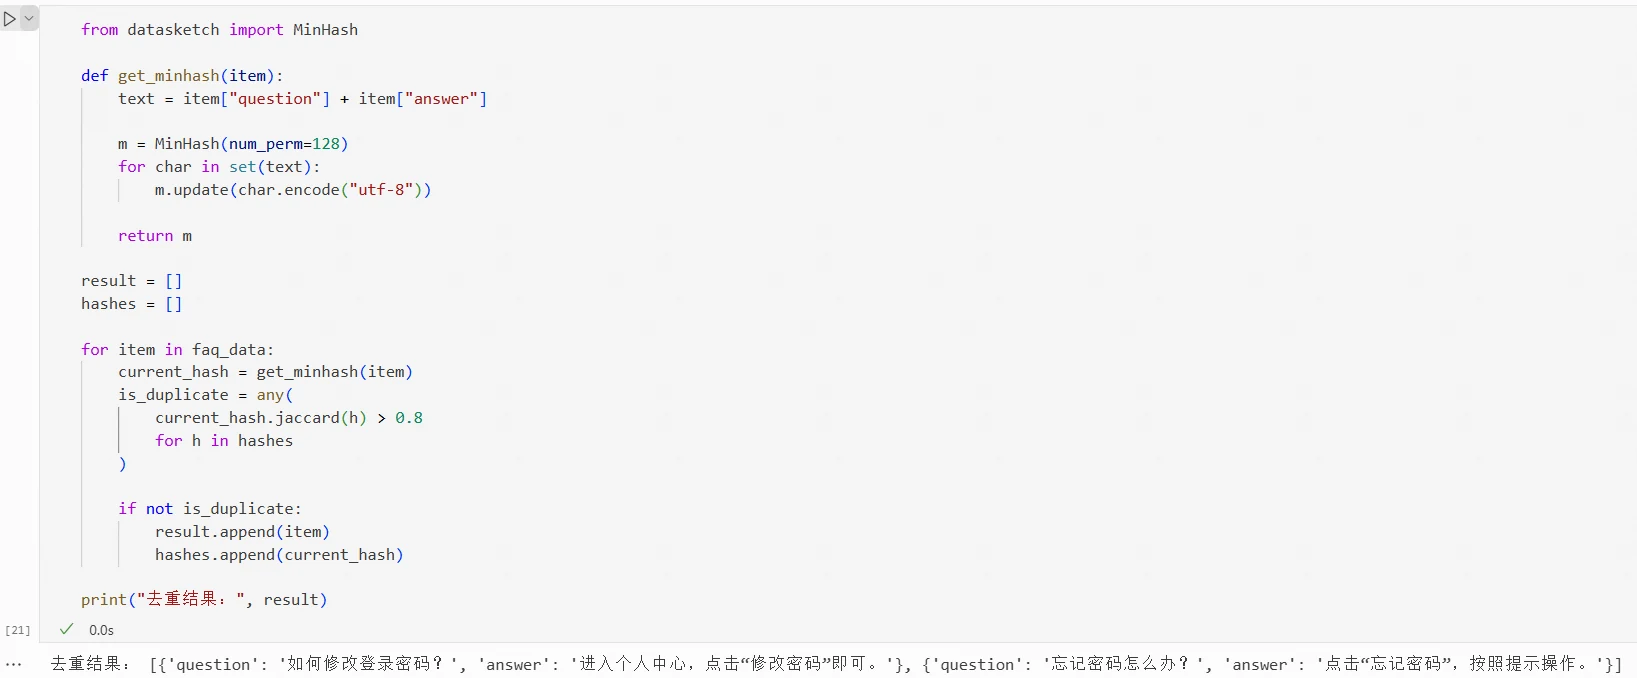
Example code:
from datasketch import MinHash

def get_minhash(item):
    text = item["question"] + item["answer"]

    m = MinHash(num_perm=128)
    for char in set(text):
        m.update(char.encode("utf-8")

    return m

result = []
hashes = []

for item in faq_data:
    current_hash = get_minhash(item)

    is_duplicate = any(
        current_hash.jaccard(h) > 0.8
        for h in hashes
    )

    if not is_duplicate:
        result.append(item)
        hashes.append(current_hash)

print("Deduplication result:", result)
Result display:
(2) SimHash
SimHash generates a fixed-length fingerprint based on text content, then uses the Hamming distance between fingerprints to determine whether texts are similar.
Unlike ordinary Hash, which is mainly used to determine whether content is exactly the same, SimHash can be used to detect texts with similar content. The smaller the Hamming distance between two SimHash fingerprints, the more similar the texts generally are.
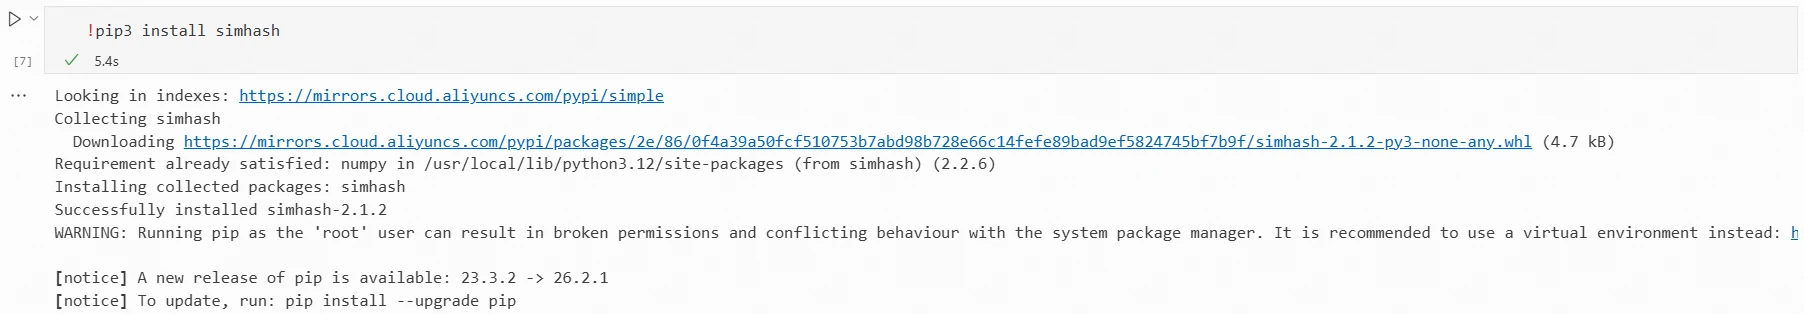
You need to install simhash:
!pip install simhash
Result display:
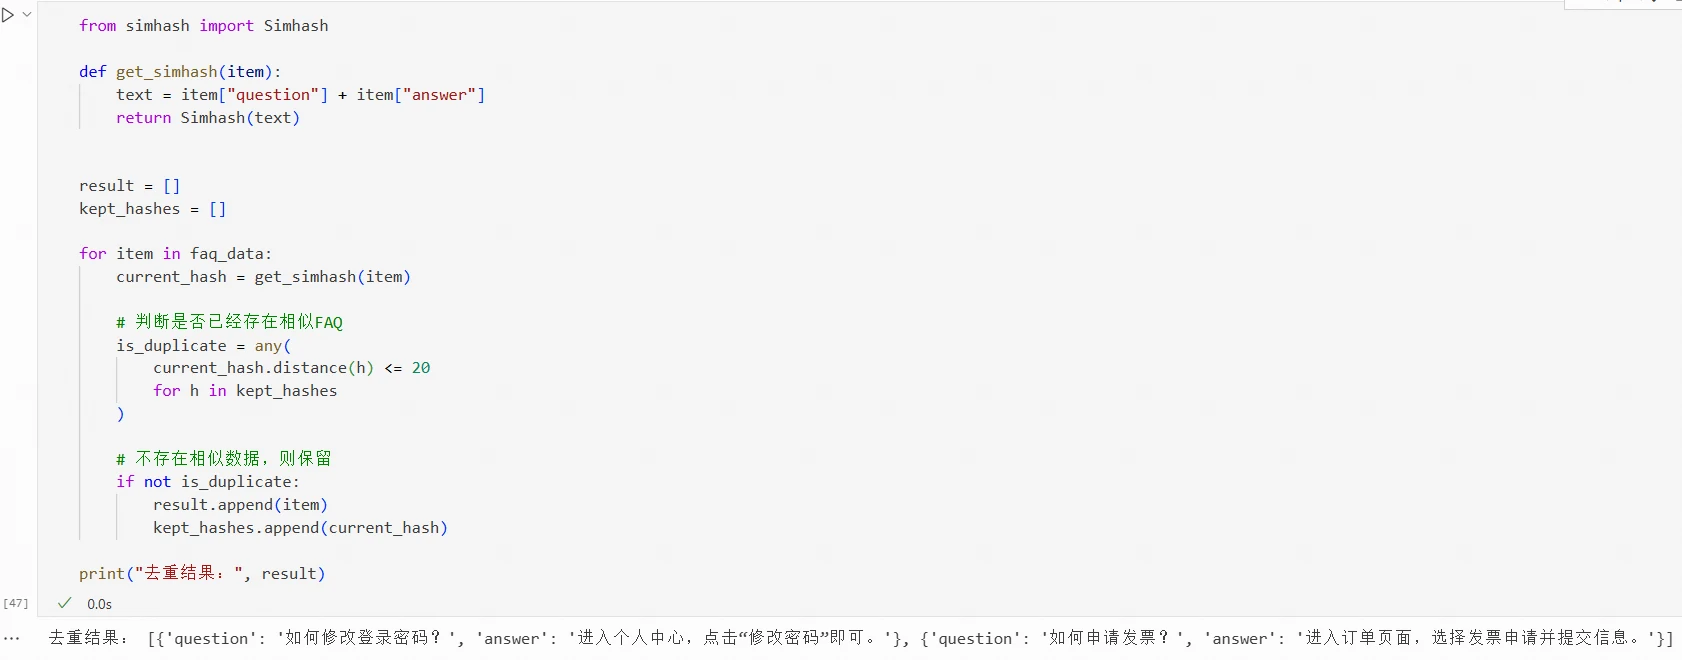
The code for using SimHash to remove similar data is as follows:
from simhash import Simhash

def get_simhash(item):
    text = item["question"] + item["answer"]
    return Simhash(text)

result = []
kept_hashes = []

for item in faq_data:
    current_hash = get_simhash(item)

    # Check if a similar FAQ already exists
    is_duplicate = any(
        current_hash.distance(h) <= 20
        for h in kept_hashes
    )

    # If no similar data exists, keep it
    if not is_duplicate:
        result.append(item)
        kept_hashes.append(current_hash)

print("Deduplication result:", result)
Result display:
(3) Vector Similarity
If two pieces of data use different wording but express similar semantics, you can use a text embedding model to make the judgment.
A text embedding model can convert text into a vector composed of a set of numerical values. For FAQ data, combine the question and answer into a single text, then calculate the cosine similarity between the two text vectors:
Where A and B represent the text vectors corresponding to two FAQs. The higher the cosine similarity, the closer the semantics of the two FAQs.
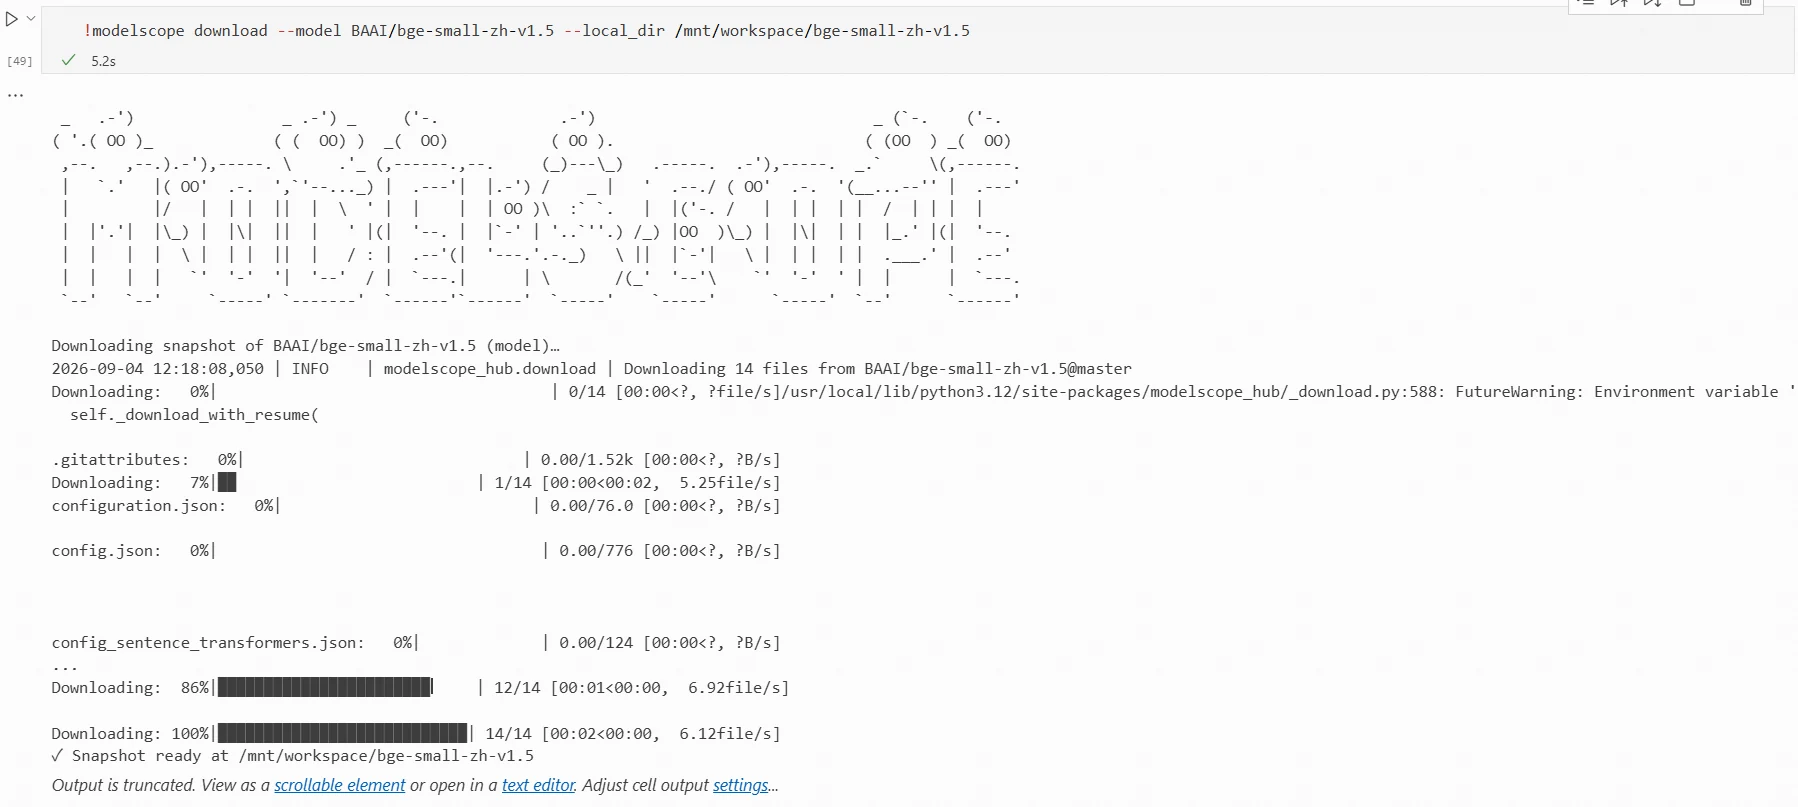
Below, we use the BAAI/bge-small-zh-v1.5 model for calculation. This model is designed for Chinese text embedding tasks, with a model size of approximately 24M, output vector dimension of 512, and is relatively small in scale with fast speed.
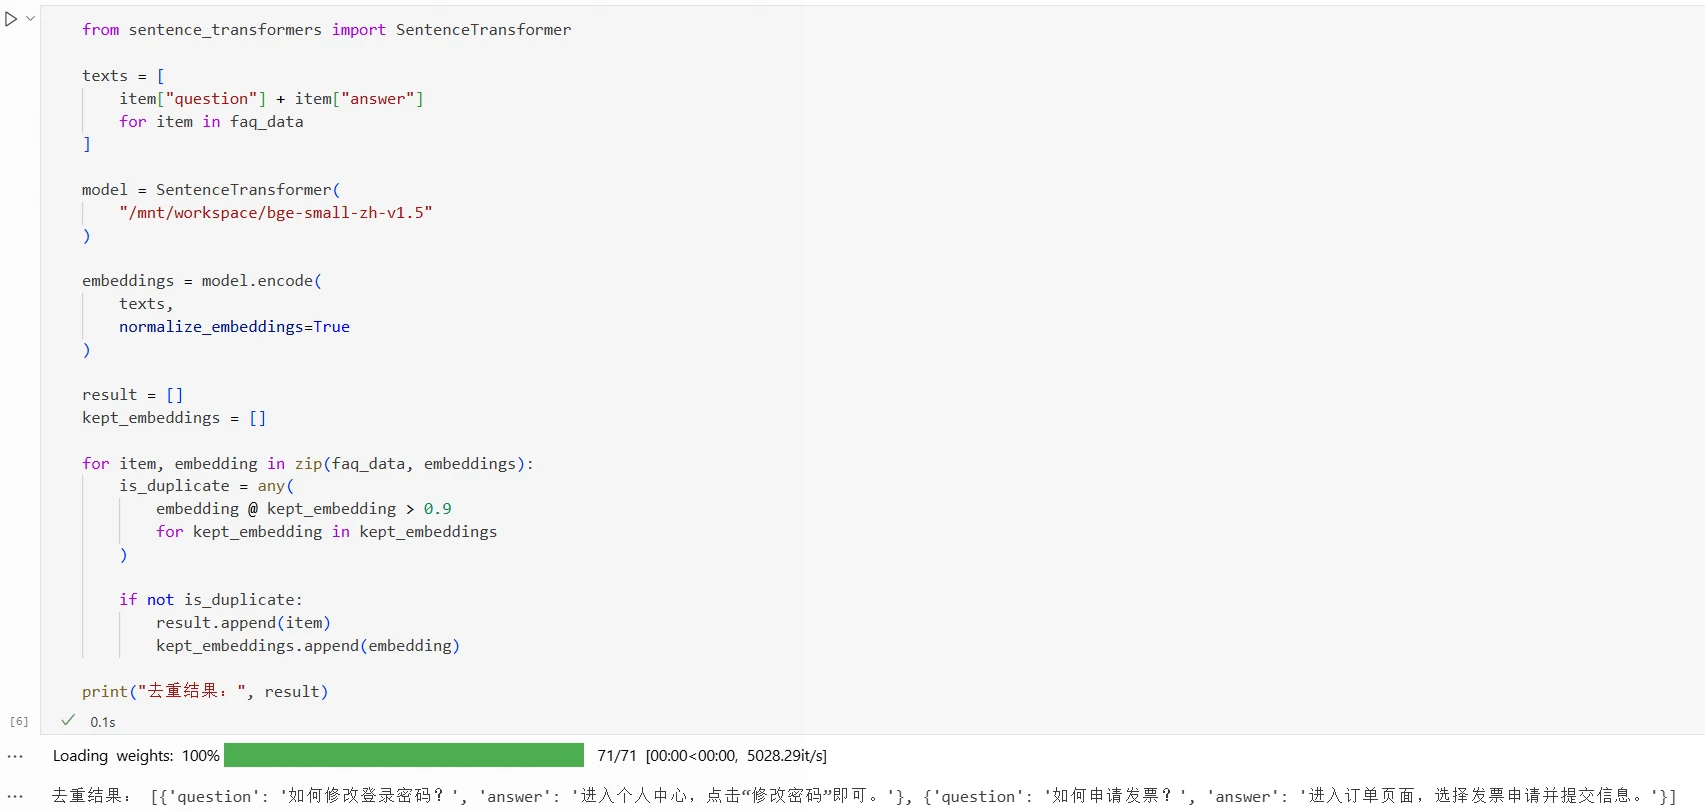
The code for calculating vector similarity to remove similar data is as follows:
from sentence_transformers import SentenceTransformer

texts = [
    item["question"] + item["answer"]
    for item in faq_data
]

model = SentenceTransformer(
    "/mnt/workspace/bge-small-zh-v1.5"
)

embeddings = model.encode(
    texts,
    normalize_embeddings=True
)

result = []
kept_embeddings = []

for item, embedding in zip(faq_data, embeddings):
    is_duplicate = any(
        embedding @ kept_embedding > 0.9
        for kept_embedding in kept_embeddings
    )

    if not is_duplicate:
        result.append(item)
        kept_embeddings.append(embedding)

print("Deduplication result:", result)
Result display:
Different methods are suitable for different types of data deduplication:
Method
Basis of Judgment
Suitable Scenarios
Direct Text Matching
Whether text is exactly identical
Small amounts of identical data
Hash
Whether hash values of text are identical
Large amounts of identical data
MinHash
Degree of word or character overlap in text
Data with literal content similarity
SimHash
Hamming distance between text fingerprints
Data with overall content similarity but minor modifications
Vector Similarity
Semantic similarity of text
Data with different phrasing but similar meaning
In practice, you can first use text matching or Hash to remove exactly identical data, then use MinHash, SimHash, or vector similarity to detect similar data. For detected similar data, you need to decide whether to delete, merge, or retain them based on the similarity threshold and business requirements, to avoid accidentally removing data with training value.
Sensitive Information Should Be Anonymized Before Training
Enterprise business data may contain sensitive information such as names, phone numbers, ID numbers, addresses, and account numbers. Before entering the training dataset, this content needs to be anonymized according to data security requirements.
Data anonymization requires first identifying sensitive information in the data, then selecting appropriate processing methods based on the type of sensitive information.
Methods for Identifying Sensitive Information
Before performing anonymization, you need to first determine which content in the data belongs to sensitive information. For text data, you can use regular expressions or sensitive information recognition models for identification.
(1) Using Regular Expressions
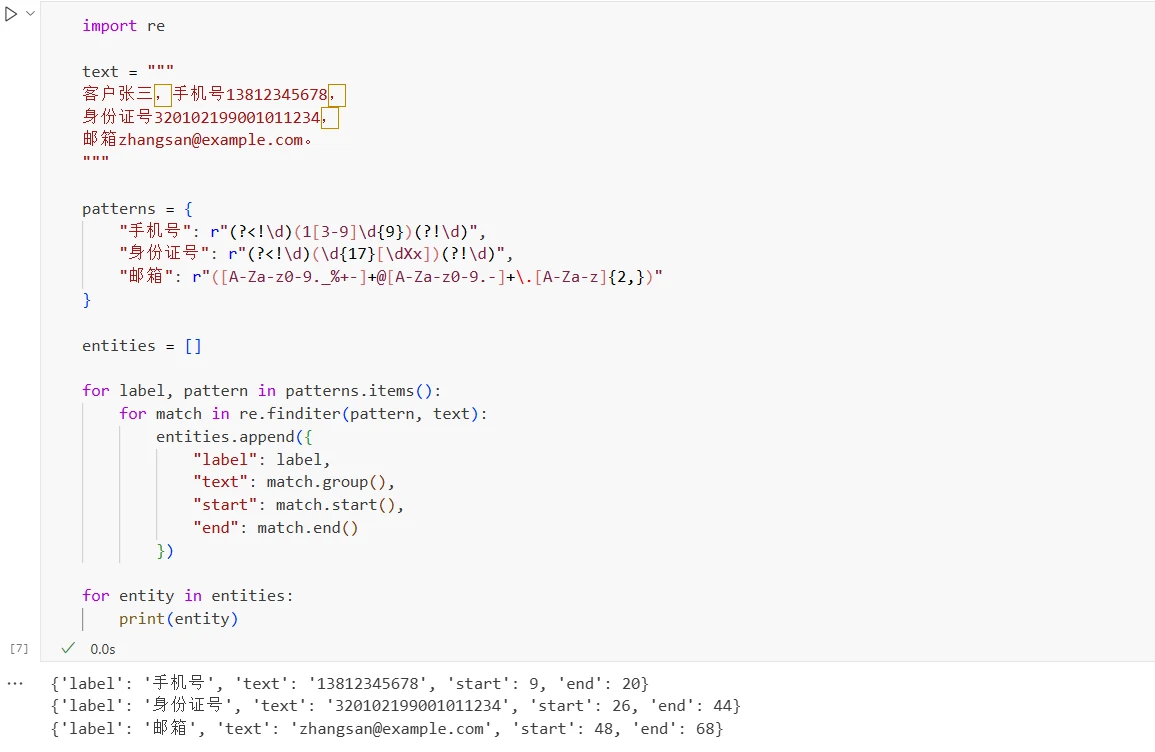
Regular expressions match text based on predefined format rules, making them suitable for identifying information with fixed formats, such as phone numbers, ID numbers, bank card numbers, and email addresses. The code for using regular expressions to identify sensitive information is as follows:
import re

text = """
Customer Zhang San, phone number 13812345678,
ID number 320102199001011234,
email zhangsan@example.com.
"""

patterns = {
    "Phone number": r"(?<!\d)(1[3-9]\d{9})(?!\d)",
    "ID number": r"(?<!\d)(\d{17}[\dXx])(?!\d)",
    "Email": r"([A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,})"
}

entities = []

for label, pattern in patterns.items():
    for match in re.finditer(pattern, text):
        entities.append({
            "label": label,
            "text": match.group(),
            "start": match.start(),
            "end": match.end()
        })

for entity in entities:
    print(entity)
Execution result:
Through regular expressions, you can obtain the content, type, and position of sensitive information in the original text. Subsequently, you can perform anonymization based on this information. Regular expressions mainly rely on format features and are effective for information with fixed structures. In practice, you need to formulate and test corresponding rules based on the format of business data. For information like names and addresses that require contextual understanding, regular expressions alone are difficult to accurately identify.
(2) Using Sensitive Information Recognition Models
For information such as names, addresses, and organizations that require semantic understanding, you can use sensitive information recognition models.
For example, the open-source ZJUICSR/AIguard-pii-detection-fast is a model designed for Chinese personal sensitive information (PII) recognition. It can identify various types of sensitive information such as names, phone numbers, ID numbers, addresses, and email addresses.
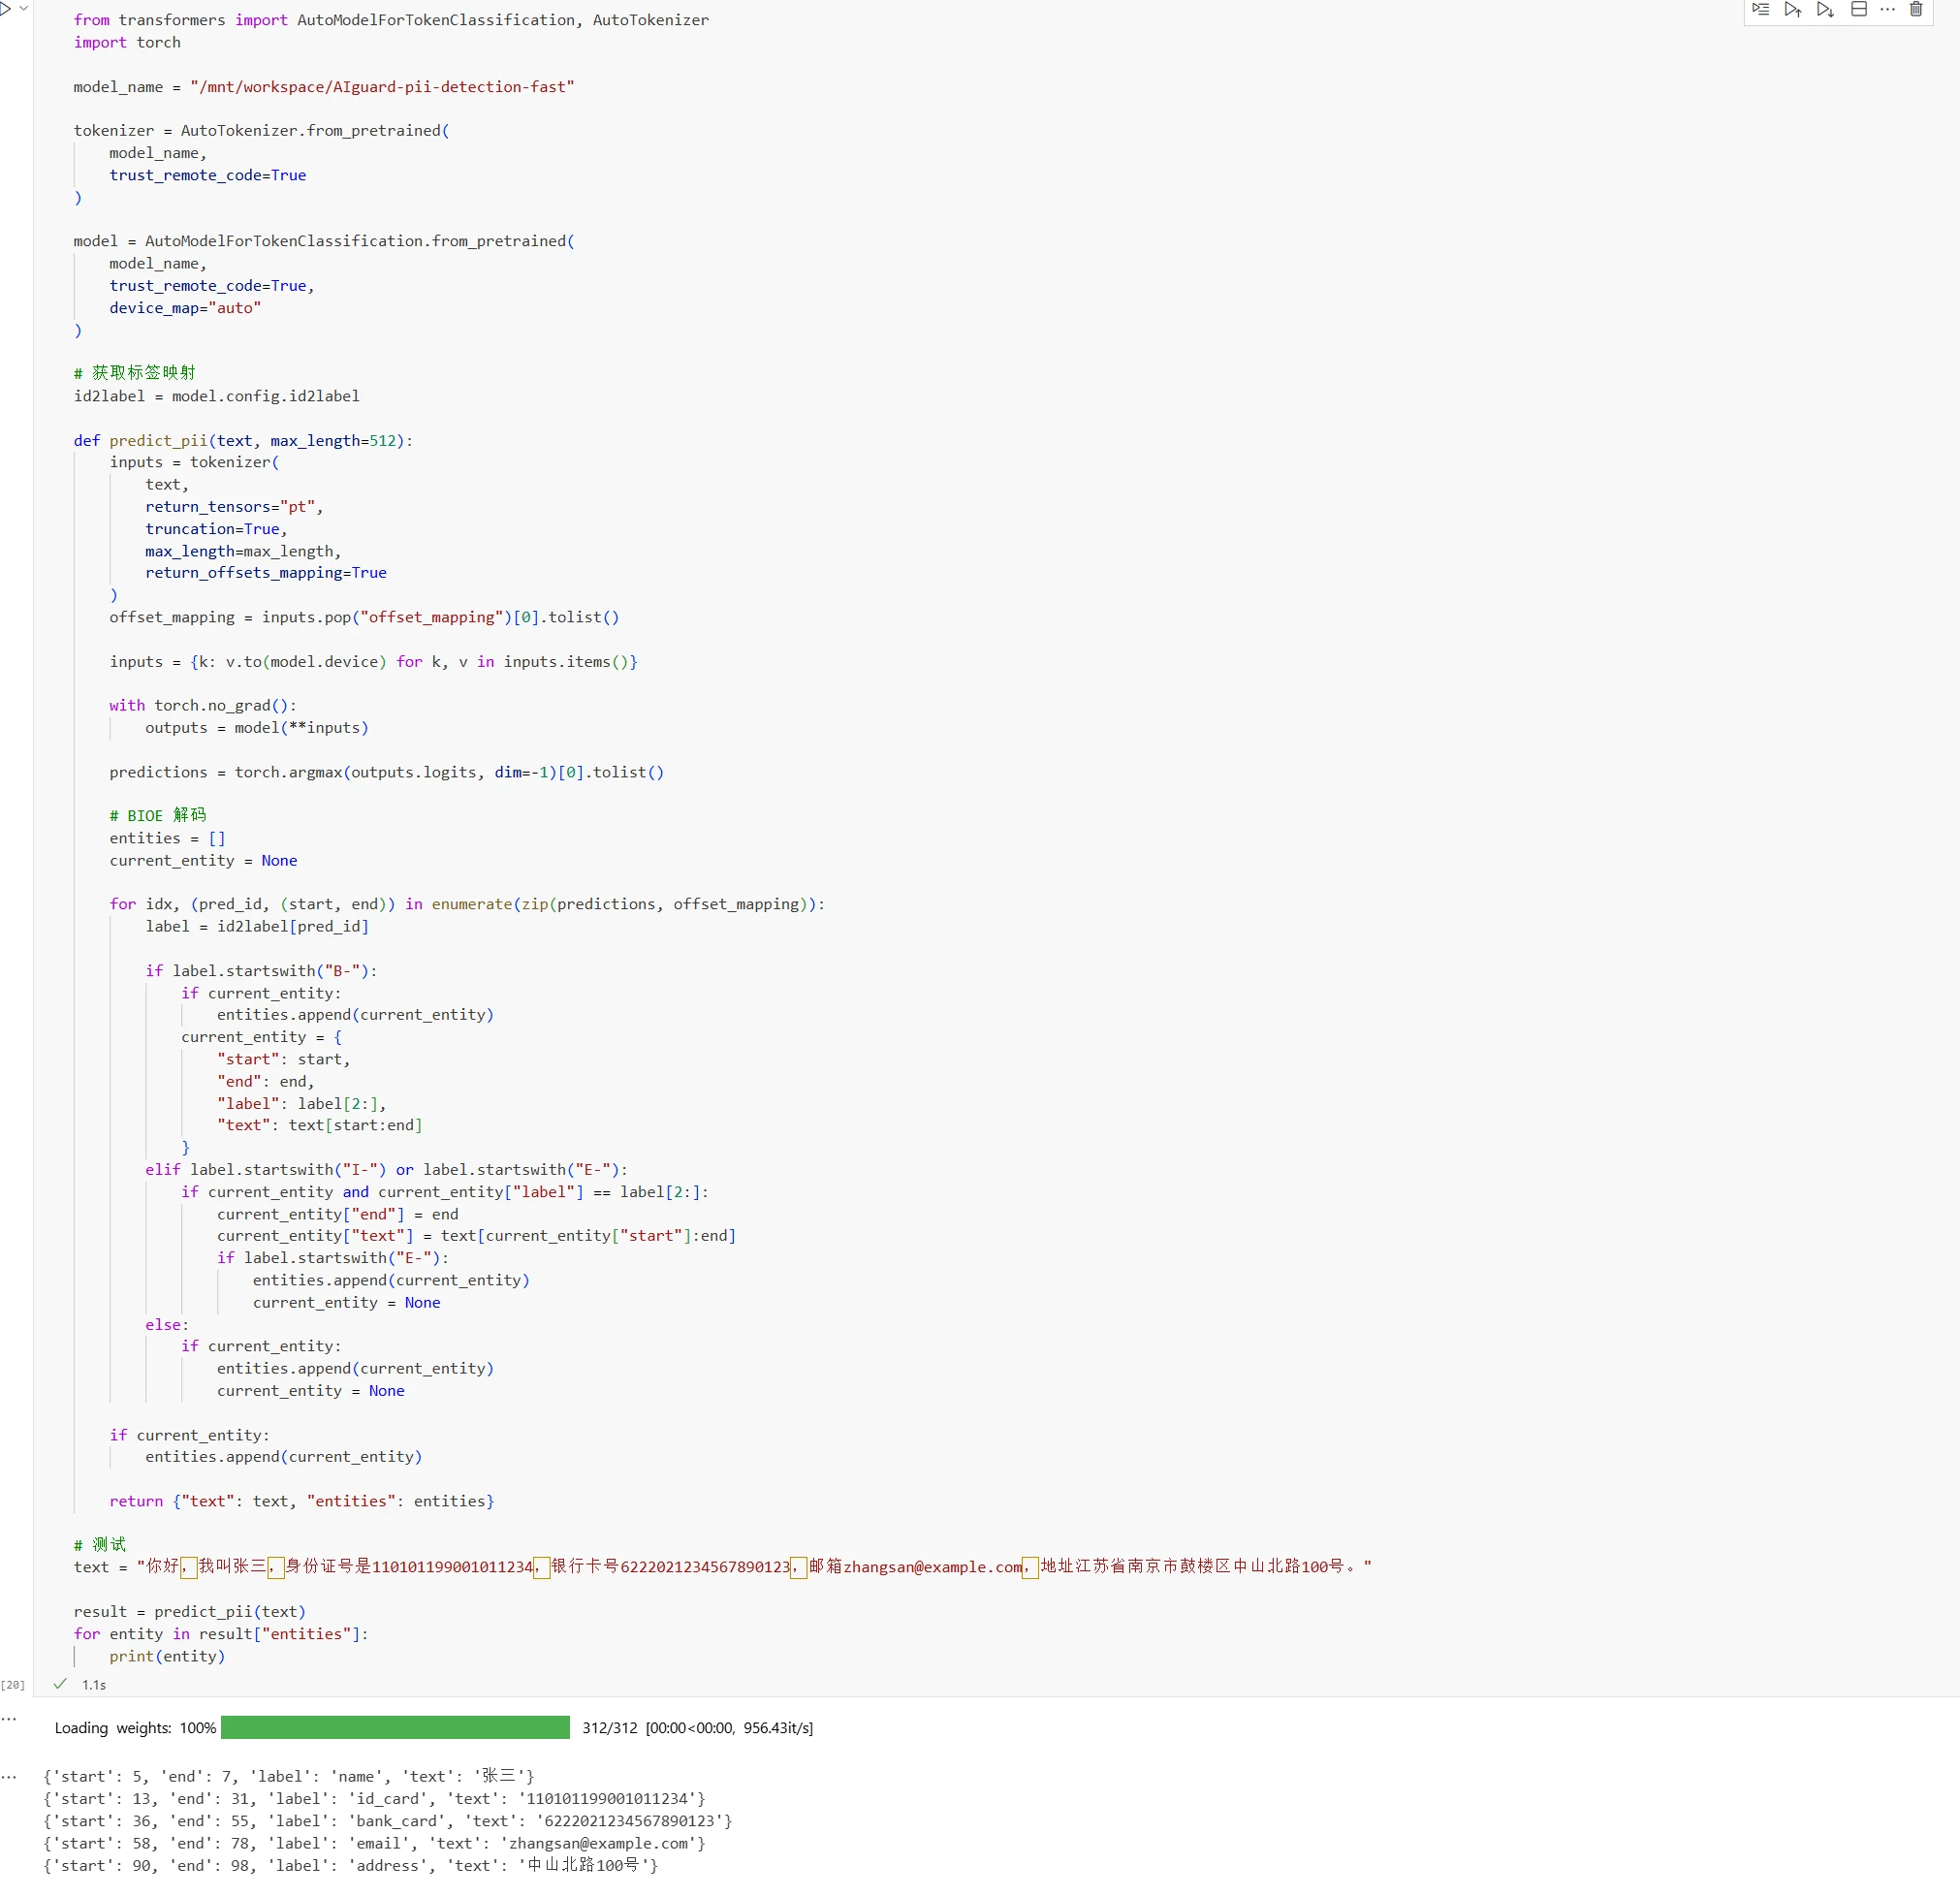
The code for using this model to identify sensitive information is as follows:
from transformers import AutoModelForTokenClassification, AutoTokenizer
import torch

model_name = "/mnt/workspace/AIguard-pii-detection-fast"

tokenizer = AutoTokenizer.from_pretrained(
    model_name,
    trust_remote_code=True
)

model = AutoModelForTokenClassification.from_pretrained(
    model_name,
    trust_remote_code=True,
    device_map="auto"
)

# Get label mapping
id2label = model.config.id2label

def predict_pii(text, max_length=512):
    inputs = tokenizer(
        text,
        return_tensors="pt",
        truncation=True,
        max_length=max_length,
        return_offsets_mapping=True
    )
    offset_mapping = inputs.pop("offset_mapping")[0].tolist()

    inputs = {k: v.to(model.device) for k, v in inputs.items()}

    with torch.no_grad():
        outputs = model(**inputs)

    predictions = torch.argmax(outputs.logits, dim=-1)[0].tolist()

    # BIOE decoding
    entities = []
    current_entity = None

    for idx, (pred_id, (start, end) in enumerate(zip(predictions, offset_mapping):
        label = id2label[pred_id]

        if label.startswith("B-"):
            if current_entity:
                entities.append(current_entity)
            current_entity = {
                "start": start,
                "end": end,
                "label": label[2:],
                "text": text[start:end]
            }
        elif label.startswith("I-") or label.startswith("E-"):
            if current_entity and current_entity["label"] == label[2:]:
                current_entity["end"] = end
                current_entity["text"] = text[current_entity["start"]:end]
                if label.startswith("E-"):
                    entities.append(current_entity)
                    current_entity = None
        else:
            if current_entity:
                entities.append(current_entity)
                current_entity = None

    if current_entity:
        entities.append(current_entity)

    return {"text": text, "entities": entities}

# Test
text = "Hello, my name is Zhang San, ID number is 110101199001011234, bank card number 6222021234567890123, email zhangsan@example.com, address No. 100 Zhongshan North Road, Gulou District, Nanjing City, Jiangsu Province."

result = predict_pii(text)
for entity in result["entities"]:
    print(entity)
Result display:
The identification results include sensitive information content, sensitive information type, and position in the original text. Subsequently, you can select the corresponding anonymization method based on this information.
In practice, regular expressions and sensitive information recognition models are often used in combination. Regular expressions handle information with fixed formats quickly, such as phone numbers and email addresses; models handle information requiring semantic understanding, such as names and addresses.
Anonymization Methods
After completing sensitive information identification, you need to select appropriate processing methods based on the type of sensitive information and training task requirements.
Common anonymization methods include:
(1) Replacement
Replacement involves substituting real sensitive information with other content. Replacement can be divided into fixed replacement and random replacement:
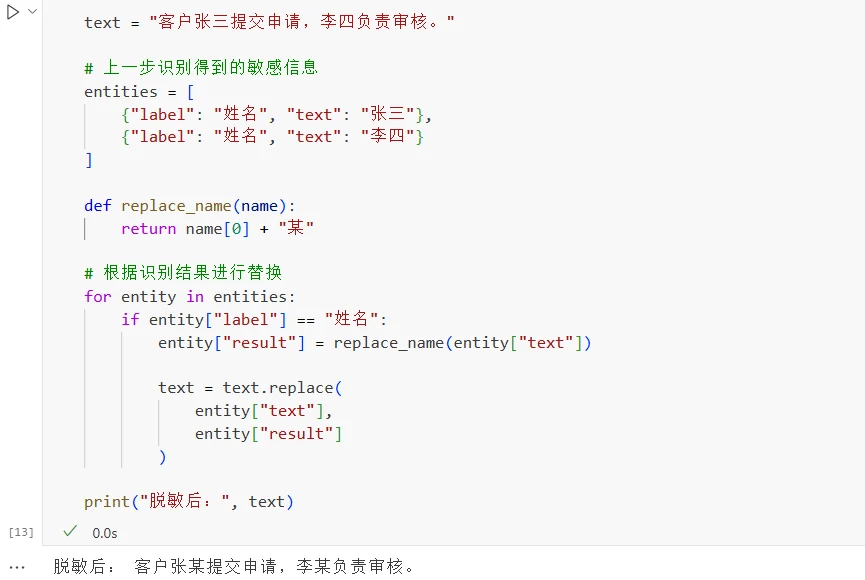
Fixed replacement: Generate replacement results according to fixed rules. For example, uniformly replace the given name in names with "certain person" — "Zhang San" becomes "Zhang certain person", "Li Si" becomes "Li certain person". Since the rules are fixed, the same information will always produce the same result, and there's no need to maintain a mapping table. The processing code is as follows:
text = "Customer Zhang San submitted the application, Li Si is responsible for review."

# Sensitive information identified in the previous step
entities = [
    {"label": "Name", "text": "Zhang San"},
    {"label": "Name", "text": "Li Si"}
]

def replace_name(name):
    return name[0] + "certain person"

# Replace based on identification results
for entity in entities:
    if entity["label"] == "Name":
        entity["result"] = replace_name(entity["text"])

        text = text.replace(
            entity["text"],
            entity["result"]
        )

print("After anonymization:", text)
Result display:
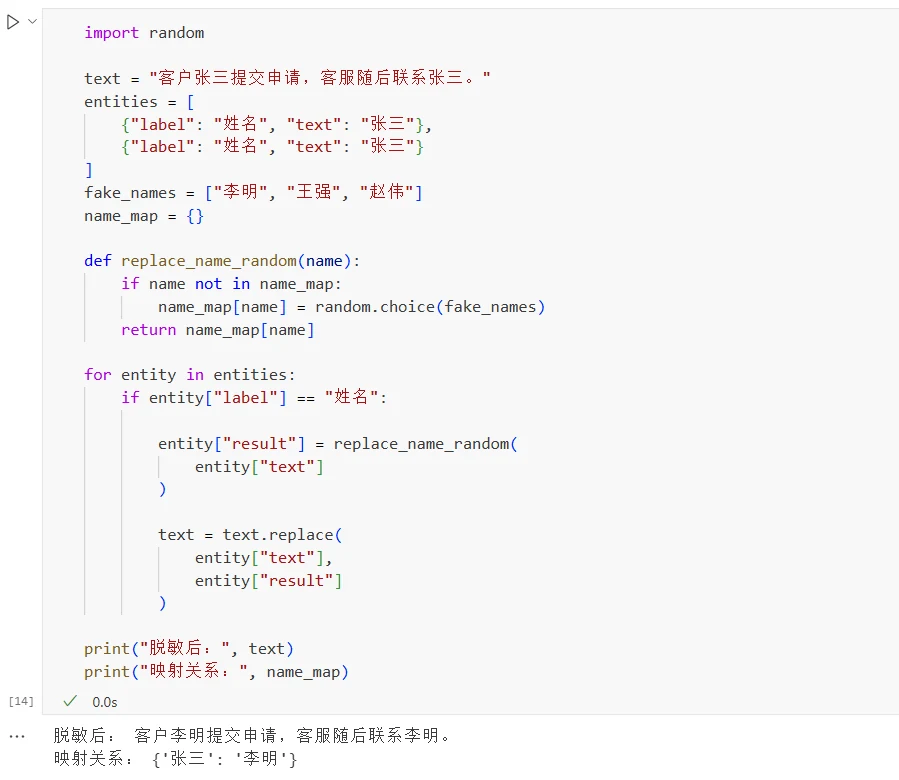
Random replacement: Randomly select fabricated information to replace real information, such as replacing "Zhang San" with "Li Ming". If the same "Zhang San" appears in multiple locations, you need to ensure consistent replacement results. Otherwise, data that originally belonged to the same object might be replaced with different identities, destroying the associations in the data. Therefore, random replacement typically requires creating a mapping table: {"Zhang San":"Li Ming"}. When encountering "Zhang San" again, "Li Ming" is used directly. The processing code is as follows:
import random

text = "Customer Zhang San submitted the application, customer service then contacted Zhang San."
entities = [
    {"label": "Name", "text": "Zhang San"},
    {"label": "Name", "text": "Zhang San"}
]
fake_names = ["Li Ming", "Wang Qiang", "Zhao Wei"]
name_map = {}

def replace_name_random(name):
    if name not in name_map:
        name_map[name] = random.choice(fake_names)
    return name_map[name]

for entity in entities:
    if entity["label"] == "Name":

        entity["result"] = replace_name_random(
            entity["text"]
        )

        text = text.replace(
            entity["text"],
            entity["result"]
        )

print("After anonymization:", text)
print("Mapping relationship:", name_map)
Result display:
(2) Masking
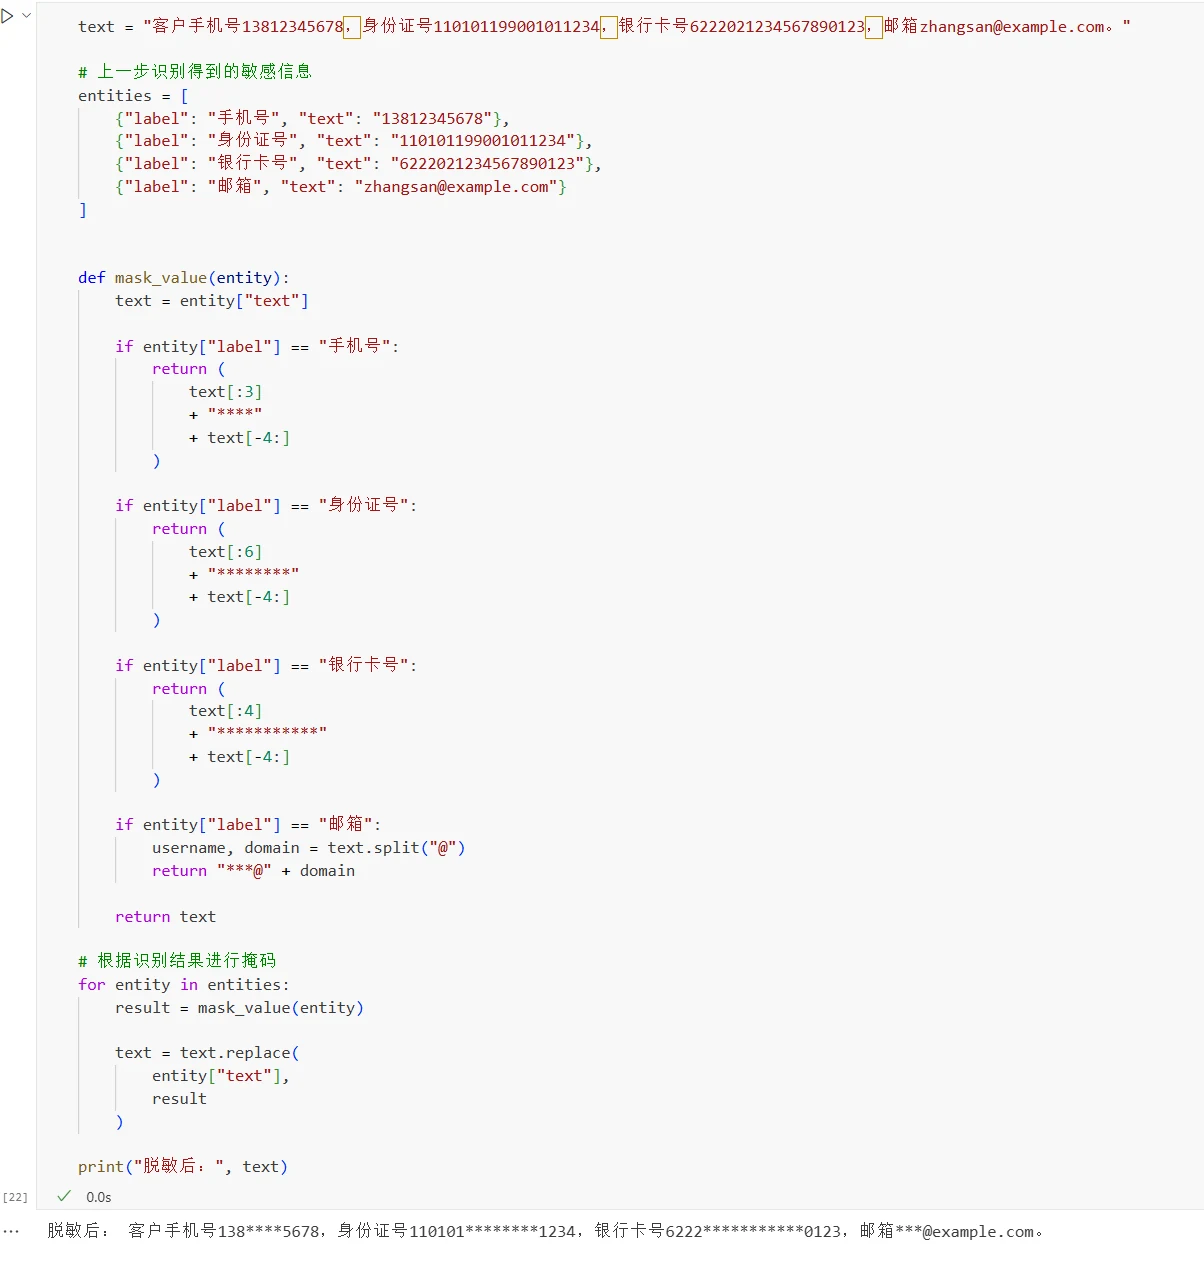
Masking involves hiding parts of sensitive content while retaining partial information, such as phone numbers, ID numbers, bank card numbers, and email addresses.
The processing code is as follows:
text = "Customer phone number 13812345678, ID number 110101199001011234, bank card number 6222021234567890123, email zhangsan@example.com."

# Sensitive information identified in the previous step
entities = [
    {"label": "Phone number", "text": "13812345678"},
    {"label": "ID number", "text": "110101199001011234"},
    {"label": "Bank card number", "text": "6222021234567890123"},
    {"label": "Email", "text": "zhangsan@example.com"}
]

def mask_value(entity):
    text = entity["text"]

    if entity["label"] == "Phone number":
        return (
            text[:3]
            + "****"
            + text[-4:]
        )

    if entity["label"] == "ID number":
        return (
            text[:6]
            + "********"
            + text[-4:]
        )

    if entity["label"] == "Bank card number":
        return (
            text[:4]
            + "***********"
            + text[-4:]
        )

    if entity["label"] == "Email":
        username, domain = text.split("@")
        return "***@" + domain

    return text

# Apply masking based on identification results
for entity in entities:
    result = mask_value(entity)

    text = text.replace(
        entity["text"],
        result
    )

print("After anonymization:", text)
Result display:
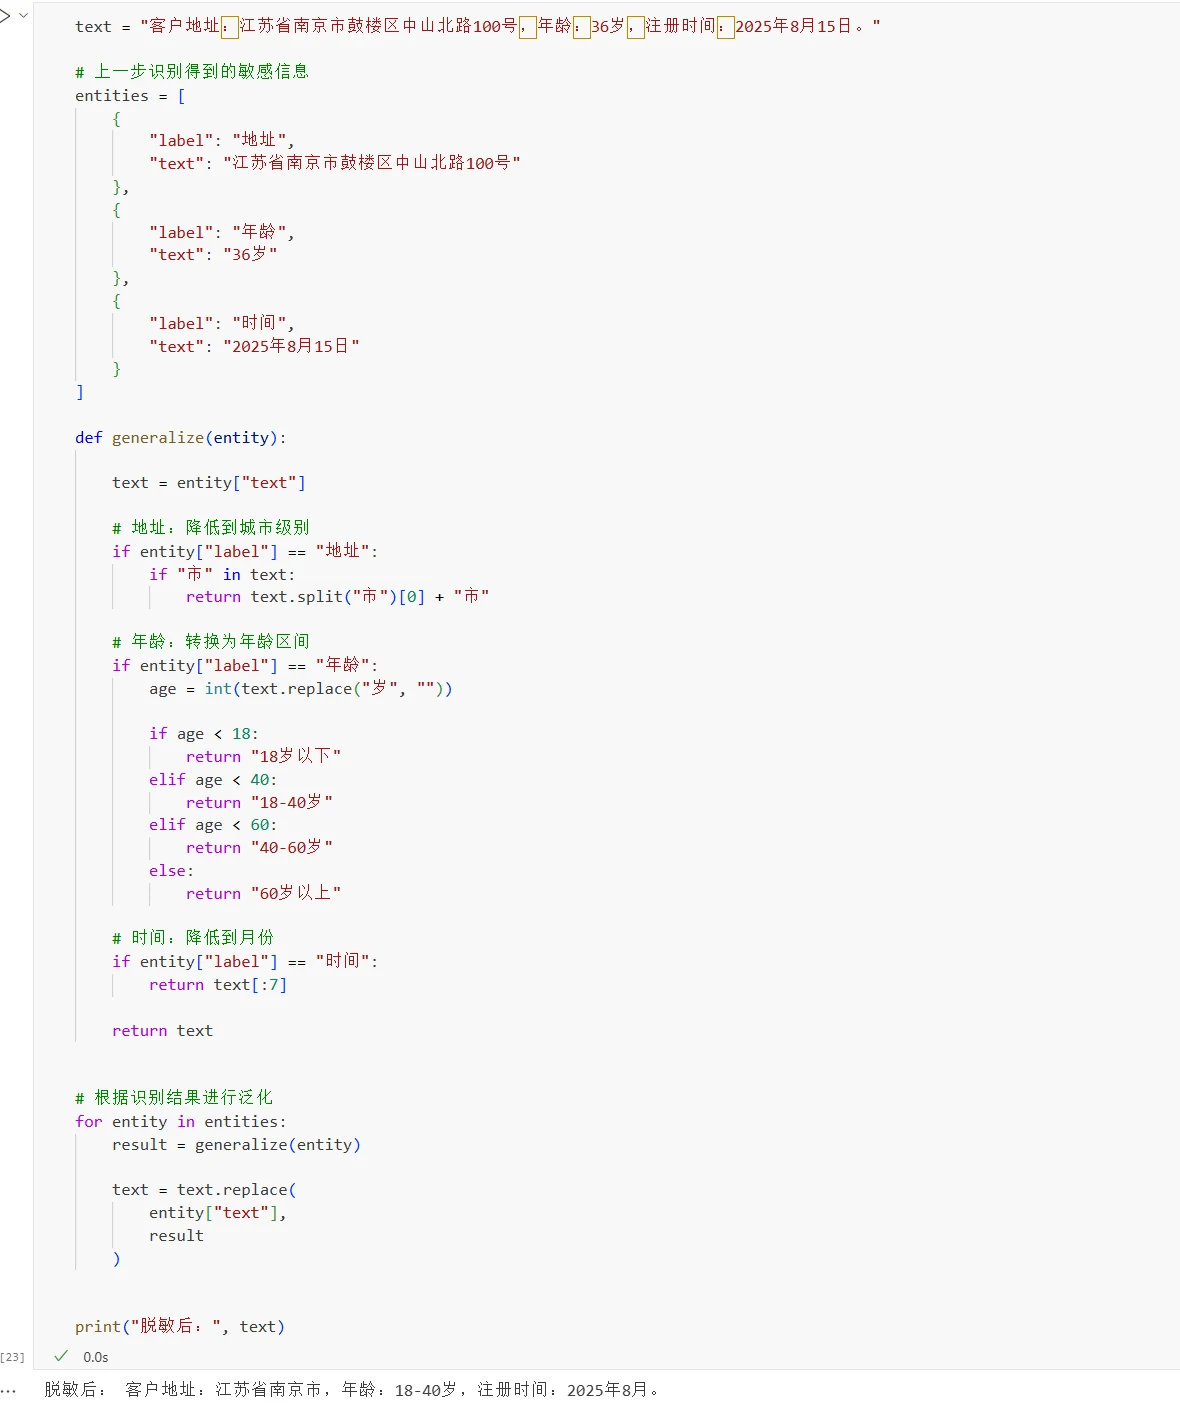
(3) Generalization
Generalization involves reducing information precision to decrease the ability to locate specific objects in the data. It is commonly used for continuous information such as addresses, ages, and times.
The processing code is as follows:
text = "Customer address: No. 100 Zhongshan North Road, Gulou District, Nanjing City, Jiangsu Province, age: 36, registration date: August 15, 2025."

# Sensitive information identified in the previous step
entities = [
    {
        "label": "Address",
        "text": "No. 100 Zhongshan North Road, Gulou District, Nanjing City, Jiangsu Province"
    },
    {
        "label": "Age",
        "text": "36 years old"
    },
    {
        "label": "Time",
        "text": "August 15, 2025"
    }
]

def generalize(entity):

    text = entity["text"]

    # Address: reduce to city level
    if entity["label"] == "Address":
        if "City" in text:
            return text.split("City")[0] + "City"

    # Age: convert to age range
    if entity["label"] == "Age":
        age = int(text.replace("years old", "")

        if age < 18:
            return "Under 18"
        elif age < 40:
            return "18-40"
        elif age < 60:
            return "40-60"
        else:
            return "Over 60"

    # Time: reduce to month level
    if entity["label"] == "Time":
        return text[:7]

    return text

# Apply generalization based on identification results
for entity in entities:
    result = generalize(entity)

    text = text.replace(
        entity["text"],
        result
    )

print("After anonymization:", text)
Result display:
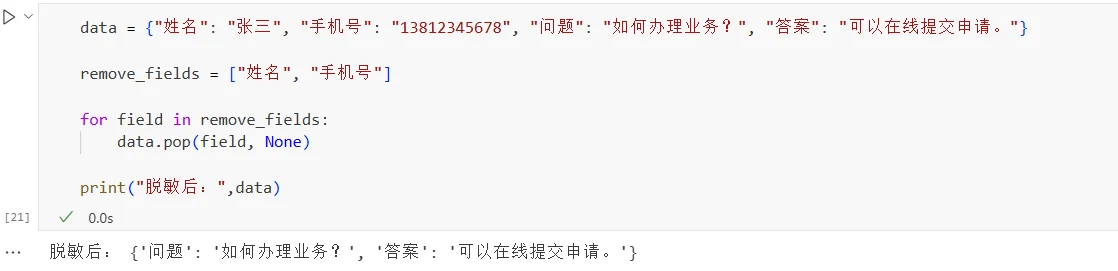
(4) Deletion
For sensitive fields unrelated to the training task, you can delete them directly. If the training task only needs to learn Q&A relationships, you can delete names and phone numbers.
data = {"Name": "Zhang San", "Phone number": "13812345678", "Question": "How to handle the service?", "Answer": "You can submit the application online."}

remove_fields = ["Name", "Phone number"]

for field in remove_fields:
    data.pop(field, None)

print("After anonymization:", data)
Result display:
In practice, the anonymization method needs to be selected based on the training task and data characteristics. When you need to preserve associations between different samples, you can use fixed replacement or random replacement with mapping; when you need to preserve partial information features, you can use masking or generalization; for sensitive information unrelated to the training task, you can delete it directly.
Different business scenarios have different data characteristics, and specific anonymization rules need to be adjusted based on actual requirements. The code in this section is only used to illustrate basic processing methods.
The Final Step: Organizing into the Format Required for Training
After completing data processing, you still need to organize the data into the corresponding format according to the training framework requirements.
Instruction Tuning is a common fine-tuning method for large language models. Training data includes user instructions and the model's expected responses, allowing the model to learn how to complete tasks according to instructions.
Different training frameworks may use different data fields. Common instruction data formats mainly include Alpaca, ShareGPT, and Messages.
Alpaca Format
The Alpaca format has a simple structure, typically using three fields: instruction, input, and output. It is suitable for single-turn instruction data.
{
  "instruction": "Translate the following Chinese text into English",
  "input": "The weather is very nice today.",
  "output": "The weather is very nice today."
}
Where: instruction represents the task the model needs to execute; input represents the input content needed to complete the task; output represents the model's expected response.
If the task itself doesn't require additional input, input can be empty.
For example:
{
  "instruction": "Introduce what machine learning is",
  "input": "",
  "output": "Machine learning is a method that enables computers to learn patterns from data."
}
This format has few fields and a clear structure, making it suitable for single-turn training tasks such as Q&A, classification, and text generation.
Messages Format
Another common approach is using messages to store conversations, where each message contains two main fields: role and content.
For example:
{
  "messages": [
    {
      "role": "system",
      "content": "You are a professional customer service assistant."
    },
    {
      "role": "user",
      "content": "When will my order arrive?"
    },
    {
      "role": "assistant",
      "content": "Please provide the order number, and I'll help you check."
    }
  ]
}
Where, system is used to set the model's role, task requirements, or response rules, user represents user input, and assistant represents the model's expected response.
The Messages format also supports multi-turn conversations. You just need to continue adding user and assistant messages in the actual conversation order.
For example:
{
  "messages": [
    {
      "role": "system",
      "content": "You are a professional customer service assistant."
    },
    {
      "role": "user",
      "content": "How to change the login password?"
    },
    {
      "role": "assistant",
      "content": "Go to account settings and select 'Change Password'."
    },
    {
      "role": "user",
      "content": "What if I forgot the original password?"
    },
    {
      "role": "assistant",
      "content": "You can select 'Forgot Password' on the login page, verify through phone number or email, and then reset the password."
    }
  ]
}
ShareGPT Format
ShareGPT is one of the common dialogue data formats in open-source large model training. It typically uses conversations to store complete dialogues and uses human and gpt to distinguish between the user and the model.
For example:
{
  "conversations": [
    {
      "from": "human",
      "value": "Translate the following Chinese text into English: The weather is very nice today."
    },
    {
      "from": "gpt",
      "value": "The weather is very nice today."
    }
  ]
}
The ShareGPT format can also store multi-turn dialogues:
{
  "conversations": [
    {
      "from": "human",
      "value": "Help me write a leave request email."
    },
    {
      "from": "gpt",
      "value": "Please tell me the leave time and reason."
    },
    {
      "from": "human",
      "value": "I have a cold, taking two days of sick leave."
    },
    {
      "from": "gpt",
      "value": "Okay, here is a leave request email..."
    }
  ]
}
How to Choose a Data Format
The Alpaca, Messages, and ShareGPT formats essentially describe the model's input and expected output, just with different field organizations.
You can choose based on the task type and training framework:
Data Format
Main Features
Suitable Scenarios
Alpaca
Organizes data using instruction, input, and output
Single-turn instructions, Q&A, classification
Messages
Stores conversations using messages, distinguishing roles through role
Single-turn or multi-turn dialogues
ShareGPT
Stores conversations using conversations, distinguishing roles through from
Single-turn or multi-turn dialogues
Different formats can generally be converted between each other. For example, a piece of Alpaca data can be converted into a set of user and assistant messages. The human and gpt in ShareGPT can also be converted to user and assistant respectively. During actual training, you should first confirm the data format and model template supported by the training framework, then organize the data according to the corresponding requirements.
Model code and related files can be found at: https://www.modelscope.cn/gallery/liucong/b41e2395-f795-400f-bafd-e53ed7f5c8ca