When a customer service call ends, has the user's problem been resolved? Did the customer service representative miss any important conditions? When there are few recordings, you can listen to them one by one; when there are many recordings, manual sampling makes it difficult to cover every call.
Traditional customer service quality inspection mainly relies on manual sampling, which not only requires considerable time but also makes it difficult to cover all calls. Using speech recognition and audio multimodal models, you can analyze call content, speakers, emotions, service tone, and interactions between both parties from phone recordings. Then, a large language model can complete scoring and generate quality inspection reports according to quality inspection rules.
This chapter uses a customer service call record from a language training institution to walk through the process from recording to quality inspection report.
Different business scenarios have different requirements for customer service quality. Before conducting automated quality inspection, it is necessary to clarify which issues quality inspection needs to focus on, and formulate corresponding quality inspection rules based on actual business requirements.
Customer service representatives at language training institutions typically need to handle course consultations, class notifications, leave requests, course adjustments, learning feedback, and after-sales service over the phone.
During quality inspection, it is necessary to check whether the customer service representative correctly understood customer needs, whether answers are complete and accurate, whether follow-up processing methods were provided for issues that cannot be immediately determined, and whether there are improper promises. At the same time, service attitude and communication process during the call also affect service quality, such as whether the customer service representative is impatient, perfunctory, or blaming, whether they interrupt the customer, and whether the customer shows negative emotions.
This information cannot be obtained solely through call transcription text; it also needs to be analyzed in conjunction with speaker information as well as emotions, tone, and interactions between both parties in the phone recording.
After determining scenario requirements, these requirements need to be further organized into specific quality inspection rules, clarifying what content needs to be checked in a call and the corresponding scoring standards for different issues, providing a basis for subsequent automated judgment and scoring.
Based on the service requirements of phone customer service at language training institutions, quality inspection rules are formulated from aspects such as demand response, information accuracy, problem resolution, service attitude, call behavior, and customer emotions, as shown in the following table.
Sign in to join the discussion
| Quality Inspection Item | Main Inspection Content | Score |
| Opening and Identity Statement | Whether to proactively greet, state the institution and personal identity, and ask about customer needs | 5 |
| Demand Identification and Response Completeness | Whether to identify issues raised by customers and respond effectively item by item | 20 |
| Information Accuracy and Risk Control | Whether to fabricate uncertain information, whether there are improper promises about learning outcomes | 15 |
| Problem Resolution and Promise Closure | Whether core customer problems are resolved, whether follow-up processing methods are explained when immediate resolution is not possible | 15 |
| Service Attitude and Professional Wording | Whether there are expressions of impatience, blame, perfunctoriness, insults, or shirking responsibility | 15 |
| Interruption and Call Rhythm | Whether there is frequent interruption of customers, interrupting, or abnormal rhythms that significantly affect communication | 10 |
| Customer Emotion and Service Recovery | Whether customers show significant negative emotions, whether customer service representatives explain and appease in a timely manner | 10 |
| Closing and Pending Item Confirmation | Whether to end politely and confirm unfinished items | 10 |
| Total | 100 |
Subsequent automated quality inspection will judge and score item by item according to these rules. Different quality inspection items require different information. For example, demand identification, information accuracy, and problem resolution are mainly judged based on call content, while service attitude, customer emotions, and interruption situations need to be analyzed in conjunction with phone recordings. Finally, comprehensive quality inspection is completed based on these analysis results.
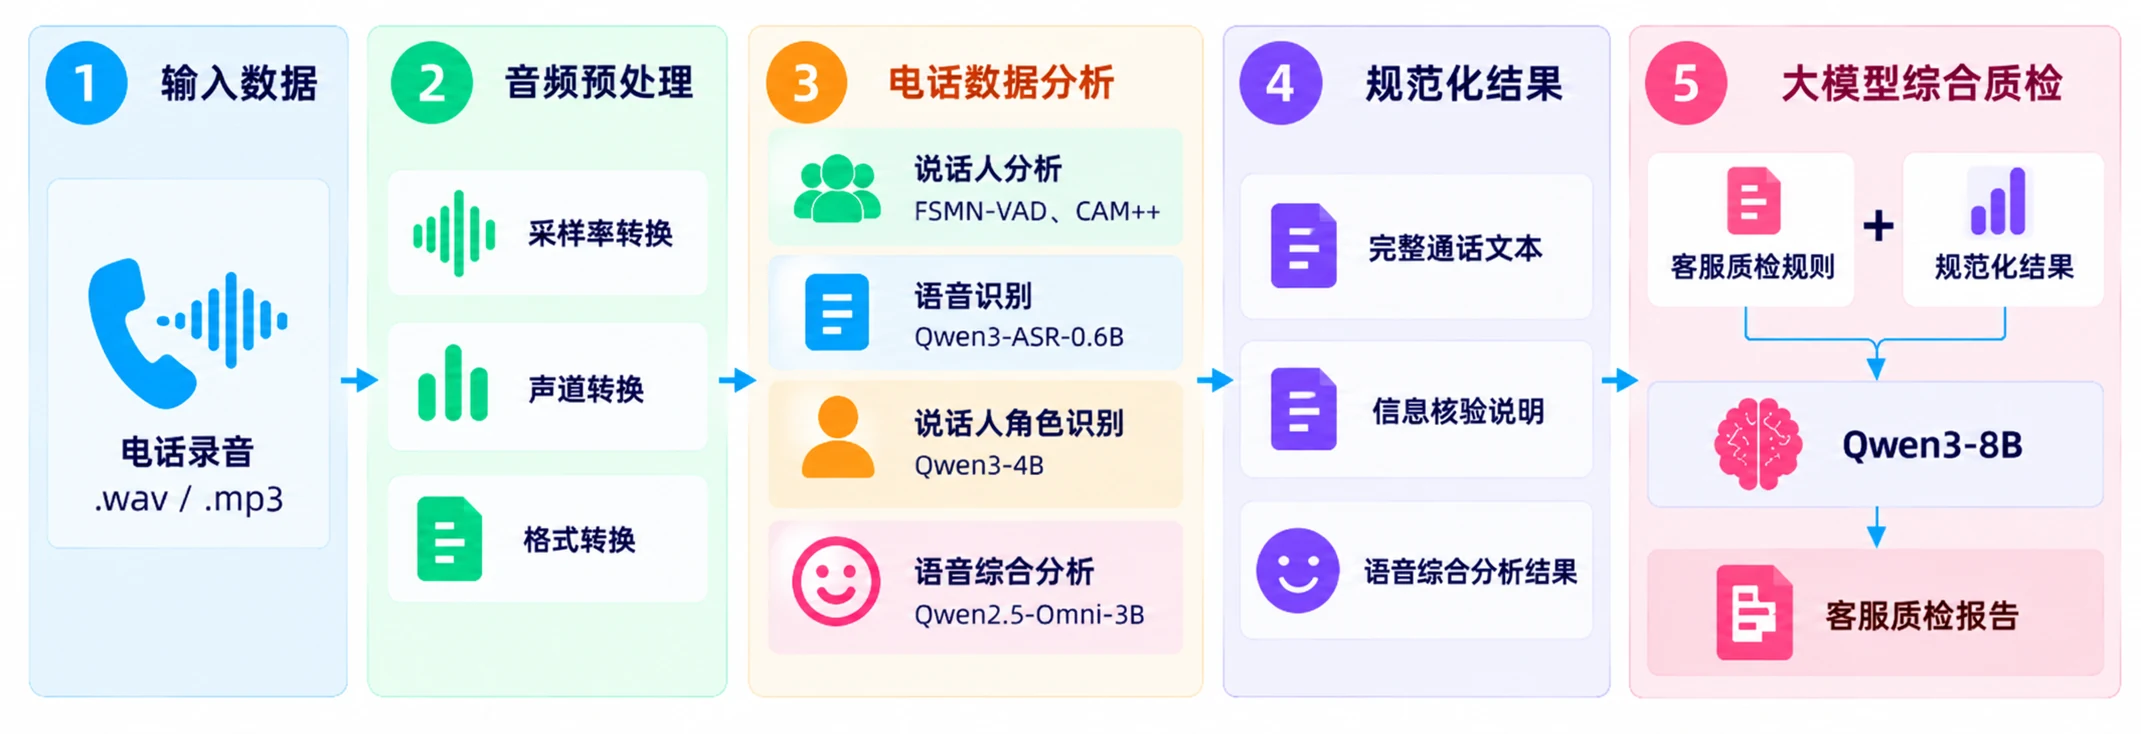
Based on the scenario requirements above, the system first obtains call text and speaker information from the phone recording, then analyzes customer emotions, customer service tone, and interactions between both parties in conjunction with the recording. Finally, these analysis results are handed over to the large language model together with customer service quality inspection rules for comprehensive judgment, scoring, and generating quality inspection reports. The entire automated quality inspection process is shown in the following figure.
The entire process can be divided into two parts: phone data analysis and comprehensive quality inspection.
After the phone recording is input into the system, the audio format needs to be unified first, converting the sampling rate and channels into a form that subsequent models can process.
The processed audio uses FSMN-VAD to detect valid speech regions, and combines CAM++ to distinguish different speakers, obtaining the speaking time of each speaker. At this point, speaker numbers such as spk0 and spk1 are obtained, but their identities cannot be directly determined.
Speech recognition is completed using Qwen3-ASR-0.6B. The model converts recordings to text and records the corresponding time for each text segment through timestamps. By aligning speech recognition results with speaker analysis results according to time, call text with speaker numbers and time information can be obtained. Subsequently, based on the dialogue content of different speakers, the smaller Qwen3-4B model is used to determine their roles in this call, converting speaker numbers to "customer service" and "customer". Finally, complete call text with role and time information can be obtained, for example:
Round 1 [Customer Service] 0.00-4.82 seconds: ...
Round 2 [Customer] 5.10-10.36 seconds: ...
The voice in the phone also contains information that cannot be directly reflected in text, such as customer service emotions and tone, customer emotion changes, and interactions between both parties. Qwen2.5-Omni-3B is used to analyze phone recordings, and in conjunction with call text, determine whether customer service representatives show impatience, perfunctoriness, blame, or stiff tone, whether customers show significant negative emotions, and whether customer service representatives respond appropriately. At the same time, it analyzes whether there are obvious interruptions or customer interruptions during the call.
The main analysis modules are shown in the following table.
| Analysis Task | Model or Component | Main Output |
| Speech Recognition | Qwen3-ASR-0.6B | Recognized text with time information |
| Speaker Analysis | FSMN-VAD, CAM++ | Different speakers and speaking times |
| Speaker Role Identification | Qwen3-4B | Customer service, customer roles |
| Speech Comprehensive Analysis | Qwen2.5-Omni-3B | Customer service emotions and tone, customer emotions and service response, call interaction |
These analysis results need to be organized into a unified format for subsequent large language models to read directly. For example:
【Call Transcription】
Round 1 [Customer Service] XX.XX-XX.XX seconds: ...
Round 2 [Customer] XX.XX-XX.XX seconds: ...

【Information Verification Note】
This analysis did not provide enterprise business rules or standard answers.
For business information such as course schedules and leave rules, only whether the customer service representative provided a clear response can be judged, and the accuracy of the content cannot be verified.

【Speech Comprehensive Analysis】

Customer Service Emotions and Tone:
Emotional Expression: ...
Service Tone: ...
Abnormal Situations: ...

Customer Emotions and Service Response:
Customer Emotions: ...
Emotional Changes: ...
Service Response: ...

Call Interaction:
Interrupting: ...
Customer Interruptions: ...
Other Abnormalities: ...

Analysis Notes: ...
The normalized results retain complete call text, speaker roles, and speech comprehensive analysis results. Business content such as customer needs, response completeness, problem resolution, promises, and compliance are no longer analyzed separately in advance, but are judged by the large language model in conjunction with the complete call content in the subsequent comprehensive quality inspection.
After completing phone data analysis, the customer service quality inspection rules formulated in section 20.1.2 and the normalized analysis results are input into Qwen3-8B together. Based on the complete call text, the model determines what needs customers raised, how customer service responded, and whether problems were resolved. Combined with information such as customer service emotions and tone, customer emotions and service response, and call interaction, it judges and scores each quality inspection rule.
For information such as course schedules and leave rules that require enterprise business rules to verify, if corresponding business standards are not provided, only whether the customer service representative provided a clear response is judged, not directly judging whether the content is correct, and noting in the report that "existing information cannot be verified."
Quality inspection is scored item by item according to the rules in section 20.1.2. Each quality inspection item, in addition to providing a score, also needs to explain the judgment result and main basis. When problems are found, corresponding call rounds, customer service representative's original words, or speech comprehensive analysis results can be cited as evidence, avoiding conclusions that only give "service attitude is poor" or "problem handling is inadequate" without basis.
The final customer service quality inspection report can use the following format:
Customer Service Quality Inspection Report

Comprehensive Score: XX/100
Quality Inspection Conclusion: ...

I. Overall Evaluation
...

II. Quality Inspection Results

1. Opening and Identity Statement: X/5
Judgment Result: ...
Main Basis: ...
Deduction Reason: ...

2. Demand Identification and Response Completeness: X/20
Judgment Result: ...
Main Basis: ...
Deduction Reason: ...

3. Information Accuracy and Risk Control: X/15
Judgment Result: ...
Main Basis: ...
Deduction Reason: ...

4. Problem Resolution and Promise Closure: X/15
Judgment Result: ...
Main Basis: ...
Deduction Reason: ...

5. Service Attitude and Professional Wording: X/15
Judgment Result: ...
Main Basis: ...
Deduction Reason: ...

6. Interruption and Call Rhythm: X/10
Judgment Result: ...
Main Basis: ...
Deduction Reason: ...

7. Customer Emotion and Service Recovery: X/10
Judgment Result: ...
Main Basis: ...
Deduction Reason: ...

8. Closing and Pending Item Confirmation: X/10
Judgment Result: ...
Main Basis: ...
Deduction Reason: ...

III. Main Issues
1. ...
2. ...

IV. Improvement Suggestions
1. ...
2. ...
Below, programs are written according to the technical solution above to gradually implement automated phone customer service quality inspection.
Install the required dependency libraries.
!pip3 install modelscope transformers accelerate
!pip3 install funasr qwen-asr qwen-omni-utils
!pip3 install soundfile scipy
Download the required models in advance so that local cache can be used directly during subsequent loading.
from modelscope import snapshot_download

snapshot_download("iic/speech_fsmn_vad_zh-cn-16k-common-pytorch")
snapshot_download("iic/speech_campplus_sv_zh-cn_16k-common")
snapshot_download("Qwen/Qwen3-ASR-0.6B")
snapshot_download("Qwen/Qwen3-ForcedAligner-0.6B")
snapshot_download("Qwen/Qwen3-4B")
snapshot_download("Qwen/Qwen3-8B")
snapshot_download("Qwen/Qwen2.5-Omni-3B")
After installation, uniformly import the dependencies needed for subsequent programs.
import os
import gc
import json
import torch
import soundfile as sf
from scipy.signal import resample_poly
from funasr import AutoModel
from qwen_asr import Qwen3ASRModel
from modelscope import AutoTokenizer, AutoModelForCausalLM, snapshot_download
from transformers import Qwen2_5OmniForConditionalGeneration, Qwen2_5OmniProcessor
from qwen_omni_utils import process_mm_info
Test audio file:
Convert input recordings uniformly to 16 kHz mono WAV audio.
def preprocess_audio(audio_path, output_path="./customer_service/preprocessed.wav",
                     target_sr=16000):
    audio, sr = sf.read(audio_path)

    # Convert to mono
    if audio.ndim > 1:
        audio = audio.mean(axis=1)

    # Resample
    if sr != target_sr:
        audio = resample_poly(audio, target_sr, sr)
        sr = target_sr

    # Save as unified wav format
    os.makedirs(os.path.dirname(output_path), exist_ok=True)
    sf.write(output_path, audio, sr)

    return output_path
Use FunASR to combine FSMN-VAD and CAM++ to obtain voice segments and time information for different speakers.
def analyze_speakers(audio_path):
    model = AutoModel(
        model="paraformer-zh",
        vad_model="fsmn-vad",
        punc_model="ct-punc",
        spk_model="cam++",
        device="cuda:0"
    )

    result = model.generate(
        input=audio_path,
        batch_size_s=60,
        sentence_timestamp=True
    )

    sentence_info = result[0].get("sentence_info", [])
    segments = []

    for item in sentence_info:
        segments.append({
            "speaker": f"spk{item['spk']}",
            "start": round(item["start"] / 1000, 2),
            "end": round(item["end"] / 1000, 2)
        })

    del model
    gc.collect()
    torch.cuda.empty_cache()

    return segments
Use Qwen3-ASR-0.6B to recognize the entire recording, and obtain timestamps for recognized text through ForcedAligner.
def analyze_asr(audio_path, language="Chinese"):
    model_path = "Qwen/Qwen3-ASR-0.6B"
    aligner_path = "Qwen/Qwen3-ForcedAligner-0.6B"
    model = Qwen3ASRModel.from_pretrained(
        model_path, dtype=torch.bfloat16, device_map="cuda:0",
        max_inference_batch_size=1, max_new_tokens=2048,
        forced_aligner=aligner_path,
        forced_aligner_kwargs={"dtype": torch.bfloat16, "device_map": "cuda:0"}
    )

    result = model.transcribe(
        audio=audio_path, language=language, return_time_stamps=True
    )[0]

    segments = []
    if result.time_stamps:
        for item in result.time_stamps:
            segments.append({
                "start": round(item.start_time, 2), "end": round(item.end_time, 2),
                "text": item.text.strip()
            })

    output = {
        "language": result.language,
        "text": result.text.strip(),
        "segments": segments
    }

    del model
    gc.collect()
    torch.cuda.empty_cache()
    return output
Use Qwen3-4B to determine roles based on dialogue content of different speakers, converting speaker numbers to "customer service" and "customer".
def identify_speaker_roles(segments):
    speaker_texts = {}
    for seg in segments:
        speaker_texts.setdefault(seg["speaker"], []).append(seg["text"])

    speaker_text = "\n".join(
        f"{speaker}:{''.join(texts)[:1000]}"
        for speaker, texts in speaker_texts.items()
    )

    model_name = "Qwen/Qwen3-4B"
    tokenizer = AutoTokenizer.from_pretrained(model_name)
    model = AutoModelForCausalLM.from_pretrained(
        model_name, torch_dtype=torch.bfloat16, device_map="cuda:0"
    )

    prompt = f"""The following is the dialogue content of different speakers in a customer service call from a language training institution.
Please determine the role of each speaker based on the dialogue content, marking the institution's customer service as "Customer Service" and the party receiving service as "Customer".

【Dialogue Content】
{speaker_text}

Only return JSON, for example:
{{"spk0": "Customer", "spk1": "Customer Service"}}
Do not output other content."""

    messages = [{"role": "user", "content": prompt}]
    text = tokenizer.apply_chat_template(
        messages, tokenize=False, add_generation_prompt=True, enable_thinking=False
    )
    inputs = tokenizer(text, return_tensors="pt").to(model.device)
    outputs = model.generate(**inputs, max_new_tokens=128)
    outputs = outputs[:, inputs.input_ids.shape[1]:]
    role_map = json.loads(tokenizer.decode(outputs[0], skip_special_tokens=True)

    for seg in segments:
        seg["speaker"] = role_map.get(seg["speaker"], seg["speaker"])

    del model, tokenizer
    gc.collect()
    torch.cuda.empty_cache()
    return segments
Now that call text with roles and time information has been obtained, the next step is to use Qwen2.5-Omni-3B in conjunction with phone recordings to further analyze customer service emotions and tone, customer emotions and service response, and interactions between both parties.
For longer phone recordings, directly inputting the complete audio into the model at once would occupy considerable video memory. Based on the call turns obtained earlier, the audio is segmented not by direct fixed-time truncation, but by waiting for the current customer service turn to end after reaching the specified length, so that each segment maintains complete conversation content as much as possible. Qwen2.5-Omni-3B is loaded only once, analyzing each audio segment sequentially, and finally organizing results according to corresponding time ranges.
The implementation code is as follows:
def split_audio_by_conversation(
    audio_path,
    segments,
    max_seconds=30,
    output_dir="./customer_service/audio_segments"
):
    audio, sr = sf.read(audio_path)
    os.makedirs(output_dir, exist_ok=True)

    groups = []
    current = []
    start_time = segments[0]["start"]

    # Segment by complete conversation, waiting for current customer service turn to end after reaching specified length
    for seg in segments:
        current.append(seg)

        if seg["end"] - start_time >= max_seconds and seg["speaker"] == "Customer Service":
            groups.append(current)
            current = []
            start_time = seg["end"]

    if current:
        groups.append(current)

    results = []

    # Extract audio based on time range of each conversation group
    for i, group in enumerate(groups):
        start = group[0]["start"]
        end = group[-1]["end"]

        segment_audio = audio[int(start * sr):int(end * sr)]
        output_path = os.path.join(output_dir, f"segment_{i + 1}.wav")
        sf.write(output_path, segment_audio, sr)

        results.append({
            "path": output_path,
            "start": start,
            "end": end,
            "segments": group
        })

    return results

def build_segment_transcript(segments):
    # Generate call text corresponding to current audio segment
    return "\n".join(
        f"Turn {seg['turn_id']} [{seg['speaker']}] "
        f"{seg['start']:.2f}-{seg['end']:.2f} seconds: {seg['text']}"
        for seg in segments
    )

def format_audio_analysis(results):
    # Organize speech analysis results of each segment by time range
    return "\n\n".join(
        f"{item['start']:.2f}-{item['end']:.2f} seconds speech comprehensive analysis results:\n"
        f"{item['analysis']}"
        for item in results
    )

def analyze_audio(audio_path, segments, max_seconds=30):
    # Segment long audio by complete conversation
    audio_segments = split_audio_by_conversation(
        audio_path,
        segments,
        max_seconds=max_seconds
    )

    # Model is loaded only once, analyzing all audio segments sequentially
    model_path = snapshot_download("Qwen/Qwen2.5-Omni-3B")
    processor = Qwen2_5OmniProcessor.from_pretrained(model_path)
    model = Qwen2_5OmniForConditionalGeneration.from_pretrained(
    model_path,
    torch_dtype=torch.bfloat16,
    device_map="cuda:0",
    enable_audio_output=False
)

    analysis_results = []

    for i, item in enumerate(audio_segments):
        print(
            f"Speech comprehensive analysis {i + 1}/{len(audio_segments)}: "
            f"{item['start']:.2f}-{item['end']:.2f} seconds"
        )

        transcript = build_segment_transcript(item["segments"])

        prompt = f"""
This is a customer service call recording from a language training institution. Please analyze the speech performance in this call based on the recording and corresponding call text.

【Call Text】
{transcript}

Please focus on analyzing the following content:

1. Customer Service Emotions and Tone
Analyze the overall emotions and service tone of the customer service representative, determining whether there is obvious impatience, perfunctoriness, blaming customers, or stiff tone.

2. Customer Emotions and Service Response
Analyze the main emotions and changes of the customer. If the customer shows significant negative emotions such as dissatisfaction, anxiety, or anger, determine whether the customer service representative provided appropriate explanations, responses, or appeasement.

3. Call Interaction
Based on the actual speaking order and simultaneous speaking situations in the actual speech, determine whether the customer service representative has obvious interruptions or customer interruptions, and whether there are other obvious issues affecting communication.

Only analyze based on actual recordings and provided call text; do not guess issues without evidence.

Please output in the following format:

Customer Service Emotions and Tone:
Emotional Expression: ...
Service Tone: ...
Abnormal Situations: ...

Customer Emotions and Service Response:
Customer Emotions: ...
Emotional Changes: ...
Service Response: ...

Call Interaction:
Interrupting: ...
Customer Interruptions: ...
Other Abnormalities: ...

Analysis Notes: ...
"""

        conversation = [{
            "role": "user",
            "content": [
                {"type": "audio", "audio": item["path"]},
                {"type": "text", "text": prompt}
            ]
        }]

        text = processor.apply_chat_template(
            conversation,
            add_generation_prompt=True,
            tokenize=False
        )

        audios, images, videos = process_mm_info(
            conversation,
            use_audio_in_video=False
        )

        inputs = processor(
            text=text,
            audio=audios,
            images=images,
            videos=videos,
            return_tensors="pt",
            padding=True
        ).to(model.device)

        with torch.no_grad():
            output = model.generate(
                **inputs,
                use_audio_in_video=False,
                return_audio=False,
                max_new_tokens=500
            )

        output = output[:, inputs.input_ids.shape[1]:]

        analysis = processor.batch_decode(
            output,
            skip_special_tokens=True,
            clean_up_tokenization_spaces=False
        )[0]

        analysis_results.append({
            "start": item["start"],
            "end": item["end"],
            "analysis": analysis
        })

        # Release intermediate variables after each segment inference, model continues to be retained
        del inputs, output, audios, images, videos
        gc.collect()
        torch.cuda.empty_cache()

    # Release model after all segments are processed
    del model, processor
    gc.collect()
    torch.cuda.empty_cache()

    return format_audio_analysis(analysis_results)
Organize analysis results from each module into a unified text format.
def format_analysis_result(transcript, audio_analysis):
    result = f"""
【Call Transcription】
{transcript}

【Information Verification Note】
This analysis did not provide enterprise business rules or standard answers.
For business information such as course schedules and leave rules, only whether the customer service representative provided a clear response can be judged,
and the accuracy of the content cannot be verified.

【Speech Comprehensive Analysis】
{audio_analysis}
"""
    return result.strip()
Input the normalized analysis results together with the customer service quality inspection rules formulated in section 20.1.2 into Qwen3-8B, allowing the model to comprehensively analyze call content and various analysis results, complete quality inspection scoring, and generate reports.
def generate_qc_report(analysis_text, qc_rules):
    model_name = "Qwen/Qwen3-8B"

    tokenizer = AutoTokenizer.from_pretrained(model_name)
    model = AutoModelForCausalLM.from_pretrained(
        model_name,
        torch_dtype=torch.bfloat16,
        device_map="cuda:0"
    )

    prompt = f"""
You are a customer service quality inspector at a language training institution. Please strictly follow the customer service quality inspection rules to complete comprehensive quality inspection based on phone analysis results and generate a quality inspection report.

【Customer Service Quality Inspection Rules】
{qc_rules}

【Phone Analysis Results】
{analysis_text}

【Quality Inspection Requirements】
1. Inspect item by item according to the 8 quality inspection items, judging only based on the provided phone analysis results; do not guess or supplement information not provided. Each judgment and deduction needs to have a clear basis.
2. Apply the principle of strict scoring. When there are no clear issues, no deductions are made; after finding clear issues, deductions should be made sufficiently based on the severity of the problem. Issues that clearly violate quality inspection rules, affect customer experience, or bring business risks should have significant deductions; do not reduce penalties because the customer service representative's overall performance is acceptable, nor should only 1-2 points be deducted as symbolic punishment.
3. For information such as course schedules and leave rules that require enterprise business rules to verify, if corresponding evidence is not provided, mark as "existing information cannot be verified" and do not judge correctness on your own. For matters such as learning outcomes that cannot be guaranteed, if the customer service representative uses expressions such as "guarantee", "definitely can", "certainly will" to make deterministic promises, judge as improper promises and make significant deductions.
4. Service attitude, professional wording, and problem resolution should be judged in conjunction with call text; customer service emotions, customer emotions, and speech performance such as interruptions and customer interruptions should be judged in conjunction with speech comprehensive analysis results. Normal speech emotion cannot override clearly existing improper expressions in text.
5. Each quality inspection item should be judged according to its corresponding inspection content; do not add requirements not stipulated in quality inspection rules, nor classify problems into unrelated quality inspection items. In principle, the same problem should not be deducted repeatedly; if the same behavior indeed affects different quality inspection items, corresponding bases should be explained separately.
6. After completing all quality inspection items, check whether item scores, comprehensive score, and quality inspection conclusion are consistent. The comprehensive score must equal the sum of the 8 quality inspection item scores.

【Quality Inspection Conclusion】
Determine the quality inspection conclusion based on the comprehensive score:
- 95-100 points: Excellent
- 90-94 points: Good
- 80-89 points: Average
- Below 80 points: Poor

【Output Format】
Please output in standard Markdown format; do not escape Markdown symbols.

# Customer Service Quality Inspection Report

## I. Comprehensive Results
- Comprehensive Score: XX/100
- Quality Inspection Conclusion: Excellent/Good/Average/Poor
- Overall Evaluation: Briefly summarize the customer service quality of this call in no more than 3 sentences.

## II. Quality Inspection Item Results

### 1. Opening and Identity Statement (X/5)
- Judgment Result: ...
- Main Basis: ...
- Deduction Reason: None/Specific reason

### 2. Demand Identification and Response Completeness (X/20)
- Judgment Result: ...
- Main Basis: ...
- Deduction Reason: None/Specific reason

### 3. Information Accuracy and Risk Control (X/15)
- Judgment Result: ...
- Main Basis: ...
- Deduction Reason: None/Specific reason

### 4. Problem Resolution and Promise Closure (X/15)
- Judgment Result: ...
- Main Basis: ...
- Deduction Reason: None/Specific reason

### 5. Service Attitude and Professional Wording (X/15)
- Judgment Result: ...
- Main Basis: ...
- Deduction Reason: None/Specific reason

### 6. Interruption and Call Rhythm (X/10)
- Judgment Result: ...
- Main Basis: ...
- Deduction Reason: None/Specific reason

### 7. Customer Emotion and Service Recovery (X/10)
- Judgment Result: ...
- Main Basis: ...
- Deduction Reason: None/Specific reason

### 8. Closing and Pending Item Confirmation (X/10)
- Judgment Result: ...
- Main Basis: ...
- Deduction Reason: None/Specific reason

## III. Main Issues
Only list main issues with clear evidence in this call. If there are no obvious issues, write "No obvious issues found."

## IV. Improvement Suggestions
Provide specific and concise improvement suggestions for main issues. If there are no obvious issues, brief maintenance suggestions can be given.
"""

    messages = [{"role": "user", "content": prompt}]

    text = tokenizer.apply_chat_template(
        messages,
        tokenize=False,
        add_generation_prompt=True,
        enable_thinking=False
    )

    inputs = tokenizer(
        text,
        return_tensors="pt"
    ).to(model.device)

    with torch.no_grad():
        outputs = model.generate(
            **inputs,
            max_new_tokens=4096
        )

    outputs = outputs[:, inputs.input_ids.shape[1]:]

    report = tokenizer.decode(
        outputs[0],
        skip_special_tokens=True
    )

    del model, tokenizer
    gc.collect()
    torch.cuda.empty_cache()

    return report
The main program also needs to define several auxiliary functions for aligning ASR text with speaker segments according to time, generating complete call text, and saving quality inspection reports.
def merge_asr_speakers(asr_segments, speaker_segments):
    results = [{"turn_id": i + 1, "speaker": seg["speaker"], "start": seg["start"], "end": seg["end"], "texts": []} for i, seg in enumerate(speaker_segments)]

    for item in asr_segments:
        best_index, best_overlap = None, 0
        for i, seg in enumerate(speaker_segments):
            overlap = min(seg["end"], item["end"]) - max(seg["start"], item["start"])
            if overlap > best_overlap:
                best_overlap, best_index = overlap, i
        if best_index is not None and best_overlap > 0:
            results[best_index]["texts"].append(item["text"])

    results = [item for item in results if item["texts"]]

    for i, item in enumerate(results):
        item["turn_id"] = i + 1
        item["text"] = "".join(item.pop("texts")

    return results

def build_transcript(segments):
    return "\n".join(
        f"Turn {seg['turn_id']} [{seg['speaker']}] {seg['start']:.2f}-{seg['end']:.2f} seconds: {seg['text']}"
        for seg in segments
    )

def save_report(report, output_path="./customer_service/customer_service_quality_report.md"):
    os.makedirs(os.path.dirname(output_path), exist_ok=True)
    with open(output_path, "w", encoding="utf-8") as f:
        f.write(report)
    return output_path

QC_RULES = """
Phone customer service quality inspection rules, total score 100 points:

1. Opening and Identity Statement (5 points)
Check whether to proactively greet, state the institution and personal identity, and ask about customer needs.

2. Demand Identification and Response Completeness (20 points)
Check whether issues raised by customers are identified and responded to effectively item by item.

3. Information Accuracy and Risk Control (15 points)
Check whether customer service representatives fabricate uncertain information, whether there are improper promises about course effects, learning outcomes, etc.
Pay special attention to guarantee expressions related to learning outcomes. Learning outcomes are affected by multiple factors such as student foundation, learning investment, and practice situations; customer service representatives must not make deterministic guarantees about learning outcomes.
If customer service representatives use deterministic expressions such as "guarantee", "definitely can", "certainly will", or clearly promise to achieve certain learning outcomes within a fixed time period, judge as improper promises and deduct points.

For example, expressions such as "Stick to it for a month and you can basically speak English fluently" and "This effect can be guaranteed" belong to improper promises about learning outcomes.
4. Problem Resolution and Promise Closure (15 points)
Check whether core customer problems are resolved; when immediate resolution is not possible, whether follow-up processing methods are explained.

5. Service Attitude and Professional Wording (15 points)
Check whether there are expressions of impatience, blame, perfunctoriness, insults, or shirking responsibility.

6. Interruption and Call Rhythm (10 points)
Check whether there is frequent interruption of customers, interrupting, or abnormal rhythms that significantly affect communication.

7. Customer Emotion and Service Recovery (10 points)
Check whether customers show significant negative emotions, whether customer service representatives explain and appease in a timely manner.

8. Closing and Pending Item Confirmation (10 points)
Check whether to end politely and confirm unfinished items.
"""

def main(audio_path, report_save_path):
    result = {}

    # Audio preprocessing
    audio_path = preprocess_audio(audio_path)
    print("Audio preprocessing completed ✅️")

    # Speaker analysis
    speaker_segments = analyze_speakers(audio_path)
    print("Speaker analysis completed ✅️")

    # Speech recognition
    asr_result = analyze_asr(audio_path)
    print("Speech recognition completed ✅️")

    # Text and speaker alignment
    segments = merge_asr_speakers(asr_result["segments"], speaker_segments)
    print("Text and speaker alignment completed ✅️")

    # Speaker role identification
    segments = identify_speaker_roles(segments)
    result["transcript"] = build_transcript(segments)
    print("Speaker role identification completed ✅️")

    # Speech comprehensive analysis
    result["audio_analysis"] = analyze_audio(audio_path, segments)
    print("Speech comprehensive analysis completed ✅️")

    # Summary analysis results
    analysis_text = format_analysis_result(result["transcript"], result["audio_analysis"])
    print("Analysis result summary completed ✅️")

    # Comprehensive quality inspection
    report = generate_qc_report(analysis_text, QC_RULES)
    print("Comprehensive quality inspection completed ✅️")

    # Save and output results
    report_path = save_report(report, report_save_path)
    print("\n========== Normalized Analysis Results ==========\n")
    print(analysis_text)
    print("\n========== Customer Service Quality Inspection Report ==========\n")
    print(report)
    print(f"\nQuality inspection report saved to: {report_path}")
    return report
Input test audio for customer service quality inspection testing.
if __name__ == "__main__":
    main(
    audio_path="./customer_service/customer_service_call_recording.wav",
    report_save_path="./customer_service/customer_service_quality_report.md"
    )
...
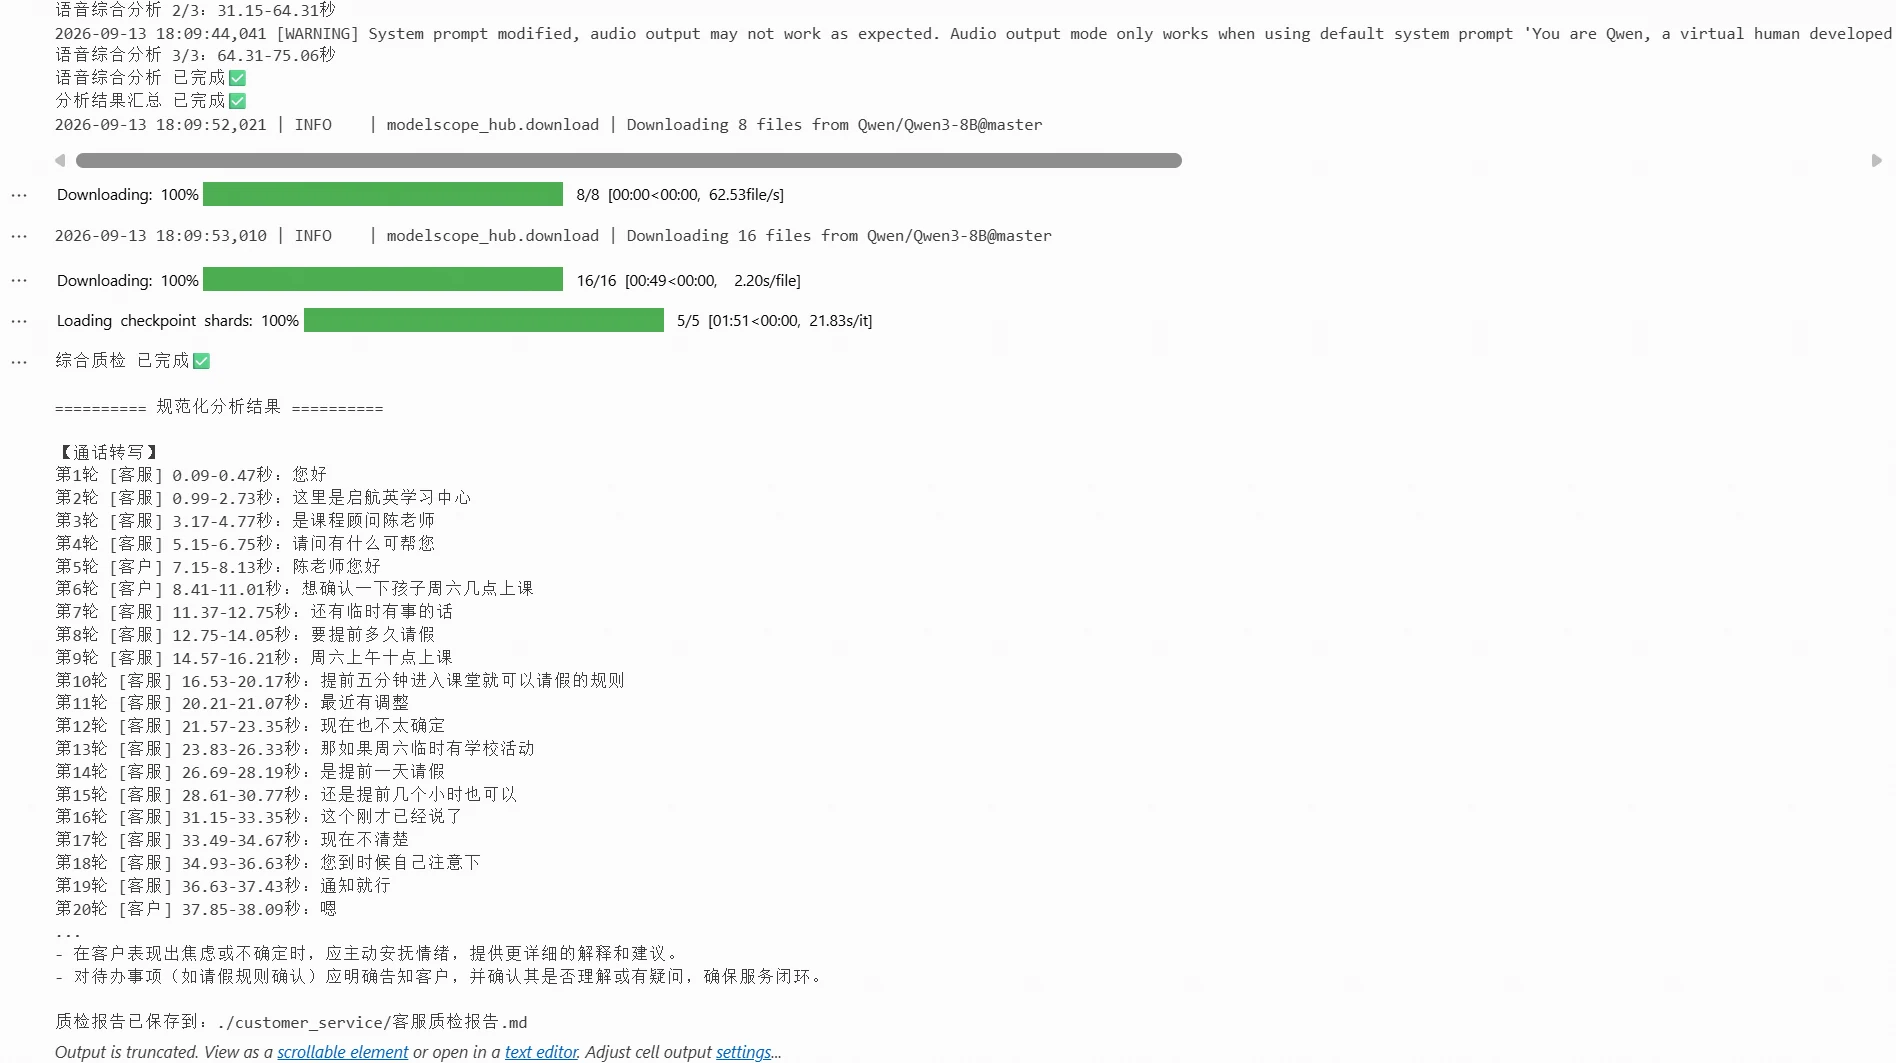
The generated quality inspection report is as follows:
The code and related files for this chapter can be found at: https://www.modelscope.cn/gallery/liucong/ae27f822-4e85-4baa-be70-74f73f07799a